Apache SeaTunnel: A Multi-Engine Data Integration Tool with a Connector-Heavy Approach
SeaTunnel is a multimodal, high-performance, distributed, massive data integration tool.
At a glance
- What is it?
- Apache SeaTunnel is a distributed data integration framework that supports batch, streaming, and CDC workloads across more than 160 connectors. This review examines its architecture, deployment options, and the trade-offs of its multi-engine design.
- Who is it for?
- Adopt Apache SeaTunnel if you need a single tool that spans batch, streaming, and CDC across many source and sink systems, and if you are comfortable running a Java-based distributed engine or integrating with an existing Flink or Spark cluster. Do not choose it if your workloads are simple single-table copies that do not justify the operational overhead of a distributed system, or if you require a mature ecosystem of transforms beyond the built-in set.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
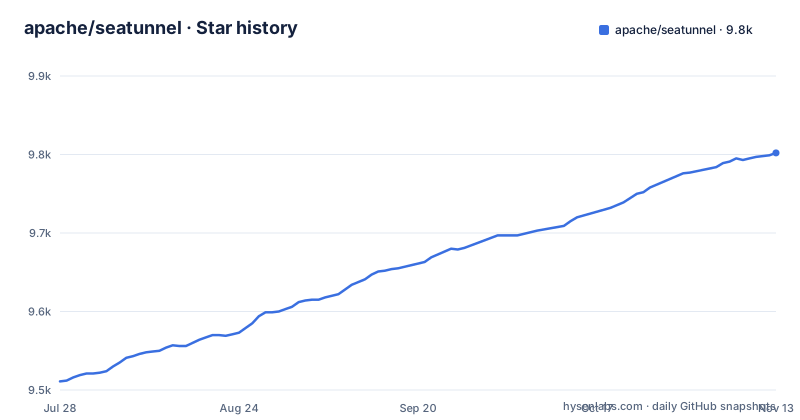
- apache/seatunnel9,802 ★ · +291
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| apache/seatunnel | 9.5k | 9.8k |
291 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What SeaTunnel Actually Solves
SeaTunnel addresses a common operational problem: moving data between many different systems without writing custom code for each pair. The README lists diverse data sources, multimodal integration (video, images, binary files, structured and unstructured text), and complex synchronization scenarios such as real-time, CDC, and full database synchronization. The target user is a data engineering team that manages dozens of pipelines and wants one framework to handle them. The project claims over 160 connectors, which is a strong draw for organizations with heterogeneous storage and message systems. However, the README does not specify which connectors are mature or how many are community-maintained. That matters because connector quality varies widely in open source projects, and a connector that exists on paper may not handle edge cases in your specific database version.
The Multi-Engine Architecture: Zeta, Flink, and Spark
SeaTunnel does not force you onto a single runtime. It supports three execution engines: SeaTunnel Zeta Engine, Flink, and Spark. The Zeta engine is the project's own engine. The other two are integrations that let you run the same connector code on existing clusters. This is both a strength and a complication. On the positive side, teams that already run Flink or Spark can adopt SeaTunnel without introducing a new runtime. On the negative side, the abstraction layer must reconcile different checkpointing, state management, and fault-tolerance models. The README lists the distributed snapshot algorithm as a key feature without tying it to an engine, and does not explain how consistency guarantees differ when you run on Flink or Spark. Engineers should assume that behavior varies by engine and test accordingly.
Getting Started: Deployment and Configuration
The official getting-started path is to download a distribution from the website and then pick an engine. The README links to a local deployment guide for Zeta and to cluster deployment documentation. It also links to Spark and Flink quick-start guides. The typical workflow is to define a job configuration file that specifies source, transform, and sink connectors, then submit it to the chosen engine. The README does not show a concrete config example, so you will need to consult the documentation for syntax. The project is Java-based, so you need a JVM. For Zeta, you likely run a standalone server or a cluster of nodes. For Flink or Spark, you deploy SeaTunnel as a job submission layer on top of those clusters. The release cadence is active: version 3.0.0 came out on 29 September 2026, following 2.3.13 in March 2026 and 2.3.12 in September 2025. That suggests steady maintenance, but it also means you should pin a version and plan for upgrades.
Connector Coverage and Multimodal Claims
The connector list is the main selling point. The README claims over 160 connectors and links source, sink and transform connector lists on the project site. The README emphasizes multimodal data integration, including video and images, which is unusual for a data integration tool. Most tools in this space focus on structured tables and JSON. The claim that SeaTunnel can handle binary files and video is plausible because a connector can read bytes from a source and write them to a sink without parsing. However, the README does not describe any special handling for video codecs or image formats. For video, images and binary files it only points to the documentation for detailed instructions. That is a thin answer. If you need to extract metadata from video or transform images in-flight, SeaTunnel likely is not the right tool.
Resource Efficiency and JDBC Multiplexing
One concrete feature stands out: JDBC multiplexing and log parsing for multi-table and multi-database synchronization. The README claims this minimizes computing resources and JDBC connections for real-time synchronization. This is a meaningful advantage for database-to-database pipelines. Many tools open one JDBC connection per table, which quickly exhausts connection pools. SeaTunnel's approach of reusing connections across tables can reduce overhead. The distributed snapshot algorithm is another specific mechanism that aims to prevent data loss or duplication during synchronization. The README mentions data quality and monitoring as features, but it does not give details on how they work. If data quality checks are important to your pipelines, you will need to read the documentation to see whether they are built-in or require additional configuration.
Limitations and Failure Modes
The README lists notable users such as JP Morgan, S7, JDT, Bytedance, and Tencent Cloud, but it does not provide details on scale or use cases. That is typical for a project site, but it means you cannot verify production readiness from the README alone. Another limitation is the multi-engine abstraction. If you choose Flink or Spark, you inherit their version-specific behaviors, and SeaTunnel's connector code may not map cleanly to all features of those engines. The README does not mention version compatibility matrices. A third issue is the transform connector ecosystem. The README lists transform connectors, but it does not enumerate them. For complex ETL transformations, you may find the built-in set insufficient and need to write custom Java code. Finally, the snapshot algorithm is described only at a high level, and there is no benchmark data in the README. You should run your own load tests.
Alternatives and How They Differ
The closest alternative is Apache NiFi, which also provides a visual flow-based programming model for data routing and transformation. NiFi runs as a standalone Java application and emphasizes fine-grained flow control, backpressure, and provenance tracking. SeaTunnel, by contrast, is engine-agnostic and focuses on high-throughput batch and streaming synchronization. Another alternative is Debezium, which specializes in CDC from databases. Debezium is a library and set of connectors that you embed in Kafka Connect or run with Flink. SeaTunnel includes CDC support, but it is not CDC-only; it covers a broader range of sources and sinks. If your primary need is reliable change data capture from a few databases, Debezium may give you more mature CDC semantics. SeaTunnel's advantage is that it unifies CDC with regular batch and streaming in one tool, reducing the number of frameworks you need to operate.
Maintenance, Upgrades, and License
SeaTunnel is an Apache project, licensed under Apache-2.0, which means you can use it commercially without restrictions beyond attribution. The project is active, with v3.0.0 released on 2026-09-29 and 2.3.13 in March 2026, and the default branch is named dev, indicating ongoing development. The README points to a contribution guide and a developer setup page, which suggests a structured process for code changes. Upgrade cost is a real consideration. Each minor release may introduce changes to connector APIs or engine integrations. The README does not provide a migration guide, so you should review release notes for each version before upgrading. The project also maintains a separate repository for tools, including an MCP server, which indicates an expanding ecosystem but also more components to track. For a production deployment, you should budget time for testing upgrades against your specific connectors and engine versions.
Editorial conclusion
Adopt Apache SeaTunnel if you need a single tool that spans batch, streaming, and CDC across many source and sink systems, and if you are comfortable running a Java-based distributed engine or integrating with an existing Flink or Spark cluster. Do not choose it if your workloads are simple single-table copies that do not justify the operational overhead of a distributed system, or if you require a mature ecosystem of transforms beyond the built-in set. Before committing, verify the availability and maintenance status of the specific connectors you need, test the Zeta engine's snapshot and checkpoint behavior under your data volumes, and confirm that the multi-engine abstraction does not introduce version conflicts with your existing Flink or Spark deployments.
Frequently asked questions
What is Apache SeaTunnel?
A Java data integration tool that synchronizes large volumes of data between systems, covering real-time, CDC and full database loads. It offers over 160 connectors and runs a job on the SeaTunnel Zeta Engine, Flink or Spark.
Is SeaTunnel a replacement for Flink?
Not in the runtime sense. Flink is one of three execution engines SeaTunnel supports, alongside its own Zeta engine and Spark, so an existing Flink deployment can keep its runtime and use SeaTunnel for the source and sink side.
How does SeaTunnel compare with NiFi?
The README makes no comparison to NiFi and publishes no figures either tool could be measured against. Its own engine list is SeaTunnel Zeta, Flink and Spark, and its connectors are described as numbering over 160 systems.
How does SeaTunnel compare with Debezium?
No comparison exists in this repository. What SeaTunnel states about itself is that CDC and full database synchronization are supported beside real-time streaming, with a distributed snapshot algorithm for consistency and JDBC multiplexing for multi-table and multi-database sync.
Is SeaTunnel an alternative to DataX?
The README does not name DataX at all. What it describes is a distributed tool whose adaptable connectors serve both batch and stream, numbering over 160, running on Zeta, Flink or Spark.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/apache-seatunnel)Star history chart for your README
[](https://hysenlabs.com/projects/apache-seatunnel)Was this useful?