MemOS 2.0: A Memory Operating System for Agents That Stores, Retrieves, and Evolves
Self-evolving memory OS for LLM & AI Agents: ultra-persistent memory, hybrid-retrieval, and cross-task skill reuse, with 35.24% token savings.
At a glance
- What is it?
- MemOS is a memory layer for LLM agents, offering a unified API, hybrid retrieval, and skill reuse. It claims significant token savings and strong benchmark scores, but self-hosting requires Neo4j and Qdrant.
- Who is it for?
- Adopt MemOS if you are building an agent that needs persistent, inspectable memory and you can accept the operational overhead of self-hosting or the data residency trade-off of the cloud API. Skip it if your use case is a simple key-value store.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
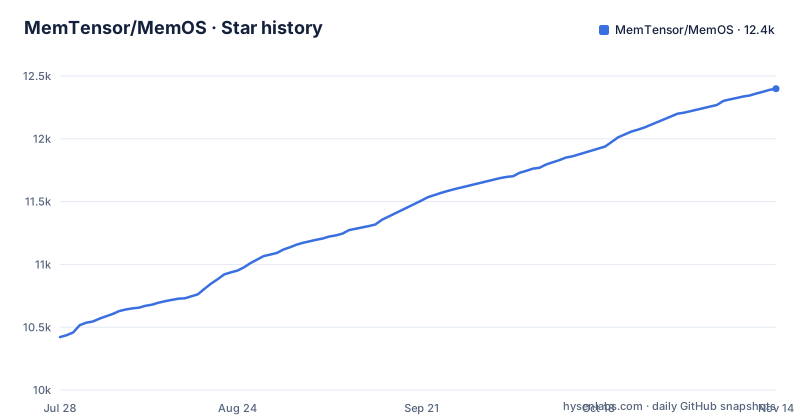
- MemTensor/MemOS12,399 ★ · +1,978
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| MemTensor/MemOS | 10.4k | 12.4k |
1,978 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What MemOS Actually Solves
MemOS targets a specific pain: LLM agents forget. A typical agent has a context window, and once that fills, prior turns, user preferences, and learned skills vanish. MemOS is a memory operating system that unifies store, retrieve, and manage operations for long-term memory. The README frames it as giving your agent persistent memory and the ability to grow. The intended users are developers building AI assistants, customer support systems that recall past tickets, personalized agents, and multi-agent setups that need shared or isolated memory. It is not a general-purpose database. It is a memory layer designed for agent workflows, with an API that treats memory as a graph, not a black-box embedding store. That distinction matters: you can inspect and edit what the agent remembers, which is a real advantage over a vector store where you only get opaque similarity hits.
The Architecture: Cubes, Scheduler, and Feedback
The repository describes a multi-layered system. At the core is a unified memory API that handles add, retrieve, edit, and delete operations. Memory is structured as a graph, which makes it inspectable and editable by design. On top of that sits multi-modal support: text, images, tool traces, and personas are retrieved and reasoned together. The knowledge base side uses what they call multi-cube management. Each cube is a composable memory unit, so you can isolate memory per user, project, or agent, then dynamically compose cubes as needed. Ingestion is asynchronous via MemScheduler, which the README claims delivers millisecond-level latency under high concurrency. That is a production-oriented design choice: you do not block the agent loop on memory writes. There is also a feedback and correction mechanism. You can give natural-language feedback to correct, supplement, or replace an existing memory. This is not a static store. It is designed to evolve, which aligns with the self-evolving memory claim in the description.
Getting Started: Four Entry Points, Different Trade-offs
MemOS offers four ways in. The cloud API is the fastest: sign up, get an API key that starts with mpg-, and call endpoints like /add/message and /search/memory. The README shows a Python example using requests, with a base URL of https://memos.memtensor.cn/api/openmem/v1. That path requires no infrastructure. Self-hosting is the opposite: you need Neo4j and Qdrant, then run docker compose up. That is a significant operational commitment. The cloud plugin for OpenClaw uses the hosted service, so no infra. The local plugin targets DeepSeek Harness, Hermes Agent, or OpenClaw, and runs on a local SQLite database with zero cloud dependency. The local plugin is installed via npm install plus agent-specific setup. The choice is clear: if you want control and offline operation, the local plugin is the path. If you want zero ops, the cloud API is the path. The self-host option is for teams that already run Neo4j and Qdrant, because adding those to a stack just for memory is heavy.
Hybrid Retrieval and Skill Reuse: The Mechanism
The local plugin description mentions hybrid retrieval using FTS5 and vector search. That is a concrete mechanism: full-text search catches exact terms, vector search catches semantic similarity. The README also describes tiered skill evolution, with L1 traces, L2 policies, L3 world models, and crystallized Skills. This is a hierarchy where raw interactions become policies, then world models, then reusable skills. The cross-task skill reuse is the payoff: an agent that learns a skill in one task can apply it to another. The cloud plugin for OpenClaw claims 72% lower token usage, which is a different number. These are vendor-provided metrics, not independent measurements. The mechanism is plausible, but the exact savings will depend on your workload and retrieval quality.
Benchmark Claims: Read the Fine Print
The README lists scores on LoCoMo (88.83), LongMemEval (89.20), PersonaMem v2 (40.58), HaluMem (80.91), BEAM-10M (56.75), GDPVal (62.07), LiveCodeBench (64.96), OmniMath (61.00), SWE-Bench (38.46), and BrowseComp-Plus (23.85). These are evaluated via OmniMemEval, a separate repository. The numbers are not uniformly high. BrowseComp-Plus at 23.85 is low, and SWE-Bench at 38.46 is modest. The README also reports that OpenClaw improves from 36.63% to 50.87% task completion with MemOS. That is a meaningful jump, but it is a single integration. The benchmark methodology matters. OmniMemEval is a public repository, so you can inspect how the datasets are constructed and whether the comparisons are fair. Treat these numbers as directional, not absolute.
Limitations and Failure Modes
The self-hosting requirement is the most obvious limitation. Neo4j and Qdrant are not trivial to operate. If you do not already run them, the operational cost is high. The cloud API avoids that, but then your data lives on MemOS Cloud, which may be a problem for regulated industries or privacy-sensitive users. The local plugin is 100% on-device, but it is tied to specific agent frameworks: DeepSeek Harness, Hermes, and OpenClaw. If you use a different agent, you are out of luck unless you build your own integration. Another failure mode is retrieval quality. Hybrid retrieval is only as good as the embedding model and the FTS5 configuration. If the retrieval returns irrelevant memories, the agent will act on wrong context, which can be worse than no memory. The feedback mechanism helps, but it requires someone to actually give feedback. In an autonomous agent loop, that may not happen.
Alternatives: What Else Is Out There
The obvious alternative is to build memory yourself on a vector database like Qdrant or Pinecone, with a simple embedding pipeline. That approach gives you full control but requires you to handle deduplication and skill extraction yourself. MemOS packages those features, so you save development time. If you need cross-task skill reuse and multi-agent memory isolation, MemOS has more built-in structure.
Maintenance and License Implications
MemOS is licensed under Apache-2.0, which is permissive. You can use it commercially, modify it, and distribute it, as long as you preserve the license notice. That is a low-friction license for most companies. The maintenance cost depends on the entry point. The cloud API has zero maintenance, but you depend on the vendor's uptime and API stability. The local plugin has moderate maintenance: you need to update the npm package. The self-host option has the highest maintenance, because you must patch Neo4j and Qdrant, manage backups, and scale them. The release cadence is active: the latest core release is v2.0.34 on 2026-09-23, the local plugin shipped v2.0.21 on 2026-10-29, and the last push was on 2026-10-29. That suggests ongoing development, but it also means you should pin versions and test upgrades.
Editorial conclusion
Adopt MemOS if you are building an agent that needs persistent, inspectable memory and you can accept the operational overhead of self-hosting or the data residency trade-off of the cloud API. Skip it if your use case is a simple key-value store. Before committing, verify the benchmark methodology in OmniMemEval, test the local plugin with your specific agent framework, and confirm that the Apache-2.0 license covers your distribution model. The 35.24% token savings is a headline number, not a guarantee; measure it against your own workloads.
Frequently asked questions
what is memos
MemOS is a memory operating system for LLMs and AI agents from MemTensor, published as the Python package MemoryOS under the Apache-2.0 license. It unifies store, retrieve, and manage for long-term memory and exposes memory as a graph you can inspect and edit rather than a black-box embedding store.
how to install memos
Four routes are offered: a hosted Cloud API where you copy an API key starting with mpg- from the dashboard, self-hosting with docker compose up which needs Neo4j plus Qdrant, an OpenClaw plugin install, or the local plugin with npm install and agent-specific setup, which needs no infrastructure because it uses local SQLite.
how to use memos
The package requires Python 3.10 or newer, and the repository ships runnable examples per feature, including api, basic_modules, core_memories, mem_cube, mem_feedback, mem_mcp, mem_reader, mem_scheduler, and mem_agent. For a local API, the Makefile serve target runs uvicorn memos.api.server_api:app.
How do memos work?
A single API adds, retrieves, edits, and deletes memory, and memory can hold text, images, tool traces, and personas that are retrieved together in one system. Operations can run asynchronously through MemScheduler, and natural-language feedback can correct, supplement, or replace existing memories over time.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/memtensor-memos)Star history chart for your README
[](https://hysenlabs.com/projects/memtensor-memos)Was this useful?