LMDeploy: A Practical Look at Compression, Deployment, and Serving for LLMs
LMDeploy is a toolkit for compressing, deploying, and serving LLMs.
At a glance
- What is it?
- LMDeploy from the InternLM team is a Python toolkit that compresses, deploys, and serves large language models. It offers a TurboMind inference engine with persistent batching and KV cache quantization, but its performance claims and hardware support need careful verification before adoption.
- Who is it for?
- Adopt LMDeploy if you need a single toolkit for quantizing, deploying, and serving LLMs, especially if you target NVIDIA GPUs or Huawei Ascend and want both a high-performance C++ engine and a pure-Python engine for experimentation. Avoid it if your model is not on the supported list, and check which version PyPI carries, since wheel uploads resumed only after PyPI expanded LMDeploy's storage quota in April 2026.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
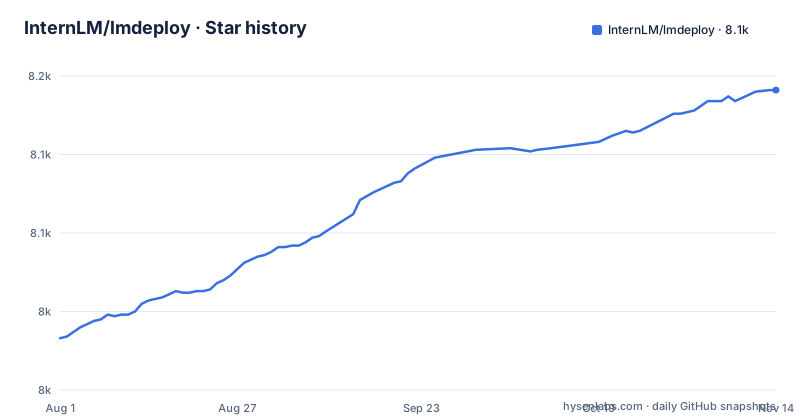
Star history
- InternLM/lmdeploy8,141 ★ · +158
| Repository | 2026-08-01 | 2026-11-14 |
|---|---|---|
| InternLM/lmdeploy | 8k | 8.1k |
158 Stars in the last 105 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What LMDeploy Actually Solves
LMDeploy is a toolkit for compressing, deploying, and serving large language models. The problem it addresses is the gap between training a model and putting it into production. You need to quantize weights to fit memory, serve multiple requests efficiently, and handle multimodal inputs without switching tools. LMDeploy bundles these steps into one Python package. The intended audience is engineers who run LLMs on their own hardware, not those using managed cloud APIs. The README emphasizes features like persistent batching (continuous batching), blocked KV cache, and tensor parallelism. These are standard concerns for anyone running a self-hosted inference service. The project is developed by the MMRazor and MMDeploy teams, which suggests a background in model compression and deployment tooling. That lineage is visible in the quantization support, which goes beyond simple weight rounding.
TurboMind vs. PyTorch Engine: Two Paths to Inference
LMDeploy offers two inference engines. The first is TurboMind, a C++-based engine that has been the project's performance workhorse since 2023. The README credits TurboMind with features like Paged Attention, Split-K decoding, and flash-attention2 support. The second is the PyTorch engine, introduced in January 2024 and developed entirely in Python. The README states this engine lowers the barrier for developers and enables rapid experimentation. That is a real trade-off. TurboMind is likely faster but harder to modify. The PyTorch engine is more accessible but may not match TurboMind's kernel-level optimizations. The existence of both engines means you have to choose. The documentation, referenced in the README, provides separate guides for each. For a production deployment, TurboMind seems the safer bet. For prototyping or adding a custom feature, the PyTorch engine is the one to start with.
Quantization: Weight-Only, KV Cache, and 4-Bit Inference
Quantization is a core part of LMDeploy. The README lists weight-only quantization, KV cache quantization, and 4-bit inference. The 4-bit inference is claimed to be 2.4x faster than FP16. The project supports AWQ for 4-bit weight quantization and, as of February 2026, supports llm-compressor 4-bit symmetric and asymmetric quantization. There is also online int8/int4 KV cache quantization, which reduces memory usage during inference. For engineers, the key takeaway is that quantization is not a single toggle. You have to choose which method fits your model and accuracy requirements. The README references detailed guides for w4a16 and KV quant, so the project expects you to read those before applying quantization.
Hardware and Model Support: Wide but Not Universal
LMDeploy supports NVIDIA GPUs, with TurboMind supporting MXFP4 from V100 onward. The PyTorch engine also supports Huawei Ascend, as noted in the 2024 news entry. The README lists support for many model families: Llama, Qwen, InternVL, DeepSeek, Mistral, Mixtral, and more. However, the supported models list is a separate document, and the README does not guarantee every version or variant works. For example, DeepSeek V3 and R1 are supported as of January 2025. The practical constraint is that you must check the supported models document before assuming your model works. A 2023 news entry also notes TurboMind support for Windows with tensor parallelism equal to 1 (tp=1).
Getting It Running: Install and Basic Commands
The README gives a direct install path: pip install lmdeploy. The April 2026 news notes that PyPI expanded the storage quota for LMDeploy, wheel uploads resumed, and v0.12.3 became available to install with pip install lmdeploy. The latest release on GitHub is v0.18.0, from September 2026. The README points to a Quick Start guide for actual commands, but the repository's structure suggests the typical flow: load a Hugging Face model, quantize it if needed, and then serve it via an API server. The README mentions an API server guide and a proxy server for multi-model, multi-machine deployments. For a concrete example, the README references loading HF models directly in TurboMind, which is a feature added in November 2023.
Limitations and Failure Modes
One limitation is the PyPI packaging history: the April 2026 news says wheel uploads resumed only after PyPI expanded LMDeploy's storage quota. Another limitation is the performance claims. The README says LMDeploy delivers up to 1.8x higher throughput than vLLM, and 1.5x the performance of vLLM on H800 for gpt-oss models. These are specific benchmarks, not general guarantees. In practice, your workload may not see that gain. Also, the project supports a wide range of models, but not all. If your model is not in the supported list, you have to wait for the project to add it or do custom work.
Comparing with vLLM: Different Strengths, Same Goal
The README repeatedly benchmarks against vLLM, so that is the natural alternative. vLLM is a popular open-source inference server with continuous batching and PagedAttention. LMDeploy offers the same core features, but adds a quantization toolkit and a PyTorch engine. The key difference is that vLLM focuses on serving, while LMDeploy covers compression as well. If you already use AWQ or llm-compressor for quantization, you might not need LMDeploy's quantization tools. But if you want a single project that handles both quantization and serving, LMDeploy is more integrated. The README claims LMDeploy is faster than vLLM in specific benchmarks, but those are vendor-claimed numbers. That distinction matters if your workflow starts with a raw Hugging Face model and ends with a quantized, served endpoint.
Maintenance and License: What You Need to Know
LMDeploy is licensed under Apache-2.0, which is permissive for commercial use. The repository is active, with recent releases v0.16.0 on 2026-08-19, v0.17.0 on 2026-09-01 and v0.18.0 on 2026-09-28. That cadence suggests ongoing maintenance. The paper acceptance to EuroSys 2027 indicates academic backing, which often correlates with long-term support. However, active development also means breaking changes. Upgrading between minor versions may require adjusting your configuration. The project has a documentation site and an issue tracker, which are standard for support. The maintenance cost is moderate: you need to track releases, check the supported models list, and re-benchmark after updates. The license allows you to modify the code, but if you fork it, you are on your own. For a production deployment, the monthly release cycle is a signal to pin a version and test upgrades in a staging environment before rolling out.
Editorial conclusion
Adopt LMDeploy if you need a single toolkit for quantizing, deploying, and serving LLMs, especially if you target NVIDIA GPUs or Huawei Ascend and want both a high-performance C++ engine and a pure-Python engine for experimentation. Avoid it if your model is not on the supported list, and check which version PyPI carries, since wheel uploads resumed only after PyPI expanded LMDeploy's storage quota in April 2026. Before committing, verify that your exact model version and hardware are covered, test the quantization quality with your own evaluation set, and benchmark throughput against vLLM on your workload, since the README's 1.8x claim is a single benchmark, not a universal guarantee.
Frequently asked questions
What is LMDeploy?
A toolkit for compressing, deploying and serving LLMs, written in Python and developed by the MMRazor and MMDeploy teams under an Apache-2.0 licence. It ships two inference engines, the compiled TurboMind and a PyTorchEngine written entirely in Python, plus quantization paths for weights and for the KV cache.
Should I use TurboMind or PyTorchEngine in LMDeploy?
TurboMind is the compiled CUDA path and carries the kernel work: W4A16 for sm_75, MXFP4 from V100, Paged Attention and Split-K decoding. PyTorchEngine is written entirely in Python and is where several model and platform additions landed, including Mono-InternVL with the PyTorch engine and graph mode on Ascend. Model support differs between the two, so check docs/en/supported_models/supported_models.md.
How does LMDeploy compare with vLLM?
The project's own numbers all use vLLM as the baseline: up to 1.8x higher request throughput from persistent batching, blocked KV cache and tensor parallelism, about 1.8x faster than vLLM for internlm2-20b after the GQA work, and 1.5x the performance of vLLM on H800 for gpt-oss under MXFP4. Of those, only the gpt-oss figure names its hardware, H800.
How does LMDeploy compare with vLLM and SGLang?
The README's performance claims use vLLM as the baseline, and its introduction and news entries do not name SGLang.
How does LMDeploy differ from Ollama?
The README's introduction and news entries do not mention Ollama. What LMDeploy describes is cluster shaped serving: persistent batching and tensor parallelism in compiled kernels, a proxy server page for multi-model, multi-machine and multi-card deployments, and quantization formats gated to NVIDIA compute capabilities.
How does LMDeploy differ from llama.cpp?
The README's introduction and news entries do not name llama.cpp. The quantization formats LMDeploy ships are GPU specific: W4A16 for sm_75, MXFP4 from V100, online int8 and int4 KV cache quantization, and llm-compressor 4-bit in symmetric and asymmetric variants.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/internlm-lmdeploy)Star history chart for your README
[](https://hysenlabs.com/projects/internlm-lmdeploy)Was this useful?