Argo Workflows: A Kubernetes CRD That Turns Every Pipeline Step Into a Container
Workflow Engine for Kubernetes
At a glance
- What is it?
- Argo Workflows is a CNCF-graduated workflow engine implemented as a Kubernetes CRD, where each step runs as a container and dependencies are declared as a DAG or a step sequence. It is the right tool for teams already operating Kubernetes who need parallel batch, ML or CI jobs; it is the wrong tool if you want a scheduler that does not require a cluster.
- Who is it for?
- Adopt Argo Workflows if your compute already lives on Kubernetes and your pipeline steps are naturally containers; skip it if you need a scheduler that runs without a cluster or if your team has no capacity to own a Kubernetes controller.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
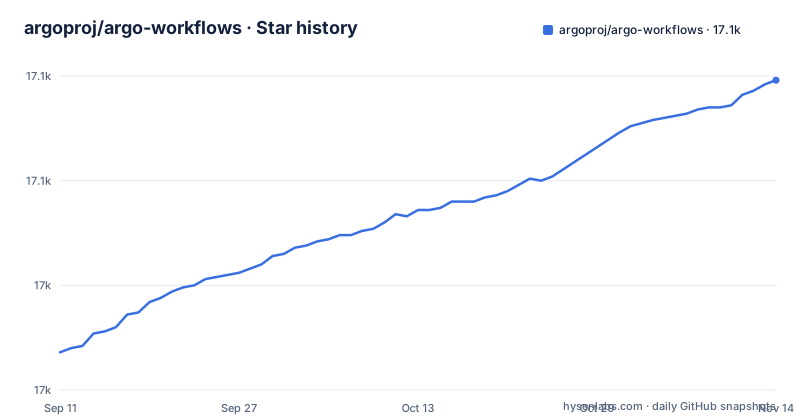
- argoproj/argo-workflows17,098 ★ · +130
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| argoproj/argo-workflows | 17k | 17.1k |
130 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Argo Workflows solves: multi-step container jobs on Kubernetes
Kubernetes runs a Pod well and a pipeline badly. A Pod has no notion of step B waiting on step A, no built-in retry for a single step, no artifact handoff between steps, and no place to declare a loop over a parameter list. Teams that need those things end up writing a controller, a status database, and a retry loop themselves. Argo Workflows targets exactly that gap. The README states it plainly: it is a container-native workflow engine for orchestrating parallel jobs on Kubernetes, implemented as a Kubernetes CRD. Each step is a container, and the workflow is a Kubernetes object rather than a separate scheduler's internal state. The intended audience is visible in the use-case list: machine learning pipelines, data and batch processing, infrastructure automation, and CI/CD. The common thread is compute that is already containerized and already destined for a cluster. If your jobs are shell scripts on a VM, Argo Workflows adds a cluster requirement without removing any of your existing work.
How the CRD, controller and executor split actually works
The architecture follows the standard Kubernetes operator pattern. A workflow is submitted as a custom resource, so it lives in etcd alongside your other objects and is readable with kubectl. A controller watches those resources and creates Pods for the steps that are ready to run. The README lists multiple executors as a feature, which means the component that actually runs your container and reports status is pluggable; the documentation does not enumerate the trade-offs between them in the README itself, so that choice has to be made from the docs. Dependency modelling is explicit: the README says you model multi-step workflows as a sequence of tasks or capture the dependencies between tasks using a directed acyclic graph. Those are two declaration styles, steps and DAG, and they are not interchangeable in every case. A DAG expresses what can run in parallel; a steps list expresses order. Data moves between steps through the features the README calls step level input and outputs, split into artifacts and parameters. Parameters are small values, artifacts are files, and artifacts are backed by the stores listed in the features section: S3, Artifactory, Alibaba Cloud OSS, Azure Blob Storage, HTTP, Git, GCS, raw, and plugins. That artifact layer is the part teams underestimate. A DAG with twenty parallel steps that each write a 4 GB artifact is a storage and network problem before it is a workflow problem.
Installing Argo Workflows and submitting a first workflow
The README points to a quick-start page at argo-workflows.readthedocs.io/en/latest/quick-start/ and a walk-through at the matching walk-through path, and it lists an Artifact Hub entry for the Helm chart at artifacthub.io/packages/helm/argo/argo-workflows. Those two routes, the documented quick-start manifests and the Helm chart, are the installation paths the project itself advertises; the README does not inline the raw kubectl apply commands, so treat the quick-start page as the source of truth rather than a command copied from a blog post. Once a controller is running, the interaction surface is the CLI, the UI, and the server interface, which the README describes as a REST API over both HTTP and GRPC. Workflow templates are stored in the cluster, which is the mechanism behind the README's workflow templating feature: a commonly used workflow is defined once and referenced by later submissions. Scheduling is handled through the cron feature for scheduled workflows. Client libraries exist for Java, Go, Python through Hera, and TypeScript through Juno, so submission does not have to go through kubectl. For Python teams specifically, the README calls out Hera as the way in, which matters because hand-writing YAML for a parameterized DAG gets old fast.
Where Argo Workflows is the wrong tool
The dependency on Kubernetes is not incidental, it is the design. There is no standalone mode described in the README. A team without a cluster, or without permission to install cluster-scoped custom resources, cannot use this at all. The second limitation is operational surface area. Running Argo Workflows means running a controller, a server interface, an artifact store, and whatever executor mode your cluster supports, and the README's feature list is long enough to indicate how many knobs exist: parallelism limits, multiple pod and workflow garbage collection strategies, pod disruption budget support, single-sign-on via OAuth2 or OIDC, and archiving of completed workflows. Each of those is a configuration decision someone has to own. The third case is short-lived, low-step-count jobs. If your pipeline is three sequential commands and it runs once a day, a CRD, a controller and an artifact store is more machinery than the job justifies. The README also lists garbage collection of completed workflows as a feature, which is a hint that completed workflow objects accumulate and need a retention policy; that is a real operational task, not a checkbox.
Airflow, Tekton and the difference in approach
Apache Airflow is the obvious comparison, and the README links a community post titled "Argo Workflows vs Apache Airflow". The difference is where the schedule and the state live. Airflow runs a scheduler and workers outside Kubernetes (or on it, but as its own system) and its tasks are Python callables executed by those workers. Argo Workflows has no separate scheduler process holding your DAG state; the workflow is a Kubernetes object and the controller reconciles it, and each step is a container the cluster schedules. That means Argo Workflows inherits Kubernetes scheduling features directly, which is why the README can list affinity, tolerations, node selectors and volumes as workflow features rather than as plugins. The cost is that anything Airflow gives you for free, such as a mature operator ecosystem and a Python-first authoring model, has to be replaced by either YAML or one of the client SDKs. Tekton is the closer architectural relative, also a Kubernetes CRD, but it splits the model differently: Tekton defines reusable Tasks and Pipelines as separate resources, while Argo Workflows keeps templating inside the workflow definition and stores commonly used workflows in the cluster as templates. If your organization already standardizes on Tekton for CI, adding Argo Workflows for batch and ML means two CRD-based engines to operate.
Maintenance, release lines and the Apache-2.0 licence
The repository is not archived and the last push recorded is 2026-10-30. The recent release list shows two maintained lines running in parallel: v4.1.6 and v4.0.15 were both published on 2026-10-22, with v4.0.14 published the same day and marked incomplete in favour of v4.0.15. Two patch releases on the same day across two minor versions is a signal that the project backports fixes, but it also means you have to decide which line you are on and track it. The licence is Apache-2.0, which is a permissive licence that permits commercial use and modification and includes an explicit patent grant; that is a summary of the identifier, not legal advice, and any redistribution or modification should be checked against the full licence text and your own counsel. Anyone pinning to v4.0.15 should confirm the upgrade path to v4.1.x from the release notes rather than assuming it. The CNCF graduated status is stated in the README and is a governance fact, not a quality guarantee.
Editorial conclusion
Adopt Argo Workflows if your compute already lives on Kubernetes and your pipeline steps are naturally containers; skip it if you need a scheduler that runs without a cluster or if your team has no capacity to own a Kubernetes controller. Before committing, verify the executor mode your cluster supports (the README lists multiple executors and Windows container support as separate features), confirm your artifact store is on the supported list (S3, Artifactory, Alibaba Cloud OSS, Azure Blob Storage, HTTP, Git, GCS, raw, plugins), and check the v4.1.x versus v4.0.x release line you intend to track.
Frequently asked questions
What is an Argo workflow?
It is a container-native workflow for Kubernetes, implemented as a custom resource definition, where each step of the workflow is a container. Steps are declared either as a sequence or as a directed acyclic graph capturing the dependencies between tasks, and the engine handles retries, timeouts, parallelism limits and suspend and resume for the whole run.
what is argo workflows used for
The project lists machine learning pipelines, data and batch processing, infrastructure automation and continuous integration and delivery, and it emphasises compute-intensive jobs where running steps in parallel on a cluster is the point. Its ecosystem list includes several machine learning projects, such as Kubeflow Pipelines, Katib, Metaflow and Seldon.
how to install argo workflows
The project file points at a quick start guide and a set of walk-through examples in its documentation, at a Helm chart published on a package registry, at an interactive training environment and at a public demo instance. It gives no installation command of its own, and the tree carries the manifests and the default configuration directories.
is argo workflows open source
It is an open source project under the Apache License 2.0, and a graduated project of the Cloud Native Computing Foundation, with participation governed by that foundation's code of conduct. The tree also carries governance, maintainers and owners files, a security policy and a public key used to sign release artefacts.
What is the difference between ArgoCD and Argo workflow?
Argo Workflows describes itself as a workflow engine where every step is a container, submitted as a custom resource, with dependencies expressed as a graph or a sequence. Its ecosystem list names an event system from the same organisation and a set of machine learning projects, and the delivery tool is not among them.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/argoproj-argo-workflows)Star history chart for your README
[](https://hysenlabs.com/projects/argoproj-argo-workflows)Was this useful?