Volcano on Kubernetes: kube-batch ancestry, three release lines, and a pinned Kubernetes minor version
A Cloud Native Batch System (Project under CNCF)
At a glance
- What is it?
- Volcano is a CNCF incubating batch scheduler for Kubernetes, descended from kube-batch and aimed at AI, big data and HPC workloads. Reading the repository rather than the README shows a module pinned to Kubernetes v1.36.1, and two patch releases, v1.15.3 and v1.14.6, shipping on the same morning.
- Who is it for?
- Adopt Volcano when you run gang-style training or analytics batches on Kubernetes and want a scheduler with its own job objects and controllers. Do not adopt it for a small cluster that never runs batch work, or when you cannot track three patch lines and a pinned Kubernetes minor version.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
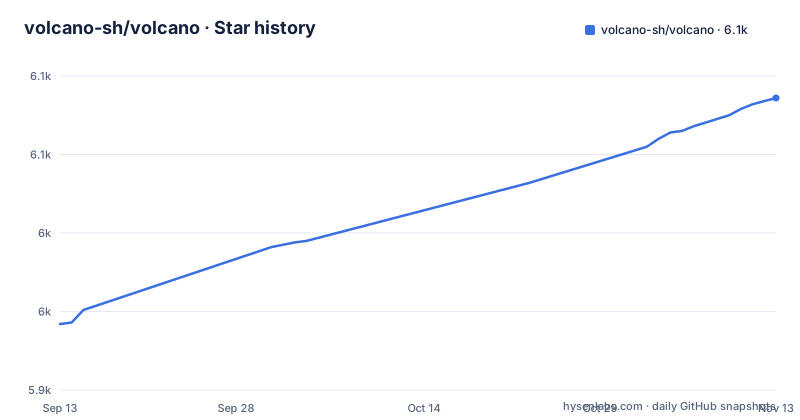
- volcano-sh/volcano6,086 ★ · +144
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| volcano-sh/volcano | 5.9k | 6.1k |
144 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
kube-batch is the base you can still see under it
Volcano is a Kubernetes-native batch scheduling system that extends and enhances the capabilities of the standard kube-scheduler, aimed at AI, machine learning and deep learning training, bioinformatics and genomics, and other big data workloads. Next to that description sits a NOTE with two issue numbers in it: the scheduler is built based on kube-batch, and the README points at issue 241 and pull request 288 for the detail.
That lineage explains more than it first appears to. The project is not a patched copy of kube-scheduler; it is a scheduler of its own that extends the standard one, and its scheduler is built based on kube-batch. Anyone chasing a scheduler bug upstream has to know which of those two code bases a fix actually landed in, because a change in one is not automatically a change in the other.
The Cloud Native Computing Foundation lists Volcano as an incubating project, which is a statement about governance and maturity rather than about the code.
Three patch lines published inside one minute
The most recent release is v1.16.0, published on 2026-10-14. Before it, two patch releases were published on the morning of 2026-09-30, within about a minute of each other: v1.14.6 at 08:55:30 UTC and v1.15.3 at 08:56:19 UTC. The last push to the default branch, master, landed on 2026-11-02.
Three live lines means three patch streams to follow, so an administrator has to pick one and decide what happens when a fix appears in another. The repository keeps release notes in CHANGELOG.md, a .release-version file at the top level, and MAINTAINERS.md, GOVERNANCE.md and SECURITY.md for the human side. The licence is Apache-2.0, and the default branch is master rather than main, which matters for anyone scripting CI against the raw repository.
What that cadence does not tell you is how long each line stays supported, or whether a fix in v1.15.3 is backported into v1.14.6.
go.mod pins Kubernetes v1.36.1, so upgrades arrive coupled
The module is volcano.sh/volcano and it declares go 1.26.0, so a build host older than that Go release is out of scope:
module volcano.sh/volcano

go 1.26.0
The Kubernetes libraries move in lockstep. k8s.io/kubernetes sits at v1.36.1, and k8s.io/api, k8s.io/apimachinery, k8s.io/client-go, k8s.io/component-base, k8s.io/component-helpers and k8s.io/dynamic-resource-allocation all sit at v0.36.1. Alongside them are controller-runtime v0.24.1, cobra v1.10.2 for the command surface, prometheus/client_golang v1.23.2 for metrics, and klog/v2 v2.140.0.
That is the coupling worth planning around. Check these pins against your cluster's Kubernetes version before a version bump, not after.
GOARCH comes from uname -m, and the CRDs are generated with v1 APIs
Two parts of the Makefile decide the shape of a build before any target runs. The first is architecture detection: OSARCH is read from uname -m, and the mapping sends x86_64 to amd64, aarch64, aarch64_be, armv8b and armv8l to arm64, i386 and i686 to x86, and arm to arm. On any other architecture the fallback assigns GOARCH straight from uname -m, so the Makefile passes through whatever value it sees.
The second is CRD generation and plugin packaging. These four lines are the ones that shape the output:
OUTPUT_DIR ?= _output
REPO_PATH=volcano.sh/volcano
IMAGE_PREFIX=volcanosh
CRD_OPTIONS ?= "crd:crdVersions=v1,generateEmbeddedObjectMeta=true"
CRD_VERSION defaults to v1 and SUPPORT_PLUGINS to "no". BUILDX_OUTPUT_TYPE is "docker" and FORCE_REBUILD is true, so images are rebuilt rather than reused. Binaries end up under _output/bin, because OUTPUT_DIR defaults to _output and BIN_DIR is set to ${OUTPUT_DIR}/bin. CC defaults to "gcc" and MUSL_CC to "/usr/local/musl/bin/musl-gcc".
No install command, so start from installer/ and example/
The repository layout shows where the software comes from: an installer/ directory at the top level, config/ and defs/ beside it, and images published under the volcanosh prefix.
From a checkout, the module path and the image target are the concrete handles:
make images DOCKER_PLATFORMS="linux/amd64,linux/arm64"This is the form the Makefile's own comment uses for a multi-architecture build, without the BUILDX_OUTPUT_TYPE setting that comment also passes.
For a first workload, example/ is the shortest route. example/job.yaml is the plain job and example/job-plugin.yaml is the plugin variant; the sibling directories cover hierarchical-jobs, sharding, task-start-dependency, jobflow, cronjob, deployment, extender, custom-plugin, invalid_jobs and integrations. Read example/invalid_jobs/ early, because it shows what the project treats as malformed input, which is a faster way to learn the rules than submitting a rejected job.
The module reaches down into CNI, eBPF and cgroups
The dependency list is wider than a scheduler's usually is. cilium/ebpf v0.17.3, containernetworking/cni v1.3.0 and containernetworking/plugins v1.1.1 put an eBPF and CNI stack into the build graph. opencontainers/cgroups v0.0.8 and moby/sys/userns v0.1.0 reach into container and cgroup internals. elastic/go-elasticsearch/v7 v7.17.10 and stathat.com/c/consistent v1.0.0 sit alongside them, and robfig/cron/v3 v3.0.1 is listed as well.
What the file does not tell you is which component pulls in the eBPF and cgroup packages, or whether a deployment can be trimmed down without them. Anyone trying to shrink the image or audit the supply chain has to read the imports.
The same file carries the test stack: ginkgo/v2 v2.32.0, gomega v1.42.1, sigs.k8s.io/e2e-framework v0.7.0 and a go-fuzz headers package, plus agiledragon/gomonkey/v2 v2.14.1 for patching functions at runtime. That last dependency tells you the unit tests rewrite behaviour in place instead of only driving public interfaces.
The front page is a conference playlist and its architecture heading is empty
Read the README from top to bottom and most of it is a link list. Eighteen conference links run from an ArchSummit 2019 talk in Shenzhen and a Huawei Connection 2019 session through sixteen KubeCon appearances, ending with two in the 2026 EU edition. Then comes an ecosystem section pointing at Spark Operator, native Spark on Kubernetes, Flink on Kubernetes, KubeRay, Grove, PyTorch, TensorFlow, kubeflow trainer in v1 and v2 form, kubeflow/arena, MPI, Horovod, PaddlePaddle, Cromwell, MindSpore, MXNet, Argo and KubeGene.
The section headed Overall Architecture links to an architecture diagram at docs/images/volcano-new-architecture.svg.
The example manifests and the Makefile add the defaults and build options.
Volcano beside kube-scheduler, descended from kube-batch
The comparison that matters is with the scheduler already running in the cluster. kube-scheduler places pods as they arrive. Volcano is a separate scheduling component with its own custom resources and controllers, and the project's claim about the standard scheduler is that it extends and enhances its capabilities rather than taking its place. The repository generates those custom resources with the controller-gen style options quoted above, CRD_OPTIONS at crdVersions=v1 with CRD_VERSION at v1, which is what defines the objects a batch job is written in.
The second reference point is kube-batch, named in the README as the project the scheduler was built from. That is ancestry rather than competition, and it matters when reading a bug: an issue traced back to kube-batch has to be matched to this code base before anyone relies on the fix.
Neither relationship hides the upgrade bill. Three release lines and one pinned Kubernetes library version mean an operator checks go.mod and the release notes before every bump.
Editorial conclusion
Adopt Volcano when you run gang-style training or analytics batches on Kubernetes and want a scheduler with its own job objects and controllers. Do not adopt it for a small cluster that never runs batch work, or when you cannot track three patch lines and a pinned Kubernetes minor version. Check k8s.io/kubernetes in go.mod against the minor version of your API server, then read docs/ for the queue and plugin configuration.
Frequently asked questions
What does Volcano do in Kubernetes?
Volcano is a Kubernetes-native batch scheduling system that extends and enhances the capabilities of the standard kube-scheduler, aimed at AI, big data and HPC workloads such as those run on Spark, Flink, Ray, PyTorch or Argo. Its scheduler is built on top of kube-batch, and the project is an incubating project of the Cloud Native Computing Foundation.
Which Kubernetes versions does Volcano support?
The go.mod pins k8s.io/kubernetes v1.36.1, with k8s.io/api, apimachinery, client-go, component-base, component-helpers and dynamic-resource-allocation all at v0.36.1. Those are the library versions the code is built against.
How do you build and install Volcano from source?
A checkout builds through the module volcano.sh/volcano, with images produced under the volcanosh prefix, and the Makefile exposes targets such as make images with DOCKER_PLATFORMS set for a multi-architecture build. The repository also has an installer/ directory at the top level.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/volcano-sh-volcano)Star history chart for your README
[](https://hysenlabs.com/projects/volcano-sh-volcano)Was this useful?