ai-agent-interview-guide: A Chinese-Language Interview Prep Repository With Three Agent Backends
A complete AI Agent interview guide, from zero to offer: 200+ interview questions, enterprise-level projects (Python/Java/Go), resume templates, STAR-method interview scripts, and Doraemon comic-style illustrations.
At a glance
- What is it?
- The repository bundles a nine-module question bank, three parallel implementations of the same customer-service agent (Python, Java, Go), and a STAR-format interview script. It is a study artifact, not a library, and the README's own note about commercial use is the first thing to check.
- Who is it for?
- Adopt it if you are preparing for a Chinese-market AI Agent or backend role and want a single repository that pairs question banks with runnable code in the language you already know. Do not adopt it if you need a maintained agent framework to ship: there are no releases, the README states the study materials are for learning reference and asks that they not be used commercially, and the three project directories are teaching replicas rather than a supported platform.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
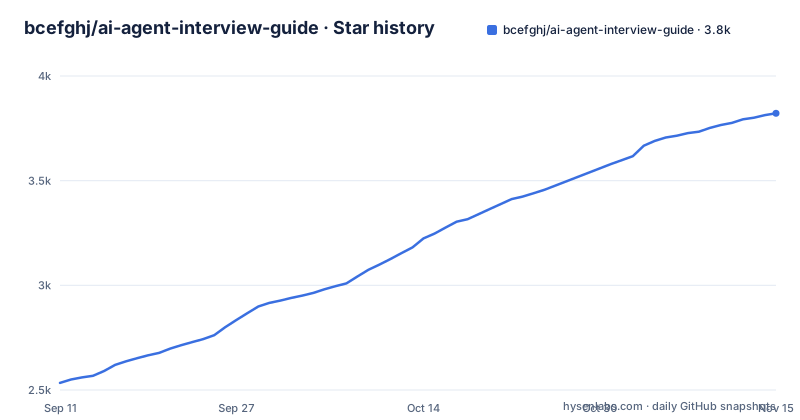
- bcefghj/ai-agent-interview-guide3,822 ★ · +1,288
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| bcefghj/ai-agent-interview-guide | 2.5k | 3.8k |
1,288 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the repository actually is, and who it is written for
This is a preparation kit, not a runtime dependency. The README describes it as material for beginners, aimed at people moving toward an AI Agent role, and the folder layout backs that up: docs/ holds the study material, comics/ holds six illustrated explainers, and three sibling directories hold the same enterprise-style project reimplemented in Python, Java and Go. The stated target audiences differ per port. The Python version is labeled for AI and algorithm positions and Python backend work, the Java version for Java backend developers, and the Go version for Go backend and cloud-native roles. That split is the most useful design decision in the repository. A candidate interviewing for a Java backend team does not have to translate a Python LangChain example into Spring AI in their head during preparation. The cost is duplication: the same architecture is described three times, and any correction to the design has to be applied three times. Nothing in the README indicates whether the three ports are kept in sync.
The agent platform the three project directories describe
The README gives an architecture diagram for what it calls an enterprise intelligent customer service and knowledge assistant agent platform. The request path is stated as: user request, API gateway, intent recognition, then an agent orchestrator. The orchestrator fans out to four agent types. A ReAct agent runs a thought-action-observation loop. A planning agent decomposes tasks. A RAG agent handles retrieval and generation. A reflection agent performs quality checks. Beneath that sits a support layer with four named pieces: multi-path retrieval combining vector search, BM25, hybrid retrieval and RRF fusion; a memory system with a Redis sliding window for short-term context and a vector database for long-term memory; a tool system covering search, a calculator, database queries and MCP; and a model router with multiple model candidates, a three-state circuit breaker and automatic fallback. Two cross-cutting concerns are listed as well: full trace recording of each step, and a document ETL pipeline that parses PDF and Word, chunks, vectorizes and stores. This is a plausible interview narrative because each component maps to a question a candidate could be asked. It is also a lot of surface area, and the README does not say which of these pieces are fully implemented versus sketched.
Getting the Python project running, and what the other two require
The README gives one command sequence per language. For Python, the recommended first choice: cd project-python, then cp .env.example .env, then edit .env to fill in your API key, then pip install -r requirements.txt, then uvicorn app.main:app --reload --host 0.0.0.0 --port 8000. The Java version is cd project-java, mvn clean package -DskipTests, then java -jar target/agent-platform-1.0.0.jar. The Go version is cd project-go, go build -o agent-server ./cmd/server, then ./agent-server. Notice what is missing. The Python path requires an API key but the README does not name which provider, and the architecture implies Milvus and Redis are needed for retrieval and short-term memory, yet no docker-compose or service startup step appears in the quick start. If you run the uvicorn command without those services reachable, expect startup or first-request failures rather than a clean demo. The .env.example file is the place to look before running anything, since it is the only artifact the README points at for configuration.
The question bank is the part with the most concrete inventory
The README publishes a per-module question count table, which is more specific than most repositories manage. Basic concepts covers agent definitions, composition, classification and application scenarios at 27 questions. Core frameworks covers ReAct, Plan-and-Execute, Reflexion and LangGraph at 27. RAG covers chunking strategy, vector databases, hybrid retrieval and reranking at 24 or more. Tool calling covers Function Calling, MCP, tool routing and security at 17 or more. Memory systems covers short and long term memory, summary compression and memory retrieval at 20. Multi-agent covers collaboration patterns, communication mechanisms and conflict resolution at 20. Large model fundamentals covers Transformer, Attention, KV Cache, LoRA and RLHF at 28. Engineering practice covers circuit breakers, token optimization, observability and deployment at 29 or more. Prompt engineering covers CoT, few-shot, ReAct templates and injection defense at 28. The module files are named 01-基础概念.md through 09-Prompt工程.md under docs/01-面试八股文/. The hedge words (24+, 17+, 29+) suggest the author is counting loosely, which is worth knowing before you treat the totals as a coverage guarantee.
Where the repository is the wrong tool
Three constraints stand out. First, there are no releases. The material is delivered as a repository snapshot on the main branch, so there is no versioned artifact to pin and no changelog to read. Second, the README states the interview material and study documents are for learning reference and asks that they not be used commercially. That sentence sits directly under an MIT License declaration, and the two are not obviously reconciled. MIT is a permissive license, but the README adds a usage request on top of it; if you intend to reuse the question bank or the project code inside a product, that is a question for your own legal review, not something this article can settle. Third, the language is Chinese throughout. The module names, the STAR scripts, the recruitment analysis of companies like Tencent, Xiaohongshu and ByteDance, and the interview Q&A are all written for the Chinese hiring market. A candidate interviewing in English will find the project code useful and the prose largely unusable.
How it differs from LangChain or a framework tutorial
The obvious alternative for someone learning agent construction is LangChain itself, or a framework-specific course. The difference in approach is the direction of the artifact. LangChain is a library you build on; its documentation teaches you the library's abstractions, and your output is an application. This repository inverts that. Its output is an interview performance, and the code exists to give you something concrete to describe when asked how you would design a system. The README even names the comparison point for the project's complexity: nageoffer/ragent. That framing tells you the code is a replica of a reference architecture, chosen so the design decisions are defensible in a interview, not because the implementation is novel. If your goal is to ship an agent, a framework plus your own requirements will get you further. If your goal is to answer why you chose RRF fusion over a simple weighted sum, this repository is organized around exactly that kind of question.
Maintenance cost and what to check before committing
The repository is MIT licensed and not archived, with the last push recorded as 2026-04-01. There are no releases, so upgrades mean pulling the branch. The practical maintenance burden falls on you in three places. The .env file holds credentials you supply, so key rotation is your responsibility. The Python stack pulls FastAPI, LangChain, Milvus and Redis, and the Java stack pulls Spring Boot 3, Spring AI, MyBatis Plus and Milvus; both are dependency trees that will drift from the pinned versions over time, and the README does not describe a version policy. The Go version uses Gin plus a self-developed framework, which is the one most likely to diverge from the other two as upstream libraries change. Before investing in any of the three, read project-python/.env.example to confirm which model providers and service endpoints are expected, and check whether the Milvus and Redis instances the architecture assumes are something you can stand up locally. If they are not, the Python quick start will not produce a working agent regardless of how good the question bank is.
Editorial conclusion
Adopt it if you are preparing for a Chinese-market AI Agent or backend role and want a single repository that pairs question banks with runnable code in the language you already know. Do not adopt it if you need a maintained agent framework to ship: there are no releases, the README states the study materials are for learning reference and asks that they not be used commercially, and the three project directories are teaching replicas rather than a supported platform. Verify first that project-python/.env.example matches the providers you actually have keys for, then run the uvicorn command and confirm the Milvus and Redis endpoints it expects are reachable before you invest time in the Java or Go ports.
Frequently asked questions
What are the 5 parts of an AI agent?
The guide's architecture does not commit to a five-part definition. What it draws is a request path through an API gateway and an intent-recognition step into an agent orchestrator, which dispatches to one of four agents: a ReAct agent running a thought, action and observation loop, a planning agent for task decomposition, a RAG agent for retrieval and generation, and a reflection agent for quality checks.
How do I prepare for an AI interview?
The quick start gives six steps: read the learning roadmap, which is six stages over roughly seven to nine months; work through the nine Q&A modules from basic concepts; look at the enterprise recruitment analysis; pick one of the three project versions to build; prepare a résumé from the STAR template and rehearse the interview script; then mock with the interview question set.
What does the ai-agent-interview-guide reference project do?
It is described as an enterprise intelligent customer service and knowledge assistant agent platform. A request passes through an API gateway and intent recognition into an orchestrator, then to one of four agents. The support layer is multi-channel retrieval combining vector search, BM25 and RRF fusion, a memory system using a Redis sliding window for short term and a vector store for long term, a tool system including MCP, model routing with a three-state circuit breaker and automatic degradation, per-step trace records, and an ETL path from PDF and Word to chunking, vectorisation and ingestion.
Can I use the ai-agent-interview-guide material commercially?
The licence section says the project uses the MIT License, and separately that the interview Q&A and study material is for study reference only and must not be used for commercial purposes. A LICENSE file sits at the repository root, and the page does not say which files the non-commercial clause governs.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/bcefghj-ai-agent-interview-guide)Star history chart for your README
[](https://hysenlabs.com/projects/bcefghj-ai-agent-interview-guide)Was this useful?