bitsandbytes: k-bit Quantization for PyTorch, From 8-bit Optimizers to QLoRA
Accessible large language models via k-bit quantization for PyTorch.
At a glance
- What is it?
- bitsandbytes brings 8-bit optimizers, LLM.int8() inference, and QLoRA 4-bit training to PyTorch, with support for CPU, NVIDIA, AMD, Intel, and Apple hardware. This review covers its mechanisms, setup, limitations, and alternatives.
- Who is it for?
- Adopt bitsandbytes if you are a PyTorch user who needs to run or fine-tune large language models on limited memory, especially on NVIDIA GPUs with SM75+ or on CPU with AVX2. Avoid it if you rely on Gaudi accelerators for 8-bit optimizers (not supported) or if you need optimized LLM.int8() performance on aarch64 CPU (marked with an asterisk as possibly lacking optimizations).
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
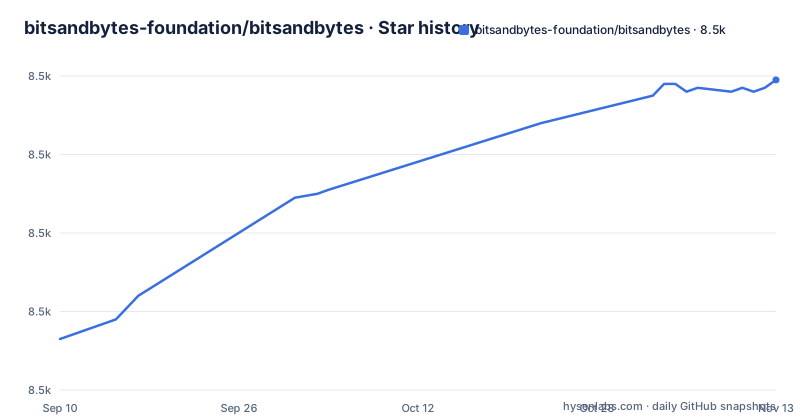
Star history
- bitsandbytes-foundation/bitsandbytes8,539 ★ · +66
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| bitsandbytes-foundation/bitsandbytes | 8.5k | 8.5k |
66 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What bitsandbytes Actually Solves
Running or training a large language model on a single GPU often fails because the model weights and optimizer states exceed available memory. bitsandbytes attacks that problem with quantization, which reduces the number of bits used to represent each weight or gradient. The project targets PyTorch users who want to fit bigger models on existing hardware without buying new accelerators. Its three headline features address different points in the workflow. The 8-bit optimizers shrink the memory footprint of optimizer states during training, which is often the dominant cost when using Adam or similar methods. LLM.int8() is for inference, cutting memory roughly in half while aiming for no performance degradation. QLoRA goes further for training, quantizing the base model to 4 bits and adding a small set of trainable low-rank adaptation weights. The library exposes these through specific modules and classes, such as bitsandbytes.nn.Linear8bitLt and bitsandbytes.nn.Linear4bit, plus the bitsandbytes.optim module for optimizers.
The Mechanism: Block-wise, Vector-wise, and Outlier Handling
The quantization methods differ in how they map floating-point numbers to lower precision. The README describes 8-bit optimizers as using block-wise quantization, which means the scale factor is computed per block of values rather than per tensor. That local scaling preserves accuracy better than a single global scale. LLM.int8() takes a different route: it uses vector-wise quantization for most features, quantizing to 8 bits, but it identifies outliers and treats them separately with 16-bit matrix multiplication. That hybrid approach is what keeps output quality close to full precision, because outliers are often responsible for a disproportionate share of the model's behavior. QLoRA quantizes the model to 4 bits and then inserts low-rank adaptation weights that remain trainable. This separation lets you train without updating the full precision weights, which is what saves memory. Understanding these distinctions matters because they explain why the library does not simply round all values to a fixed number of bits.
Setup and System Requirements
The installation path depends on your platform. The README lists Python 3.10 and PyTorch 2.4 as minimum requirements for all platforms. On Linux, you need glibc >= 2.24. For x86-64 CPUs, the minimum is AVX2, with AVX512F and AVX512BF16 as optimized paths. NVIDIA GPUs need SM60 or newer, with SM75 recommended. The project also supports AMD GPUs with specific gfx targets, Intel GPUs including Arc A-Series and Data Center Max, and Apple M1 and newer on macOS 14+. The project is on PyPI and provides a continuous-release wheel named continuous-release_main. You would install it with pip, for example pip install bitsandbytes. The documentation lives on Hugging Face, with separate guides for Transformers, Diffusers, and PEFT integrations. That integration is a key part of the setup: you often do not call bitsandbytes directly but through a library like Transformers that wraps its quantized layers.
Hardware Support: Broad but Uneven
The accelerator support table is the most informative part of the README, and it reveals real differences in maturity. On Linux x86-64, all three features are marked as supported for CPU, NVIDIA, AMD, and Intel GPUs. But the table also uses a legend with planned, partially supported, and not supported states. Intel Gaudi is a clear example: LLM.int8() is supported, QLoRA 4-bit is only partially supported, and 8-bit optimizers are not supported at all. Apple's Metal backend has 8-bit optimizers marked as planned, meaning they are not yet available. The asterisks on LLM.int8() for aarch64 CPU, macOS CPU and Metal indicate that it is supported there but may lack performance optimizations. That matters if you are on an M-series Mac and plan to run LLM.int8() inference: it is supported, but may not be optimized. The README notes that the table reflects the current development branch, so the stable release 0.50.0 may have a different status. Always check the tag-specific README if you are on a released version.
Where It Fails or Is the Wrong Tool
The most obvious limitation is hardware. If you are on an Intel Gaudi accelerator and want to use 8-bit optimizers, this library is not the right choice because the feature is listed as not supported. Similarly, if you are on Apple Metal and need 8-bit optimizers today, they are only planned, so you would be waiting. Another constraint is the Python and PyTorch floor: Python 3.10 and PyTorch 2.4 mean that projects pinned to older versions cannot use the latest bitsandbytes without upgrading. The README also warns that while they aim for wide backwards compatibility, using the latest PyTorch is recommended. That is a maintenance signal: you may need to move your whole stack forward to stay on supported versions. Performance is another concern. The asterisks on LLM.int8() for aarch64 CPU and macOS say it 'may lack performance optimizations.' If you are on an Apple Silicon Mac and expect production-grade throughput for LLM.int8(), the documentation is telling you that you might be disappointed. For users who only need inference and have ample memory, quantization is an unnecessary complexity layer; full precision inference is simpler and avoids any risk of quality loss.
Alternatives: How They Differ in Approach
The most direct alternative is Hugging Face's own quantization integrations, which often build on bitsandbytes but add a layer of abstraction. The README links to Transformers, Diffusers, and PEFT documentation for bitsandbytes, so those are not competitors but wrappers. A real alternative in approach is GPTQ, which is a post-training quantization method that calibrates against a dataset to find optimal scales and zero points. Unlike bitsandbytes, which applies quantization at runtime with a deterministic scheme, GPTQ requires a separate calibration step and produces a quantized model file. That means GPTQ models are typically pre-quantized and loaded directly, while bitsandbytes can quantize a model on the fly. Another alternative is AWQ, which also uses activation-aware scaling to protect important weights. The key difference is that bitsandbytes is a general-purpose library that also provides optimizers and training support, while GPTQ and AWQ are focused on inference-time compression. If your goal is purely to serve a quantized model and you are willing to run calibration, GPTQ or AWQ might give better quality per bit, but they do not offer the training path that QLoRA does.
Maintenance, Licensing, and Upgrade Cost
The project is under active development. The last push was in November 2026, with a recent stable release 0.50.2 in August 2026 and a continuous-release wheel updated in October 2026. The release notes for 0.50.1 mention RTX Spark support, which indicates the project tracks new NVIDIA hardware. This cadence means you should expect frequent updates and plan for them. The license is MIT, which is permissive and does not impose copyleft obligations, so you can use it in commercial products without releasing your own code. That is a low-license-risk choice, though you should still review the full license text if you have specific legal concerns. The maintenance cost comes from keeping up with PyTorch updates. The README recommends using the latest PyTorch, which means every PyTorch release could require a bitsandbytes update. If you are integrating with Transformers, you also need to track version compatibility across three libraries. The project's sponsorship by Hugging Face suggests ongoing investment, but the documentation does not specify a formal support contract, so you are relying on community and maintainer responsiveness.
Editorial conclusion
Adopt bitsandbytes if you are a PyTorch user who needs to run or fine-tune large language models on limited memory, especially on NVIDIA GPUs with SM75+ or on CPU with AVX2. Avoid it if you rely on Gaudi accelerators for 8-bit optimizers (not supported) or if you need optimized LLM.int8() performance on aarch64 CPU (marked with an asterisk as possibly lacking optimizations). Before adopting, verify that your hardware is listed in the accelerator table, that your PyTorch version is 2.4 or newer, and that you can meet the glibc requirement on Linux. Check the latest release notes, as the project is under active development with recent updates for RTX Spark support.
Frequently asked questions
How do I install the bitsandbytes library?
The stated minimums are Python 3.10+ and PyTorch 2.4+, with a recommendation to use the latest PyTorch. Runtime dependencies are torch>=2.4,<3, numpy>=1.17, and packaging>=20.9, and a source build goes through the scikit-build-core backend, which compiles csrc/ via CMake.
How do I install bitsandbytes with GPU support?
The GPU you own decides which row of the support table you land on. NVIDIA needs SM60+ minimum and SM75+ recommended on x86-64, AMD is listed for CDNA gfx908 and gfx90a (plus gfx942, gfx950 and gfx1250 on Linux) and several RDNA families, and Intel Arc A and B series run on the xpu backend, while 8-bit optimizers are not supported on Intel Gaudi2 or Gaudi3.
How do I use bitsandbytes?
Drop in the quantized layer modules, bitsandbytes.nn.Linear8bitLt for 8-bit and bitsandbytes.nn.Linear4bit for 4-bit, and reach the optimizers through the bitsandbytes.optim module. check_bnb_install.py in the repository root checks the install, and examples/int8_inference_huggingface.py shows the 8-bit inference path.
What does bitsandbytes do?
It cuts PyTorch memory for inference and training three ways: block-wise quantized 8-bit optimizer state, vector-wise LLM.int8() inference that keeps outliers in 16-bit matrix multiplication, and 4-bit QLoRA training with small trainable low-rank adaptation weights added on top.
What is bitsandbytes quantization?
Three schemes under one name: block-wise quantization for the optimizers, vector-wise quantization for LLM.int8(), and 4-bit quantization for QLoRA, where the low-rank adapter is the only trainable part. The per-layer details live in the official documentation rather than the README.
What is bitsandbytes used for?
LLM.int8() targets inference with only half the required memory, and QLoRA targets fine-tuning a 4-bit quantized model by training a small set of low-rank adaptation weights on top of it. Both plug into the quantization primitives under bitsandbytes.nn.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Fine-Tuning Gemma 4 on an 8 GB RTX 3050: Slow, Low End and Still Viabledev.to · Oct 21, 2026 · 4 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/bitsandbytes-foundation-bitsandbytes)Star history chart for your README
[](https://hysenlabs.com/projects/bitsandbytes-foundation-bitsandbytes)Was this useful?