MLX-VLM: Running and fine-tuning vision-language models on Apple Silicon
MLX-VLM is a package for inference and fine-tuning of Vision Language Models (VLMs) on your Mac using MLX.
At a glance
- What is it?
- MLX-VLM brings inference, fine-tuning, and a growing set of optimizations for vision-language models to Macs with Apple Silicon. It is a practical option for developers who want local, private VLM workloads without a CUDA GPU.
- Who is it for?
- Adopt MLX-VLM if you are a Mac user with Apple Silicon, need local or private inference of VLMs, and value a wide model zoo with Python APIs and a FastAPI server. It is not the right tool if you need production-grade multi-GPU serving, or want to avoid dependency on a fast-moving project with frequent releases.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
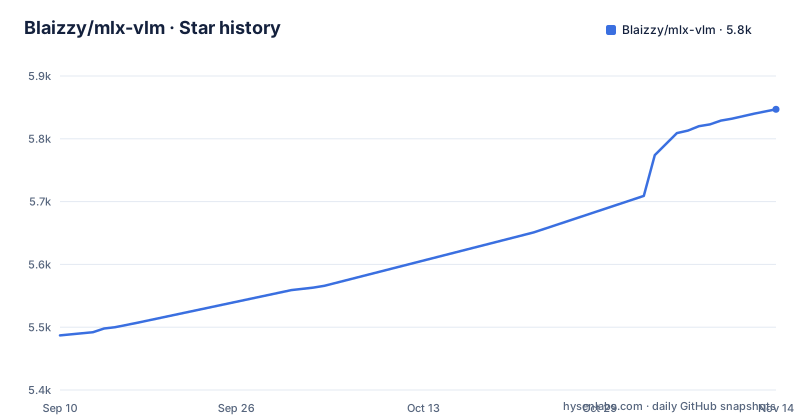
- Blaizzy/mlx-vlm5,847 ★ · +360
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| Blaizzy/mlx-vlm | 5.5k | 5.8k |
360 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What MLX-VLM solves and who it targets
MLX-VLM exists to close a specific gap: running vision-language models on Macs without a CUDA GPU. Most VLM frameworks assume NVIDIA hardware, leaving Apple Silicon users with slow CPU inference or cloud dependencies. MLX-VLM uses Apple's MLX framework to run VLMs and omni models, which also handle audio and video, directly on the Mac's unified memory. The target user is a developer or researcher who wants to prototype, fine-tune, or serve a VLM locally, with the privacy and cost benefits of no cloud round trips. The package is Python-based and installable via pip, so it fits into existing Python workflows. It also ships a Gradio chat UI and a FastAPI server, which makes it usable for local demos and small internal tools. The README lists a large number of supported architectures, including LLaVA-OneVision and newer ones like Gemma 4 and MiniMax M3, which suggests a broad scope. The pyproject also defines optional cuda and cpu extras (mlx-cuda and mlx-cpu), and the README has an Activation Quantization (CUDA) section.
Architecture and data flow: from Hugging Face weights to MLX execution
The core mechanism is conversion of Hugging Face models into MLX format and then running them with MLX operations. The README references a conversion script, mlx_vlm.convert, which handles quantization with options for bits, group size, and modes like RTN and AWQ. Once converted, inference happens through the generate module or the server. The data flow is typical for MLX ports: weights are downloaded from Hugging Face, converted to MLX's format, and then loaded into memory for inference. The package supports speculative decoding with several draft model methods, including DFlash, DFlash2, DSpark, and Gemma 4's MTP, which are designed to speed up token generation. There is also a vision feature caching mechanism that likely stores computed image embeddings to avoid recomputation across prompts, which is a common optimization for multi-turn VLM conversations. The server component adds continuous batching and automatic prefix caching, which are advanced features for serving multiple requests efficiently. Distributed inference has its own section in the README table of contents. This architecture means that the package is not a wrapper around a remote API; it runs everything locally, which is a different trade-off from cloud-based services.
Getting started: installation and first commands
Installation is straightforward with pip. The README gives the command pip install -U mlx-vlm for the base package. If you want the Gradio chat UI, you need the extra dependency, and the README warns to quote the package name to avoid shell globbing: pip install -U 'mlx-vlm[ui]'. After installation, the command-line entry point is mlx_vlm.generate. The cli-inference skill describes it as covering text, image and audio inputs and image-generation flags. The CLI is the entry point for quick tests. For a more interactive experience, you can launch the Gradio UI or start the FastAPI server. The server exposes multiple endpoints, including chat, responses, messages, audio, image, cache, and metrics, which makes it suitable for integrating into a web app. The README also mentions a skills bundle that can be loaded into coding agents like Claude Code or Codex. That is a unique feature for a project of this type, aimed at improving developer workflows.
Optimizations that matter: quantization, speculative decoding, and caching
MLX-VLM includes several performance features that are directly relevant to running large models on memory-constrained Macs. Quantization is handled through the conversion script, with support for bits, group size, and modes like RTN and AWQ. The README mentions mixed recipes, which likely allow different quantization levels for different layers. Speculative decoding is supported via multiple draft methods, which can reduce latency by generating multiple tokens in parallel and then verifying them. The server supports continuous batching, which improves throughput when handling multiple requests, and automatic prefix caching, which reuses computation for repeated prompt prefixes. There is also KV cache quantization, which reduces the memory footprint of the key-value cache during generation. The TurboQuant KV cache is another optimization, with its own README section. These features indicate a project that cares about making VLMs usable on consumer hardware, not just a proof of concept.
The model zoo: breadth versus depth
One of MLX-VLM's strengths is the number of supported model architectures. The README lists dozens of models with dedicated documentation, including OCR-focused models like DeepSeek-OCR and PaddleOCR-VL, multimodal models like Phi-4 Multimodal and MiniCPM-V, and newer ones like Gemma 4 and MiniMax M3. This breadth is a double-edged sword. For a user, it means you can often find a model that fits your task, whether that is document extraction, visual question answering, or point-based grounding. The model-specific documentation includes prompt formats and best practices, which is valuable because VLM prompts are often finicky. However, maintaining support for so many architectures is a large burden. Porting a new architecture is its own workflow, with an add-new-model skill for it. This means that some models may have subtle bugs or lag behind the latest versions from Hugging Face. If you need the latest model release, you may have to wait for the maintainers to port it. Also, the package does not support every VLM; it is a curated set.
Limitations and failure modes
The primary target is Apple Silicon Macs, although the pyproject also defines cuda and cpu extras (mlx-cuda and mlx-cpu). The package also depends on the MLX framework, which is under active development, so API changes can break the package. The release history shows frequent releases, with v0.7.9, v0.7.10 and v0.7.11 released between 2026-10-19 and 2026-10-28, indicating a fast iteration cycle. That speed can mean instability. Another failure mode is memory. Even with quantization, large VLMs can exceed the unified memory of a base Mac. For example, a 70B model in 4-bit still requires around 35GB of memory, which is only available on higher-end Macs. The distributed inference feature, which has its own README section, might help. The server's continuous batching and prefix caching are advanced, but they are likely single-node features; scaling to multiple replicas is not described. Also, the package is for inference and fine-tuning, with a Fine-tuning section in the README and an examples/training/ folder.
Alternatives and how they differ
The most direct alternative is llama.cpp with its VLM support, which runs on a wider range of hardware, including CPUs and CUDA GPUs, and uses GGUF quantization. The difference in approach is that llama.cpp is a C++ project with a different memory management model, and it supports many models but often requires manual conversion of vision towers. Another alternative is the official MLX examples repository from Apple, which includes some VLM implementations but is not a unified package like MLX-VLM. The official examples tend to be more minimal and require more manual work to adapt to new models. A third alternative is using a cloud API like OpenAI's GPT-4V or Anthropic's Claude, which removes local hardware constraints but introduces latency, cost, and privacy concerns. MLX-VLM's advantage is that it provides a consistent Python API and CLI for many models on Apple hardware, with optimizations like speculative decoding that are not always present in other local solutions. The trade-off is that you are tied to Apple's ecosystem and the project's maintenance pace.
Maintenance, licensing, and upgrade cost
The project is MIT licensed, which is permissive and allows commercial use with attribution. The repository is not archived and had a push on 2026-11-02, indicating active maintenance. The release cadence is high, with three releases in a two-week period, which means frequent updates. This is a double-edged sword: you get new features and model support quickly, but you also face potential breaking changes. Upgrading may require reading release notes or testing. The dependency on MLX means that when MLX updates, MLX-VLM must adapt, and there could be lag. The project also includes a skills bundle for coding agents, which is an interesting but non-essential feature. For maintenance, you should expect to pin your mlx-vlm version and test after upgrades. The package is not a standalone binary; it is a Python package, so you need a Python environment management strategy. The cost of upgrading is moderate: you must reinstall and possibly reconvert models if the format changes. The project does not appear to have a formal deprecation policy, so older model support may be dropped without notice.
Editorial conclusion
Adopt MLX-VLM if you are a Mac user with Apple Silicon, need local or private inference of VLMs, and value a wide model zoo with Python APIs and a FastAPI server. It is not the right tool if you need production-grade multi-GPU serving, or want to avoid dependency on a fast-moving project with frequent releases. Before adopting, verify that your target model is listed in the model-specific documentation, check the quantization options in the convert script, and test the CLI and server on your exact macOS version. The project is MIT licensed and under active development, so expect breaking changes and check the changelog before upgrading.
Frequently asked questions
What is mlx-vlm?
It is a Python package for inference and fine-tuning of Vision Language Models and Omni Models, meaning VLMs with audio and video support, on a Mac using MLX. It is MIT licensed and requires Python 3.10 or newer.
How do I install mlx-vlm?
Run pip install -U mlx-vlm. The Gradio chat UI needs one more step, pip install -U 'mlx-vlm[ui]', and the quotes matter because shells such as zsh would otherwise treat [ui] as a glob pattern.
How do I use mlx-vlm once it is installed?
It installs eight console scripts: mlx_vlm.generate, mlx_vlm.chat, mlx_vlm.chat_ui, mlx_vlm.server, mlx_vlm.convert, mlx_vlm.decide, mlx_vlm.moe_offload, and mlx_vlm.train. There is also a Gradio chat UI, a Python script path, and a FastAPI server.
What is the difference between mlx-vlm and mlx-lm?
MLX-VLM defines itself as a package for Vision Language Models and Omni Models, meaning models with audio and video support, running on a Mac through MLX.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/blaizzy-mlx-vlm)Star history chart for your README
[](https://hysenlabs.com/projects/blaizzy-mlx-vlm)Was this useful?