bootandy/dust: a du replacement that reads the directory tree for you
A more intuitive version of du in rust
At a glance
- What is it?
- dust is a Rust disk usage tool that prints the largest directories without a sort or head pipe. It is easy to install and pleasant to read, but its output is a summary, not an audit.
- Who is it for?
- Adopt dust if you regularly ask where the space went on a machine you control and you want the answer in one command instead of a du pipe. Do not adopt it if you need to delete directories inside the tool, browse a remote filesystem interactively, or produce a byte-exact accounting of a tree.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
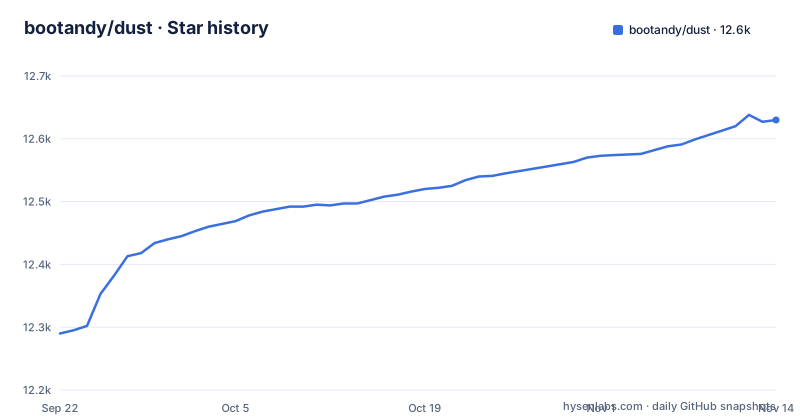
- bootandy/dust12,630 ★ · +340
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| bootandy/dust | 12.3k | 12.6k |
340 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What dust is for, and who ends up using it
The README states the motivation plainly: "Because I want an easy way to see where my disk is being used." That is the whole scope. dust answers one question, which directory is eating the disk, and it answers it in a single command with no pipeline.
The tool is aimed at people who already reach for du and then immediately reach for sort and head. In the classic workflow you run du -d 1 -h, pipe it through sort -h, and read the last ten lines. dust folds those three steps into one invocation and picks a sensible number of rows from the terminal height. The README also notes it will print a maximum of one permission-denied message, which matters on system directories where du can bury the useful output under a wall of errors.
It is a terminal tool for interactive use. There is no daemon, no index, no database, and nothing to keep running between invocations. That makes it a good fit for a developer laptop, a build server you have shell access to, and a container image where you want to know why the layer is large. It is a poor fit for anything that needs to run unattended and produce a stable, machine-readable report on a schedule.
How dust decides what to show
The mechanism is a parallel directory walk followed by a selection step. The README describes the behaviour as listing "a slightly-less-than-the-terminal-height number of the biggest subdirectories or files" and then recursing down the tree to find the larger entries. There is no need for a -d flag or a -h flag to get a readable result, although both exist.
The colouring carries information rather than decoration. The README explains that the shades of grey indicate which parent folder a subfolder belongs to, and that a light grey line running up from a bar shows the folders inside that parent. Deleting the parent removes everything the line connects. That is the part of the design worth understanding: the bars are a tree, not a flat ranked list.
One default is easy to misread. dust reports disk usage by default, and the -s flag switches to apparent size, which the README describes as showing "the length of the file as opposed to the amount of disk space it uses." On a filesystem with compression or large block sizes these two numbers diverge, and the divergence is often exactly what you are trying to find.
Installing dust and reading your first tree
The README lists a quick install script for Linux, macOS and Windows that pipes a remote shell script into sh. If you would rather not do that, the Cargo route is one line and builds from source:
cargo install du-dustThe crate is named du-dust while the binary is dust, which is a common source of confusion when searching package indexes. Homebrew users on macOS and Linux can install with brew install dust, Fedora users with sudo dnf install du-dust, and Windows users with scoop install dust. Prebuilt Linux and macOS binaries are attached to the GitHub releases, extracted with tar -xvf and moved into a directory on your PATH.
Once installed, run it against a directory:
dust -n 10You should see a ranked list of the largest directories under the current path, each with a percentage bar, capped at ten rows rather than your terminal height. The README suggests that newcomers tune the -n parameter first, giving dust -n 10 and dust -n 50 as examples, and demonstrates -d 2 for limiting depth in the project's demo.
To change the defaults permanently, dust reads a config file. The README gives this example:
reverse=true
limit-filesystem=true
That file lives at $XDG_CONFIG_HOME/dust/config.toml, falling back to ~/.config/dust/config.toml, or alternatively at ~/.dust.toml. Keys use the long flag name in kebab-case, and the repository ships a fuller sample at config/config.toml. If you set reverse=true there, every invocation flips its ordering, so check the sample before adding keys you do not recognise.
The flags that change the answer, not just the display
Most of the usage list is presentation: -p shows the full path of subdirectories, -r reverses the order of output, and -o picks the unit format such as si, b, kb, kib, mb, mib, gb or gib. These are safe to ignore until you need them.
A smaller set changes what gets counted or shown. -s switches to apparent size, and the README notes that dust will not count hard links multiple times unless you use -s. -F shows only files, which the README describes as the way to find your largest files, and -D does the opposite and shows only directories. -d sets how many levels of subdirectories appear, and -n sets how many entries are shown. The README stresses that -n is not quite like head -n or tail -n: dust -n 90 shows your 90 largest entries, chosen intelligently from the tree.
The config file makes choices permanent: the README's example sets reverse=true and limit-filesystem=true, using the long flag names in kebab-case.
Where dust stops being the right tool
dust does not delete anything. ncdu, which the README lists first among alternatives, is an interactive browser that lets you move through the tree and remove directories as you go. If your workflow is find the culprit and delete it in the same session, dust will hand you a path and you will run rm yourself. That is a deliberate design boundary, not a missing feature, but it changes the shape of the task.
The second limitation is the snap package. The README carries an explicit note that dust installed through snap can only access files stored in the /home directory, pointing to an upstream issue. If you install via snap and then scan a directory outside /home, you will not get the result you expect, and the cause is the packaging rather than the tool.
The third is the Windows MSVC build, which the README says requires VCRUNTIME140.dll, linking to Microsoft's redistributable page. The GNU build is described as working. On a clean Windows machine without the redistributable, the MSVC binary is the wrong download.
Finally, dust is a summary by construction. It deliberately shows only large entries and caps the row count at roughly terminal height. If you need every directory accounted for, or a total you can reconcile to the byte against df, this is the wrong instrument. The README's own alternative list ends with du -d 1 -h | sort -h, and for a one-off exact listing that pipeline is still correct.
dust against ncdu and dua
The README names ncdu, dutree, dua, pdu and dirstat-rs as alternatives, and the difference between the first two and dust is the clearest one to state.
ncdu is a full-screen interactive application. You start it, it scans, and then you navigate the tree with the keyboard, sorting and drilling down inside the interface. It holds the scan in memory and lets you act on it. dust prints a result and exits. The trade is real in both directions: ncdu gives you navigation and deletion but requires a session, while dust composes with the shell, works in a pipe, and leaves nothing running. For a quick check inside a script or over ssh in one command, dust is the shorter path.
dua, from the same list, is another Rust disk usage tool. The README does not compare the two beyond listing dua as an alternative, so the honest statement is that both are terminal disk usage tools written in Rust and the README does not document how they differ. Anyone choosing between them should read dua's own documentation rather than assume dust's summary behaviour applies there.
What dust argues for itself is stated in the README's own section heading, "Why to use Dust over the Alternatives": it claims to do the right thing when handling lots of small files and directories, and to keep output simple by showing only large entries. That is a claim about defaults, and it is the thing to evaluate against your own directory trees. A tree with a few enormous files and a tree with a hundred thousand small ones are different problems, and the second is where the default row cap and the recursive selection matter most.
Licence, maintenance and what an upgrade costs you
dust is licensed Apache-2.0, stated in the repository metadata and the Cargo.toml license field. The repository ships a LICENSE file at the top level, and the Debian packaging metadata in Cargo.toml installs that same LICENSE into usr/share/doc/du-dust. Apache-2.0 is a permissive licence with an explicit patent grant and a requirement to preserve notices. If you redistribute a binary, the notice obligation applies to you; that is a general property of the licence and not legal advice for your situation.
The repository is not archived, and the last push was on 2026-11-01, which is the same day as the v1.2.7 release. The recent tags are v1.2.5 on 2026-08-19, v1.2.6 on 2026-09-16, then v1.2.7 on 2026-11-01. Three releases in about ten weeks is a pattern worth knowing if you are pinning a version in a build image.
Upgrade cost is low by design. There is no server component, no migration, no state on disk beyond an optional config file. The realistic upgrade risk is in that config file: keys use the long flag name in kebab-case, so a flag that gets renamed upstream silently stops taking effect rather than failing loudly. If you maintain a config.toml, re-read config/config.toml in the repository after a major bump. The dependency set in Cargo.toml is broad for a tool this size, including clap, rayon, regex, serde and sysinfo, so a cargo install from source pulls a substantial tree and takes longer than the binary download.
Editorial conclusion
Adopt dust if you regularly ask where the space went on a machine you control and you want the answer in one command instead of a du pipe. Do not adopt it if you need to delete directories inside the tool, browse a remote filesystem interactively, or produce a byte-exact accounting of a tree. Before relying on it, verify one thing: whether the sizes it reports are disk usage or apparent size, because the default and the -s flag disagree, and that difference decides whether the number matches your df output.
Frequently asked questions
Is dust faster than du?
The README does not make a speed claim against du, and no benchmark is published in the repository. Its claim is about output rather than speed: it gives an instant overview of which directories use space without requiring sort or head. Treat any speed expectation as workload-dependent and test it on your own filesystem.
What is du-dust?
du-dust is the package name of the dust project, while the installed binary is called dust. The Cargo.toml sets name = "du-dust" and declares a binary target named dust, which is why cargo install du-dust is the correct command and why package indexes list it under the longer name.
What is dust in Linux?
dust is a command-line disk usage tool written in Rust that prints the largest directories or files under a path, ranked and sized to roughly your terminal height, so you do not need to pipe du through sort and head. The README describes it as "a more intuitive version of du" and says it will print a maximum of one permission-denied message.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/bootandy-dust)Star history chart for your README
[](https://hysenlabs.com/projects/bootandy-dust)Was this useful?