newspaper3k: Article Extraction in Python 3, and What It Leaves to You
newspaper3k is a news, full-text, and article metadata extraction in Python 3. Advanced docs:
At a glance
- What is it?
- newspaper3k turns a news URL into title, authors, text, top image and keywords through an Article object, and can crawl a whole news source. It does not find URLs by topic and it does not get you past IP blocks.
- Who is it for?
- newspaper3k fits scripts that already have article URLs or a news homepage and need clean text, authors and dates from them. It is a poor fit if you need topic-based URL discovery, guaranteed access to blocking sites, or a release history you can audit, because discovery and proxies are left to other services and the only GitHub releases date from 2014.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 19 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
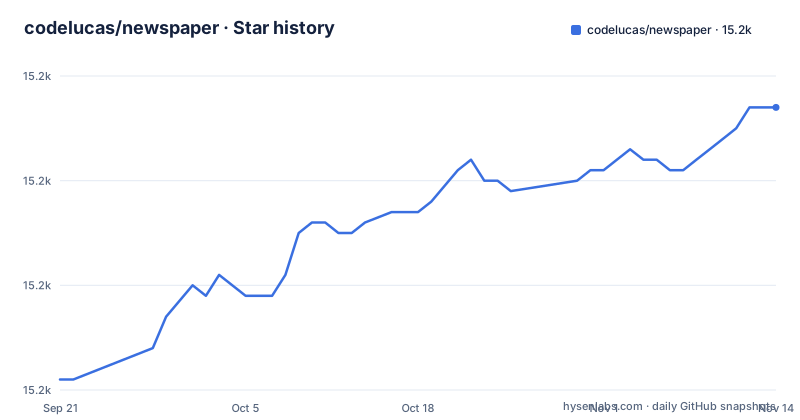
- codelucas/newspaper15,187 ★ · +26
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| codelucas/newspaper | 15.2k | 15.2k |
26 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Download, parse and nlp are three separate calls on one Article
The core of newspaper3k is the `Article` class, and it deliberately does not do everything in one step. You build the object from a URL, fetch the page, and only then analyse it. The README walks through it in that order.
>>> from newspaper import Article
>>> article = Article(url)
>>> article.download()
>>> article.parse()
After `download()`, `article.html` holds the raw page. After `parse()`, you get `article.authors`, `article.publish_date`, `article.text`, `article.top_image` and `article.movies`. Keywords and a summary come from a third call, `article.nlp()`, which fills `article.keywords` and `article.summary`.
The consequence is that reading `article.text` before `parse()` gives you nothing useful, and reading `article.summary` before `nlp()` does the same. If a script only needs the body text, you can skip `nlp()` and avoid its extra work. If the download fails, there is no HTML to parse, so error handling belongs around the first call, not the later ones.
build() crawls a whole source but hands you URLs, not downloaded articles
For sites you want to monitor, `newspaper.build()` takes a homepage and returns a source object. In the README example, `cnn_paper = newspaper.build('http://cnn.com')` gives you `cnn_paper.articles`, a list you can loop over to print each `article.url`, and `cnn_paper.category_urls()`, which lists section addresses such as `http://cnn.com/world` and `http://tech.cnn.com`.
The list that comes back is a list of candidate articles. Each one still has to go through the same sequence as a standalone Article: `cnn_article.download()`, then `cnn_article.parse()`, then `cnn_article.nlp()` if you want keywords. Building the source does not fetch every article's text up front.
That split is useful for control, since you decide how many articles to pull and at what pace. It also means a naive loop over thousands of articles makes thousands of requests from your machine, one after another, which is exactly the situation that triggers the blocking problems described further down. The library gives you the map of a site, not a polite crawl schedule.
fulltext() lets you skip the downloader when you already hold the HTML
Not every pipeline wants newspaper3k to fetch pages. Some already have HTML from another client, a cache, or a headless browser. For that case the README shows `from newspaper import fulltext`, followed by passing HTML text into it and getting the article text back.
It matters because the built-in download step is the part most exposed to blocking. If a site serves different markup to a browser than to a plain HTTP client, you can fetch the page with the tool that works and still use newspaper3k only for extraction. In the README example the HTML comes from `requests.get(...).text`.
What you give up is everything that came with the Article object. A bare string in and a string out means no `authors`, no `publish_date` and no `top_image`. If you want those metadata fields, you need the Article path, which means letting the library do the download or finding another way to feed it the page.
Language detection is automatic for one article but a single setting for a whole source
If no language is specified, newspaper3k attempts to auto detect one. You can also state it: `Article(url, language='zh')` for Chinese, with the README example pulling a BBC Chinese article and printing the title and the first 150 characters of text.
For a whole source the same parameter exists on `build()`. The README's example is `newspaper.build('http://www.sina.com.cn/', language='zh')`, and it comes with a condition: use it only if you are certain that an entire news source is in one language.
That condition is the limit. A site that mixes languages, such as a portal with English and Chinese sections, will be treated with one language setting for everything you build from it. The consequence is wrong tokenisation or poor keyword and summary output for the minority language pages, and the library offers no per-article switch inside `build()`. If your target mixes languages, either leave detection on or build separate sources for the separate sections.
The dependency list carries language segmenters and loose version floors
The requirements file shows why installing this library is heavier than a plain HTML parser. Beyond `beautifulsoup4`, `lxml` and `requests`, it pulls in `nltk`, `Pillow`, `feedparser`, `feedfinder2`, `tldextract`, `PyYAML` and `python-dateutil`, plus language tools: `jieba3k` for Chinese, `pythainlp` for Thai and `tinysegmenter==0.3`.
That last line is the only exact pin, and it carries a comment: `# TODO(codelucas): Investigate making this >=0.3`. Every other entry is a lower bound such as `lxml>=3.6.0` or `requests>=2.10.0`, with no upper limit. The floors are old versions, and the file does not tell you which newer releases of those packages have been tried together.
In practice, you install into a fresh virtual environment and test your own pages, because an unbounded `nltk` or `Pillow` can move under you. The repository also contains a `download_corpora.py` script at the top level, so expect some language data to be fetched separately from the pip install. The package itself is named `newspaper3k`, and the installer in `setup.py` points Python 3 users at `pip3 install newspaper3k`.
Finding article URLs by topic is outside the library, so the README points you at SerpApi
The README is direct about a gap. `newspaper.build()` suits cases where you know which sites to crawl. When the question is "I want every article about X across all publications", you first need URLs, and newspaper3k does not search.
Its suggested answer is a third-party service: query Google News through SerpApi's Google News API, then hand the result links to newspaper for extraction. The example installs `google-search-results` with `# pip3 install google-search-results`, builds a `GoogleSearch` with `"engine": "google_news"`, a query such as `"electric vehicles"` and an `api_key` placeholder, and loops over `news_results`, running `Article(result["link"])` through download, parse and nlp.
Two things follow. You need a SerpApi account and key, and the README comment says there is a free plan at serpapi.com; limits and prices are set by that service, not by this repository. And the section is the author's own recommendation with tracking parameters in the links, so read it as a pairing suggestion rather than a built-in feature. Without that external step, newspaper3k only extracts from URLs you already have.
Blocking is your problem: config.proxies exists, but the proxy advice is a vendor pitch
The README names the wall every scraper hits: 403s, captchas, rate limits and silent shadow bans. Its stated cause is the IP address, and its proposed fix is rotating residential proxies.
The library does give you the hooks. A `Config` object has `config.proxies`, a dictionary with `http` and `https` entries pointing at a proxy gateway, and `config.browser_user_agent`, which the README fills with a Chrome-on-macOS string and notes that a real browser user agent helps. The example goes on to set a request timeout on the same `Config` object, so check the library's own docs for that option's exact name and default before relying on it.
The section is written in the first person and recommends one named proxy provider, quoting that provider's own figures for IP count, countries and success rate. Those are the vendor's claims, not measurements of newspaper3k, and the library does not rotate proxies or solve captchas itself. If a target blocks you, setting proxies and a user agent is all the library offers; everything beyond that is your own infrastructure and your own responsibility for what you scrape.
GitHub releases stop at 0.0.9 in 2014 while setup.py claims 0.3.0
The release trail is confusing and worth checking before you depend on it. The two GitHub releases are 0.0.9, titled End of Python 2 support, dated 2014-12-17, and 0.0.8, titled Bugfixes, better documentation, dated 2014-10-13. Meanwhile `setup.py` sets `version='0.3.0'` and the package name `newspaper3k`, with a `publish` argument that builds an sdist and wheel and uploads with twine.
So the version you get from pip is not described by any GitHub release. To know what changed between the numbers, the repository has a `CHANGELOG.md`, and its content is not reproduced in the README text.
On activity, the repository was last pushed on 2026-10-26, so the default branch `master` has recent commits, but a push date is not a statement about releases or support. The README calls the Python 2 branch deprecated and buggy, and `setup.py` exits with a warning if you try to install the Python 3 package on Python 2. The CI badge points at Travis, which is a sign of how old the setup is. The code is MIT licensed, and a `GOOSE-LICENSE.txt` file sits next to the main `LICENSE`.
Editorial conclusion
newspaper3k fits scripts that already have article URLs or a news homepage and need clean text, authors and dates from them. It is a poor fit if you need topic-based URL discovery, guaranteed access to blocking sites, or a release history you can audit, because discovery and proxies are left to other services and the only GitHub releases date from 2014.
Frequently asked questions
What does newspaper mean in the newspaper3k library?
Here it is not a printed paper. Newspaper is a Python 3 library, described as news, full-text, and article metadata extraction, installed under the package name newspaper3k.
How do I install newspaper3k?
The installer message in setup.py points Python 3 users to pip3 install newspaper3k. The Python 2 package is installed with pip install newspaper, and that branch is described as deprecated and buggy.
Can newspaper3k extract articles in languages other than English?
Yes. It auto detects the language if none is given, or you can pass language='zh' to Article or build(). Use the build() setting only if an entire source is in one language.
Does newspaper3k find articles about a topic on its own?
No. The README suggests searching Google News through SerpApi first and then passing the result links to Article for extraction.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/codelucas-newspaper)Star history chart for your README
[](https://hysenlabs.com/projects/codelucas-newspaper)Was this useful?