commaai/research: The 7-Hour Driving Dataset Behind a 2016 Autonomy Paper
GitHub describes it as dataset and code for 2016 paper "Learning a Driving Simulator". The repository metadata lists Python as its primary language. The metadata lists the BSD-3-Clause license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- This repository holds the comma.ai driving dataset and code for the 2016 paper 'Learning a Driving Simulator'. It offers 7.25 hours of highway driving data and two example experiments, but its age and dependencies make it a research artifact rather than a production toolkit.
- Who is it for?
- Adopt this repository if you need a real, recorded highway driving dataset for academic or non-commercial research, especially for steering angle prediction or generative driving scenes. Do not use it for production autonomy or commercial work, because the dataset license forbids commercial use and the code targets obsolete TensorFlow 0.9 and Keras 1.0.6.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 51 months ago, on August 16, 2022.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
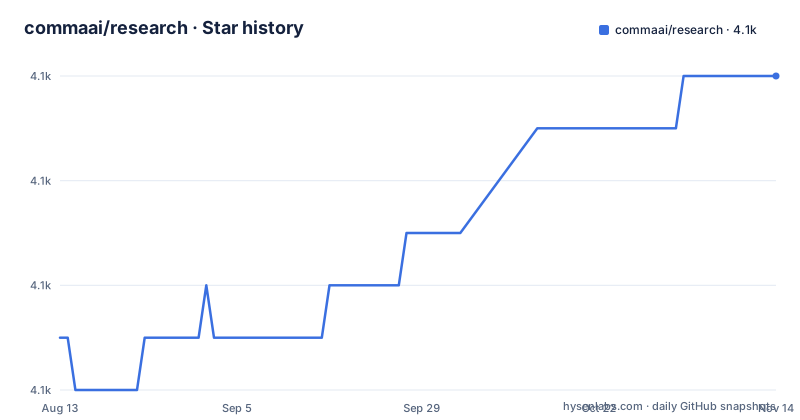
- commaai/research4,128 ★ · +5
| Repository | 2026-08-13 | 2026-11-14 |
|---|---|---|
| commaai/research | 4.1k | 4.1k |
5 Stars in the last 93 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A Snapshot of 2016 Driving Data
The dataset is split into 10 video clips, named after the driver and timestamp, for example dog/2016-01-30--11-24-51. Sizes range from 2.7 GB to 13 GB, totaling around 45 GB compressed and 80 GB uncompressed. The camera captures at 20 Hz, and the log measurements are resampled to a uniform 100 Hz time base. This dual rate is a core design choice: it gives fine-grained vehicle telemetry while keeping image storage manageable. The log includes speed, acceleration, steering angle, GPS, and gyroscope angles. A pointer dataset called cam1_ptr aligns camera frames with the other measurements.
The Mechanism: HDF5 Files and the cam1_ptr Alignment
Data is stored in HDF5 format. The camera dataset has shape number_frames x 3 x 160 x 320 with uint8 type. The log dataset contains the telemetry. The alignment between the two is handled by cam1_ptr, an HDF5 dataset inside the log file. This pointer tells you which log index corresponds to each camera frame. Without it, you would have to guess the time offset between video and measurements. The repository provides the data structure and the pointer, but the README does not explain how to use cam1_ptr in code. You have to infer that from the example markdown files, which are not included in the README excerpt. That is a gap. The mechanism is simple, but the documentation is thin.
Two Example Experiments: Steering and DriveSim
The README points to two markdown files that demonstrate possible uses. SelfSteering.md trains a steering angle predictor from the camera and log data. DriveSim.md trains a generative image model. These are the only code examples described. The repository likely contains Python scripts to run these experiments, but the README does not list them. The examples are meant to show that the dataset can support both supervised regression (steering) and unsupervised generative modeling. That is a broad range. The generative model is interesting because it suggests learning a simulator from real driving data, which is the paper's thesis. The steering predictor is more conventional. The README does not include results or metrics, so you cannot judge quality from this material alone.
Getting It Running: Commands and Dependencies
To download the dataset, you run ./get_data.sh or fetch it from the archive.org comma dataset page. The script is not shown in the README, but it exists in the repository. The dependencies are anaconda, TensorFlow 0.9, Keras 1.0.6, and OpenCV (cv2). These versions are old. TensorFlow 0.9 was released in 2016, and Keras 1.0.6 is equally dated. Installing them today on a modern Python environment will likely fail or require workarounds. The README does not provide installation instructions beyond listing the requirements. This is a real barrier. If you want to run the examples, you may need to create a separate environment with legacy package versions. The code may also depend on Python 2, which is no longer supported. You should verify that before attempting to run anything.
Licensing: Non-Commercial and ShareAlike
The license is not just a formality. It changes who can use this repository. Academic researchers and hobbyists can use it freely, as long as they share derivatives. A startup or a self-driving car company cannot. The README also includes a hiring pitch, asking people to show 'amazing stuff' on the dataset. That reinforces the research and recruiting intent, not a production-ready library.
Limitations: Old Code, No Releases, and a Single Vehicle
The biggest limitation is the age of the dependencies. TensorFlow 0.9 and Keras 1.0.6 are long obsolete. The code may not run on current hardware or software without significant changes. The repository has no releases, so there is no versioned snapshot to rely on. The dataset comes from a single vehicle, the Acura ILX 2016, and a single camera setup. That limits generalization. The driving is largely highway, so urban or off-road scenarios are absent. The recording rate of 20 Hz for camera and 100 Hz for logs is fixed; you cannot change it without resampling. The README does not mention any preprocessing or cleaning steps, so the data may contain raw sensor noise. For a modern project, you would need to validate the data quality yourself. The archive.org link may also change over time, so the download script could break.
Alternatives: The udacity and nuScenes Datasets
A common alternative is the Udacity self-driving car dataset, which also provides camera images and steering angles. Udacity's dataset is larger and has been used in many competitions. The key difference is licensing: Udacity's dataset is public domain, so it can be used commercially without restriction. Another alternative is the nuScenes dataset from Motional, which offers multi-modal sensor data including lidar, radar, and cameras, with full 360-degree coverage. nuScenes is more modern and includes annotations for object detection, but it requires registration and has a non-commercial license for some versions. Compared to commaai/research, nuScenes is much larger and more complex, but it also requires more storage and compute. If you need a simple steering angle dataset for a quick experiment, commaai/research is fine. If you need commercial use or modern sensor modalities, choose Udacity or nuScenes.
Maintenance and Upgrade Cost
The repository is not maintained. There are no recent releases and the last push is unknown. The README does not mention any update plans. The code depends on packages that are no longer supported, so upgrading to current versions of TensorFlow or Keras would require rewriting the model definitions and data loading code. The HDF5 format is stable, so the data itself will remain readable. But the example scripts, if they exist, likely use old APIs. The upgrade cost is non-trivial. You would need to port the code to a modern deep learning framework, which could take days or weeks depending on your experience. The dataset itself, once downloaded, is a static asset. The maintenance burden is on you, not the project.
Editorial conclusion
Adopt this repository if you need a real, recorded highway driving dataset for academic or non-commercial research, especially for steering angle prediction or generative driving scenes. Do not use it for production autonomy or commercial work, because the dataset license forbids commercial use and the code targets obsolete TensorFlow 0.9 and Keras 1.0.6. Before starting, verify the download script still works and check the archive.org link for integrity. Then decide whether the 20 Hz camera and 100 Hz logs match your needs, or look for a newer dataset with permissive licensing.
Frequently asked questions
What is the commaai research dataset?
Seven and a quarter hours of largely highway driving, recorded at 20 Hz from a camera mounted on the windshield of a 2016 Acura ILX, with speed, acceleration, steering angle, GPS coordinates and gyroscope angles recorded in parallel and transformed to a 100 Hz time base. It comes as 45 GB compressed, 80 GB uncompressed.
What licence applies to the commaai driving dataset?
The data is copyrighted by comma.ai and published under Creative Commons Attribution-NonCommercial-ShareAlike 3.0, so you must attribute it, may not use it commercially, and must distribute derivatives under the same licence. The code in the repository is separately licensed BSD-3-Clause, which is a different and more permissive set of terms.
What are the machine learning experiments in commaai/research?
Two. One trains a steering angle predictor and the other trains a generative image model, which is what the paper Learning a Driving Simulator is about. Each has its own markdown document and its own training and viewing scripts, and the repository also includes a Dask-based data generator and a server script.
Can I run the code in commaai/research today?
Not as documented. The requirements name TensorFlow 0.9 and Keras 1.0.6, both 2016 releases, along with Anaconda and OpenCV 3. The repository has no GitHub releases and its last push was on 2022-08-16, so there is no tagged version to install and the environment it was written for no longer exists.
How do I download the commaai dataset?
Run the included script, which is get_data.sh, or use the copy hosted on archive.org. Either way the data arrives as timestamped directories grouped by driver, in segments ranging from 2.7 GB to 13 GB, and it has to be extracted before use.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/commaai-research)Star history chart for your README
[](https://hysenlabs.com/projects/commaai-research)Was this useful?