Easy Dataset: A GUI Pipeline for Turning Documents into LLM Training and Eval Sets
A powerful tool for creating datasets for LLM fine-tuning, RAG and evaluation.
At a glance
- What is it?
- Easy Dataset is an application, offered as desktop clients and as a self-hosted web app, for converting PDFs, Markdown, and other documents into structured datasets for fine-tuning, RAG, and evaluation. It bundles parsing, QA generation, and an eval harness, but its unclassified license and reliance on external LLM APIs shape where it fits.
- Who is it for?
- Adopt Easy Dataset if you need a visual, low-code way to turn domain documents into QA pairs or evaluation sets and you can run a desktop app. Skip it if you need to run dataset creation without any GUI, or want to avoid sending document content to third-party LLM APIs.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
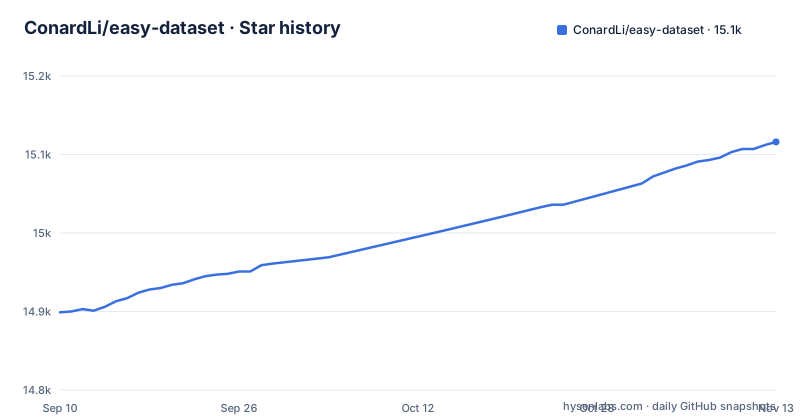
- ConardLi/easy-dataset15,116 ★ · +217
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| ConardLi/easy-dataset | 14.9k | 15.1k |
217 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Easy Dataset Actually Solves
Building a fine-tuning dataset from raw documents is tedious. You have to parse PDFs, split text sensibly, write questions, generate answers, and then format everything for a trainer like LLaMA Factory. Easy Dataset is an application, available as desktop clients or a local web app, that tries to automate that whole chain. It targets engineers and non-technical users who need structured QA data from domain-specific documents. The README lists three use cases: model fine-tuning, retrieval-augmented generation (RAG), and model evaluation. For RAG, the output is likely used to test retrieval quality, though the README does not detail how the exported data maps to a RAG benchmark. The tool also includes an evaluation system, so you can generate test questions and run model comparisons. That makes it a one-stop shop for dataset creation and assessment, which is unusual. Most open-source tools in this space do one side, either generation or evaluation, not both in a single GUI.
The Pipeline: From PDF to QA Pairs
The core workflow is visible from the feature list. You start by importing documents in PDF, Markdown, DOCX, TXT, or EPUB format. The tool applies intelligent text splitting, with multiple algorithms: Markdown structure, recursive separators, fixed length, and code-aware chunking. You can visually adjust the segmentation. Next, it generates questions from text segments using an LLM API, with templates and batch generation. A domain label tree is built from the document structure, and the tool auto-tags content. Then it generates answers, including Chain of Thought, again via LLM API. Finally, data cleaning removes noise. The README mentions a data distillation feature that generates label trees and questions directly from domain topics, without uploading documents. That suggests you can bootstrap a dataset from a topic list alone. The whole process depends on external LLM calls for question and answer generation. The tool does not train or host models; it orchestrates APIs. That is a key architectural point: the quality of your dataset is bounded by the underlying LLM you connect.
Running It: Desktop Clients and Local Setup
The primary way to run Easy Dataset is to download a desktop client. The README provides links for Windows, macOS (Intel and M) and Linux (AppImage). It also documents running from source with npm on http://localhost:1717 and running the official Docker image ghcr.io/conardli/easy-dataset. After installing, you point the app at your documents and configure an LLM API. The README says it is compatible with all LLM APIs that follow the OpenAI format, and lists providers: OpenAI, MiniMax, Ollama, Zhipu AI, Alibaba Bailian, OpenRouter. For vision tasks like PDF parsing and image QA, it supports Gemini and Claude. So the setup is: install the app, add an API key, choose a model, and start generating. There is no command-line interface described. That lowers the barrier for non-technical users but makes it awkward for automated pipelines. If you want to run dataset generation in a CI/CD loop, you would need a different tool.
Export Formats and Integration Points
The output side matters because a dataset is useless if your trainer cannot read it. Easy Dataset exports to Alpaca, ShareGPT, and Multilingual-Thinking formats, in JSON or JSONL. Alpaca and ShareGPT are common fine-tuning formats, so that covers most open-source training stacks. The tool also generates a LLaMA Factory configuration file with one click, which is a concrete integration. For RAG evaluation, you can export test sets with question types like true/false, single-choice, multiple-choice, short-answer, and open-ended. There is a balanced export feature that lets you configure export counts per tag, which helps avoid class imbalance in your dataset. You can also upload datasets directly to Hugging Face Hub. These integrations are practical. They reduce the glue code you would otherwise write. The Multilingual-Thinking format is less standard, but its presence suggests support for reasoning-style datasets. The README does not give an example of the exported JSON structure, so you should verify the schema matches your trainer's expectations before committing.
Built-In Evaluation: More Than a Dataset Creator
Version 1.7.0 added an evaluation system, which is a significant expansion. You can generate evaluation datasets from documents and then run automated evaluation using a Judge Model. That judge model scores answers based on customizable rules. There is also a human blind test system, called Arena, which compares two models' answers double-blind. This is useful for post-fine-tuning evaluation, vertical domain model assessment, and RAG recall rate evaluation, as the README states. The tool also includes an AI quality assessment that scores and filters generated datasets. That means you can use the same tool to create a test set and then evaluate a model against it. The evaluation feature is not just a side add-on; it is central to the project's identity. However, the README does not specify how the judge model is selected or whether it can be a local model via Ollama. Given the OpenAI-compatible API support, you could likely point the judge at any compatible endpoint, but that is an inference, not a documented fact.
Limitations and Cases Where It Is the Wrong Fit
The first thing to settle is the license. The repository metadata reports it as NOASSERTION, meaning GitHub could not classify the LICENSE file at the repository root, so read that file before relying on the tool in a commercial product. Another limitation is that it is built around a graphical interface, whether a desktop client or the web app that the npm and Docker installs serve on port 1717. No command-line interface is described, so batch processing on a server still goes through that interface. The tool does have a task management center for background batch processing. Also, the quality of generated questions and answers depends entirely on the LLM API you configure. The tool does not include a local generation model by default, except through Ollama integration. That means you need internet access or a local Ollama setup, and you incur API costs. Finally, the README claims support for many document formats, but parsing quality for complex PDFs is always a risk. You should test with your own files before assuming the output is clean.
Alternatives: How the Approach Differs
The most direct alternative is to use a library like LlamaIndex or LangChain to build a custom dataset generation pipeline. Those frameworks give you programmatic control over document loading, splitting, and LLM calls. You write Python code, which is more flexible but requires engineering effort. Easy Dataset offers a GUI and visual segmentation, which libraries do not. Another alternative is the dataset generation tools that come with fine-tuning frameworks, such as LLaMA Factory's own data preparation scripts, but those are usually less comprehensive. There is also the approach of manual dataset curation, using tools like Label Studio for annotation. That is a human-in-the-loop process, which is more accurate but slower and not automated. The key difference is that Easy Dataset combines generation and evaluation in a desktop app, while library-based approaches are code-first and often separate generation from evaluation. If you prefer a visual interface and do not want to write code, Easy Dataset wins. If you need to integrate dataset creation into an automated ML pipeline, a code library is more appropriate.
Maintenance, Upgrades, and License Reality
The repository is active. The last push was 2026-05-01, and releases came out in 2026, with version 1.7.3 in April 2026. That suggests ongoing maintenance. The README mentions a documentation site and tutorial videos, which helps with onboarding. The GitHub API reports the license as NOASSERTION, meaning GitHub could not classify the LICENSE file. That is a red flag for legal review. You should open the repository and read the actual LICENSE file. The README also includes a donation link and star prompts, which is common but not relevant to technical evaluation. Upgrade cost is moderate: desktop users download new versions from the releases page. The Docker setup keeps data in the local-db and prisma folders mounted from the host. If you build a large dataset and the app changes its internal schema, you might have to redo work. The export formats are standard, so your final datasets are portable, but the intermediate project state may not be.
Editorial conclusion
Adopt Easy Dataset if you need a visual, low-code way to turn domain documents into QA pairs or evaluation sets and you can run a desktop app. Skip it if you need to run dataset creation without any GUI, or want to avoid sending document content to third-party LLM APIs. Before committing, verify which document formats your actual corpus uses, confirm your chosen LLM providers are supported, and test the export formats against your downstream fine-tuning or RAG pipeline. The project is actively maintained with recent releases, but read its LICENSE file first, since GitHub reports the license as NOASSERTION.
Frequently asked questions
What is easy-dataset?
An application for building datasets for large language models, covering fine-tuning, retrieval-augmented generation and evaluation. It parses documents in PDF, Markdown, DOCX, TXT and EPUB among others, splits them with several algorithms, generates questions from the segments, builds a domain label tree, and can generate answers with chain of thought. It is a Next.js application with an Electron desktop build and an official container image.
how to use easy dataset
Either download a desktop client for Windows, macOS on either processor, or Linux as an AppImage, or run it locally. From source, the sequence is clone the repository, change directory, install dependencies with npm, then build and start, and open port 1717 in a browser. The container route publishes the same port and mounts two directories for the local database and the database schema.
What model providers does easy-dataset support?
Any language model API that follows the OpenAI request format, which is the stated compatibility rule. Named providers include OpenAI, a Chinese model provider, an aggregator, a Chinese platform service and Ollama for local models. Vision models including Gemini and Claude are supported for PDF parsing and image question answering.
What formats can easy-dataset export?
Three named dataset formats with either JSON or JSON Lines files: Alpaca, ShareGPT and a multilingual reasoning format. There is also a balancing option that lets you set how many rows to export per label, a one-click configuration file generator for another fine-tuning framework, and a direct upload button to a public model hub.
What does the evaluation feature in easy-dataset do?
It arrived in version 1.7.0 and generates evaluation datasets rather than training ones: true or false, single choice, multiple choice, short answer and open-ended questions. A judge model scores answers against configurable rules, there is a double-blind arena comparing two models' answers, and an automatic quality score filters generated data. A testing playground compares up to three models at once.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/conardli-easy-dataset)Star history chart for your README
[](https://hysenlabs.com/projects/conardli-easy-dataset)Was this useful?