DataHub: a LinkedIn-born metadata graph whose newest Context features sit on the Cloud side
The Context Platform for your Data and AI Stack
At a glance
- What is it?
- DataHub is an Apache-2.0 metadata platform that ingests from 150+ systems into one graph with column-level lineage and serves it to people and AI agents. The self-hosted edition is real and usable, but the README's headline Context features are pitched under the managed Cloud product, so read the edition comparison before you plan around them.
- Who is it for?
- DataHub fits a data team that is willing to operate a multi-service stack and wants an Apache-2.0 metadata graph with lineage across many sources, plus an MCP server so agents can read it. It is a poor fit for anyone who expects a light single-binary catalog, or who is really shopping for Context Intelligence and Context Hub, which the README describes as part of DataHub Cloud.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
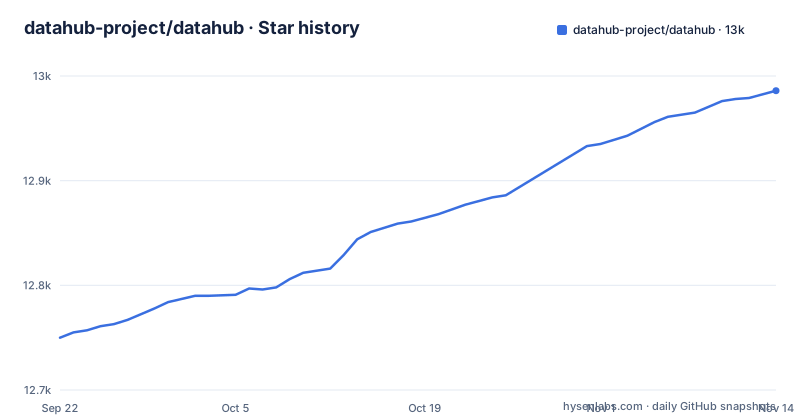
Star history
- datahub-project/datahub12,986 ★ · +236
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| datahub-project/datahub | 12.8k | 13k |
236 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One pip package drives the whole local Docker stack
The fastest self-hosted route goes through the Python CLI. The package on PyPI is acryl-datahub, and it installs the datahub command that pulls and starts the containers:
pip install acryl-datahub
datahub docker quickstart
Two prerequisites gate this: Docker with 8GB of RAM available to it, and Python 3.10 or newer. On a laptop where Docker Desktop is capped below 8GB, the quickstart is the step that struggles, not the pip install, so check the Docker memory allocation before blaming the CLI. When the stack is up, the web UI answers on http://localhost:9002 and accepts the username datahub with the password datahub. Those credentials are printed on the project's front page, so they are known to everyone. A quickstart instance is fine on a workstation, but forwarding port 9002 onto a shared network hands a working login to anyone who can reach it. For an installation other people will depend on, the project sends you to a separate Kubernetes deployment guide on docs.datahub.com instead of the quickstart. If you only want to click around the interface first, demo.datahub.com needs no installation at all.
The repository is a multi-service Gradle build, not a single Python library
GitHub labels the primary language Python, yet the top level of the repository shows a platform made of many cooperating parts. The user interface lives in datahub-frontend and datahub-web-react. The GraphQL layer is datahub-graphql-core. The backend spreads across metadata-service, metadata-io, metadata-dao-impl and metadata-jobs. Connectors sit in metadata-ingestion and metadata-ingestion-modules. The data model is defined in metadata-models, with metadata-models-custom and entity-registry next to it, and datahub-actions, datahub-upgrade and ingestion-scheduler round it out. The build is driven by Gradle, with build.gradle, gradlew, gradle.properties and buildSrc/ at the root and python-build/ beside them, while docker/ and datahub-kubernetes/ hold the packaging. The consequence for a reader who wants to patch something: building from source means working with the Gradle toolchain and several services at once, not editing one Python package. For running it, the published container images, such as acryldata/datahub-gms on Docker Hub, are the practical path. The root also carries AGENTS.md, CLAUDE.md, .cursor/ and .claude/, so the maintainers expect coding agents to be working inside this tree.
Lineage is only as complete as your connector coverage
Metadata enters through Context Ingestion, which pulls from 150+ integrations into a unified context graph. Named sources include dbt, Power BI, Confluence and Notion, so the graph is meant to hold documentation pages next to warehouse tables and BI dashboards. Column-level lineage is traced across those sources from origin to consumption. The project states its own dependency plainly: context is only as good as the lineage underneath it, and lineage is only as good as its coverage. Turn that around and you get the failure mode. If a system in your stack has no connector, its tables show up as a break in the lineage, and everything built on top of the graph, including impact analysis, search results and the context handed to agents, inherits the hole. Check docs.datahub.com/integrations for each of your real sources before you budget the project. The suggested next steps after the quickstart describe the intended workflow in order: ingest metadata with the CLI, search the catalog through the SDK search client, query lineage, then add documentation. On top of the graph sit discovery features (natural language search, profiling of schema, statistics, ownership and usage) and governance features (a business glossary that is owned and versioned, stewardship for every asset, access policies and compliance controls).
Context Intelligence and Context Hub are pitched under DataHub Cloud
The README offers two paths. DataHub OSS is self-hosted and Apache 2.0, with full access to the metadata graph, 150+ integrations, column-level lineage, governance and discovery, and it is described as best for teams comfortable running their own stack. DataHub Cloud is managed and SLA-backed, and it is the Cloud paragraph that names data observability and the full Context Platform: Context Intelligence, Context Hub and native agent integrations out of the box. Those are the most distinctive items on the page. Context Intelligence mines years of query history to build a semantic index of how an organization uses its data without manual authoring, and Context Hub is a workspace where domain experts review and approve AI-proposed context before any agent sees it. If those two features are the reason you are evaluating DataHub, do not assume the self-hosted build includes them. The Core capabilities section also lists Observability (quality assertions, freshness checks, SLA tracking, incident tracking) without marking which edition carries it. The project links a page comparing OSS and Cloud; read it feature by feature before committing engineering time. The opening paragraph of the README is about the company and its flagship DataHub Cloud, so much of the front page describes the commercial product rather than this repository.
Agents read the catalog through an MCP server launched with uvx
Context Activation is the delivery side of the platform: validated context goes out to agents through the Model Context Protocol, GraphQL, an API or an SDK. For MCP, the project ships a server you add to an MCP client such as Claude Desktop or Cursor:
uvx mcp-server-datahub@latestTwo practical points follow from that one line. First, the @latest tag resolves to whatever version is newest at launch, so two machines configured on different days can end up running different server versions; if you need repeatable agent behaviour, record which version you actually ran. Second, the MCP server serves what DataHub holds. An instance with nothing ingested gives the agent nothing useful to read, and an instance with gaps in lineage passes those gaps straight to the agent. The MCP setup guide lives at docs.datahub.com under the feature guides. The broader pitch is that you bring your own agents, your own LLM and your own stack, with MCP for agent delivery and GraphQL and REST for everything else, so DataHub does not require a particular model vendor on the consuming side.
Releases run on more than one version line at once
The project is under active development. The last push to the master branch was on 2026-10-31, and the release list shows three tags in a single week: v1.9.0rc1 on 2026-10-27, v1.6.0.4rc2 on 2026-10-29, and v1.6.0.4 on 2026-10-30. That is a patch release on the 1.6.0 line landing three days after a release candidate for 1.9.0. Two consequences matter for anyone running it. Version numbers alone do not tell you which line is newest in the sense you care about, since a 1.6 patch can be published after a 1.9 candidate, so read the release notes rather than sorting tags. And rc tags are release candidates, not final releases, so a production deployment should not track them by accident. Because the CLI comes from pip install acryl-datahub and the server comes from container images, write down the CLI version and the image tags you deployed together; the release list by itself does not tell you which line a fresh pip install resolves to on a given day. Apache-2.0 licensing applies to the repository regardless of which line you pick.
The adoption and ROI figures come from the vendor, not from the repository
The front page leans on numbers. It names Netflix, Visa, Etsy, Slack, Apple, FIS and Miro as production users, claims 3,000+ organizations, and points to an ADOPTERS.md file in the repository. It cites more than 16,000 community members, 750+ contributors and 10M+ assets managed in production. It also quotes an IDC study from March 2026: customers reporting text-to-SQL accuracy moving from 50% to 90% after connecting DataHub, 119% more AI/ML models reaching production, and search time for business users falling from 50 minutes to five, a 91% reduction. Those last figures are customer-reported and published on datahub.com/roi, the company's own site. None of them can be reproduced from the quickstart, and they say nothing about how your warehouse or your connector mix will behave. The history is more verifiable: DataHub started at LinkedIn in 2019 to manage metadata at very large scale, and the README credits both DataHub and LinkedIn as builders. Treat the adoption list as evidence that the project is used widely, and treat the accuracy and time-saving percentages as marketing claims to test on your own data.
Editorial conclusion
DataHub fits a data team that is willing to operate a multi-service stack and wants an Apache-2.0 metadata graph with lineage across many sources, plus an MCP server so agents can read it. It is a poor fit for anyone who expects a light single-binary catalog, or who is really shopping for Context Intelligence and Context Hub, which the README describes as part of DataHub Cloud. Before adopting, confirm that connectors exist for your actual sources, check the OSS versus Cloud comparison for every feature you need, and give Docker at least 8GB of RAM for the local trial.
Frequently asked questions
What is DataHub used for?
DataHub ingests metadata from 150+ integrations into one graph with column-level lineage, then provides search, governance features such as a business glossary and ownership, and serves that context to AI agents over MCP, GraphQL, an API or an SDK.
Who owns DataHub?
DataHub started at LinkedIn in 2019. The open source project is now built by the company DataHub, founded by the creators of the open source product, together with LinkedIn, and is released under Apache-2.0.
What companies use DataHub?
The README names Netflix, Visa, Etsy, Slack, Apple, FIS and Miro as production users and claims more than 3,000 organizations, with a longer list in the repository's ADOPTERS.md file.
How much is DataHub?
DataHub OSS is Apache-2.0 licensed and free to self-host on your own infrastructure. DataHub Cloud is the managed, SLA-backed edition and offers a free trial; the README does not list its prices.
How do I install the DataHub CLI?
Run pip install acryl-datahub with Python 3.10 or newer. Then datahub docker quickstart starts a local instance, which needs Docker with 8GB of RAM and serves the UI on localhost:9002.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/datahub-project-datahub)Star history chart for your README
[](https://hysenlabs.com/projects/datahub-project-datahub)Was this useful?