llm-twin-course: four Python services, one CDC-fed RAG pipeline
🤖 𝗟𝗲𝗮𝗿𝗻 for 𝗳𝗿𝗲𝗲 how to 𝗯𝘂𝗶𝗹𝗱 an end-to-end 𝗽𝗿𝗼𝗱𝘂𝗰𝘁𝗶𝗼𝗻-𝗿𝗲𝗮𝗱𝘆 𝗟𝗟𝗠 & 𝗥𝗔𝗚 𝘀𝘆𝘀𝘁𝗲𝗺 using 𝗟𝗟𝗠𝗢𝗽𝘀 best practices: ~ 𝘴𝘰𝘶𝘳𝘤𝘦 𝘤𝘰𝘥𝘦 + 12 𝘩𝘢𝘯𝘥𝘴-𝘰𝘯 𝘭𝘦𝘴𝘴𝘰𝘯𝘴
At a glance
- What is it?
- Decoding AI's free course builds an LLM twin of a person from their own writing across four Python microservices wired together by MongoDB change streams, RabbitMQ, Bytewax and SageMaker. The value is the wiring you can read; the cost is that fine-tuning and inference need a paid AWS account.
- Who is it for?
- Adopt it if you are an ML engineer who wants to read one coherent CDC-to-RAG implementation rather than stitch five separate tutorials together, and if your source data is the kind of public writing a crawler can reach. Skip it if you need inference on your own hardware, if your corpus already sits somewhere other than MongoDB with change streams enabled, or if the ten dollar AWS budget is the whole budget.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
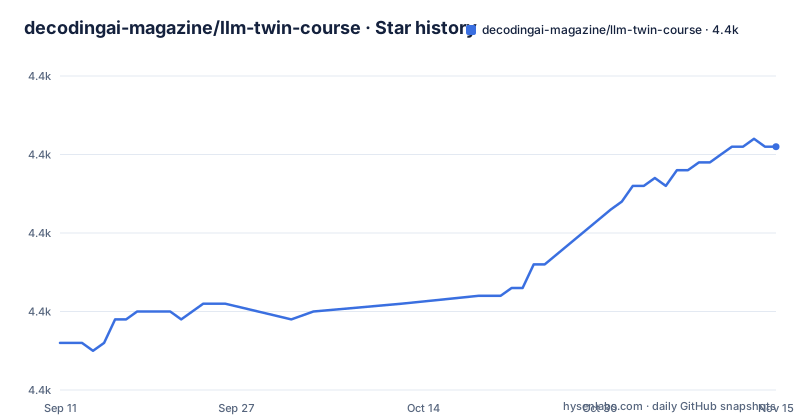
Star history
- decodingai-magazine/llm-twin-course4,411 ★ · +25
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| decodingai-magazine/llm-twin-course | 4.4k | 4.4k |
25 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the course actually builds: a writer, not a chatbot
The end product is an AI character that writes in the style of a named person. The source data is that person's own public writing, crawled from Medium, Substack and GitHub. The README names the target explicitly: an LLM twin that learns to write like somebody by folding their style and personality into a model.
The audience is narrow and stated plainly. ML and AI engineers who want production LLM and RAG engineering, plus data engineers, data scientists and software engineers who want to see what sits behind those systems. The README rules out one audience explicitly, saying the course focuses on engineering practices and end-to-end system implementation rather than theoretical model optimization or research. Nobody is going to learn a new fine-tuning method here.
Prerequisites are basic Python and machine learning, at intermediate level. The hardware line claims any modern laptop will do, because fine-tuning and inference run on AWS SageMaker. That claim is true and it is also the hidden dependency: the laptop does the orchestration, the bill goes to AWS.
Four microservices and the queue that couples them
The architecture splits into four Python services, and the interesting decision is how they talk. Data collection crawls the platforms, cleans and normalizes the text, and loads it into a MongoDB NoSQL database through ETL pipelines. Rather than polling the database, the service sends change events to a RabbitMQ queue using the change data capture pattern.
That single choice shapes everything downstream. A CDC event means the feature pipeline never needs to know what a crawler is. It consumes messages from the queue in real time through a Bytewax streaming pipeline, and for each message it cleans, chunks, embeds and loads the result into a Qdrant vector database. Each service can be rebuilt, restarted or rescaled without the others noticing.
The training service builds a custom instruction dataset from that collected data for supervised fine-tuning, fine-tunes with LoRA or QLoRA, logs experiments to a Comet ML tracker, evaluates with Opik, saves the best checkpoint to the Hugging Face model registry, and orchestrates itself on SageMaker. The inference service loads that checkpoint back out of the registry, serves it as a REST API through SageMaker inference endpoints, applies advanced RAG query rewriting, monitors prompts and outputs in Opik, and finishes with a Gradio UI.
The Makefile will not run until .env exists
Installation is a Poetry environment pinned to Python 3.11, which matches the ~3.11 constraint in pyproject.toml. The bonus RAG work lives in a separate dependency group, so the default install deliberately excludes it. Copy .env.example to .env first, though, because the Makefile includes that file on its very first line and exports everything in it. Without .env, no make target runs at all, including help.
poetry env use 3.11
poetry install --without superlinked_rag
The .env.example splits keys into two tiers. OpenAI, Hugging Face and Comet ML values are required even when working locally. Qdrant Cloud and the AWS credentials, including AWS_ARN_ROLE and AWS_REGION set to eu-central-1, are only needed when you move off local infrastructure. USE_QDRANT_CLOUD defaults to false, so a local Qdrant is the path of least resistance.
Start the local stack next. It brings up a three-node MongoDB replica set on ports 30001 through 30003, RabbitMQ with the management UI remapped to 15673, Qdrant on 6333, and a Lambda runtime on 9010 for the crawlers. The Makefile's local-start target runs:
docker compose -f docker-compose.yml up --build -dThat build is heavy. The crawlers image pins platform linux/amd64, so it runs under emulation on Apple Silicon.
Pinned Python libraries next to a Qdrant image tagged latest
Look at the dependency table and the version strategy is strict where it counts. opik is pinned to exactly 1.0.1 with no caret. huggingface-hub is pinned to 0.25.1. selenium is pinned to 4.21.0. sagemaker is the one loose end, declared >=2.232.2.
Now look at docker-compose.yml. mongo:5 and rabbitmq:3-management-alpine are pinned to major versions. qdrant/qdrant floats on the latest tag. A skipped-skim reader would miss this, because everything else in the repository behaves like a locked environment. In practice that means a qdrant client built against the 1.8.0 line can meet a vector server whose schema and gRPC behaviour moved underneath it, and the poetry.lock file cannot protect you from it, since the lock covers Python packages only.
One more version note worth carrying: Bytewax is not a main dependency at all. It sits in its own group at a fixed 0.18.2, alongside superlinked at ^7.2.1 in a third group. Swapping in the bonus path means changing which groups install, and the default install target leaves out only the superlinked_rag group.
Where the CDC handoff from Mongo to RabbitMQ breaks
The architecture has a specific failure mode, and it lives between MongoDB and RabbitMQ. Change data capture only fires on writes and updates.
The second break is quieter. The inference service reads from the Hugging Face model registry, and the training service pushes there.
A third boundary: the cost section is explicit that OpenAI runs about a dollar and AWS for fine-tuning and inference runs under ten dollars depending on how much you play with the scripts and your region. Ten dollars is a first-pass figure. Repeated LoRA runs on SageMaker endpoints do not stay at ten dollars.
What a single tuned model leaves on the table
The obvious alternative is to skip the fine-tuning pipeline entirely. Take the same crawled corpus, chunk it, embed it, and answer through retrieval alone, serving a general model behind an API. That approach trades the twin's learned voice for retrieval of the original sentences, which preserves facts but not the style.
The course goes the other way. It fine-tunes with LoRA or QLoRA on a custom instruction dataset built from the person's writing, then layers advanced RAG on top at inference time. Fine-tuning supplies the register; retrieval supplies the specifics the fine-tune never saw. The cost is that you now own two systems, a training pipeline and an inference pipeline, and both need to work.
The two bonus lessons change the retrieval side. They refactor cleaning, chunking and embedding with Superlinked, a vector compute engine, and load the vectors into Redis as a vector database, then rewrite the RAG layer to produce better queries.
An MIT repository of ten lessons and two bonus ones
There is no enrolment step. Code sits in this repository, articles sit on Decoding ML, and the whole course is free with ten hands-on lessons plus two bonus lessons on improving RAG. Cost sits with you: about a dollar for the OpenAI API and under ten dollars for AWS, with everything else inside a free tier.
Licensing is MIT and carries no copyleft obligation, so a service can be reused in your own repository.
The last push was on 2026-04-20, with no version history to anchor to beyond the lock file. Dependencies pinned to opik 1.0.1 and huggingface-hub 0.25.1 are the kind that need adjusting when the hosted services behind them change.
Editorial conclusion
Adopt it if you are an ML engineer who wants to read one coherent CDC-to-RAG implementation rather than stitch five separate tutorials together, and if your source data is the kind of public writing a crawler can reach. Skip it if you need inference on your own hardware, if your corpus already sits somewhere other than MongoDB with change streams enabled, or if the ten dollar AWS budget is the whole budget. Verify first that make install resolves on Python 3.11, because the Makefile includes .env before any target runs and fails outright when that file is missing.
Frequently asked questions
What is the llm-twin-course from Decoding AI?
It is a free, self-paced Python course that builds an LLM twin of a person from their own Medium, Substack and GitHub writing. The system spans four microservices and covers crawling, streaming feature engineering, LoRA fine-tuning and RAG inference.
Does llm-twin-course need paid cloud services to run?
Yes, for the training and inference stages, which run on AWS SageMaker. The README puts OpenAI at roughly one dollar and AWS at under ten dollars depending on how much you use the scripts and which region you pick.
What does llm-twin-course use for its vector database?
Qdrant is the default vector store for the feature pipeline. A USE_QDRANT_CLOUD flag in .env switches to Qdrant Cloud, and the bonus lessons move the vectors into Redis instead.
How do I install llm-twin-course locally?
Copy .env.example to .env first, because the Makefile includes that file before any target runs. Then make install creates a Poetry environment on Python 3.11 and installs dependencies without the superlinked_rag group.
Is llm-twin-course suitable for learning model research?
No. The README states the course focuses on engineering practices and end-to-end system implementation rather than theoretical model optimization or research. It assumes intermediate Python and machine learning knowledge.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/decodingai-magazine-llm-twin-course)Star history chart for your README
[](https://hysenlabs.com/projects/decodingai-magazine-llm-twin-course)Was this useful?