XGBoost 3.4: Distributed Gradient Boosting, Backends, and Limitations
Scalable, Portable and Distributed Gradient Boosting (GBDT, GBRT or GBM) Library, for Python, R, Java, Scala, C++ and more. Runs on single machine, Hadoop, Spark, Dask, Flink and DataFlow
At a glance
- What is it?
- XGBoost remains the reference implementation for gradient boosted trees, and the current 3.4.x line is receiving patch releases, most recently 3.4.2. This review covers what the project actually does, how the distributed backends fit together, and where its portability promise starts to fray.
- Who is it for?
- Adopt XGBoost if you need a mature, Apache-2.0 licensed gradient boosting library that runs on a single machine or across Spark, Dask, or Kubernetes. Do not adopt it if you need native support for neural network architectures or if your primary workload is deep learning on tabular data.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
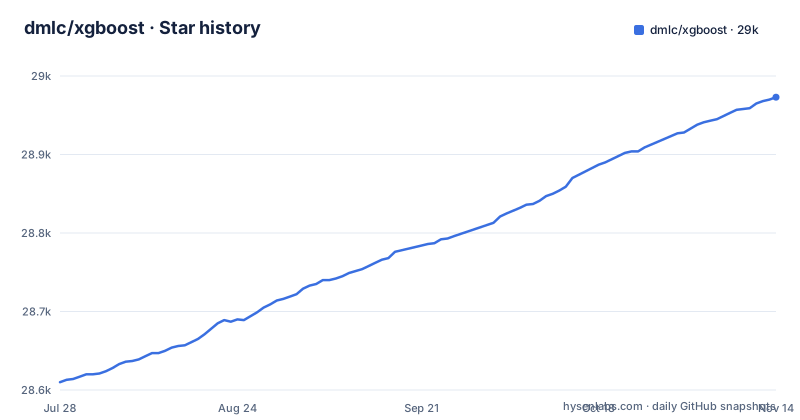
- dmlc/xgboost28,970 ★ · +360
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| dmlc/xgboost | 28.6k | 29k |
360 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What XGBoost Actually Solves
XGBoost solves a specific problem: training gradient boosted decision trees at scale, with a focus on speed and portability. The library implements the Gradient Boosting framework, which builds an ensemble of weak learners, typically trees, where each new tree corrects the errors of the previous ones. That approach dominates structured or tabular data problems, where it often beats deep learning models. The target user is a data scientist or engineer who has a dataset with rows and columns, needs a model that is both accurate and interpretable, and wants to run training on anything from a laptop to a multi-node cluster. The README explicitly mentions solving problems with billions of examples, which sets the scale expectation. It is not a general purpose machine learning library; it is a specialized tool for one family of algorithms.
The Mechanism: Parallel Tree Boosting and Distributed Execution
The core mechanism is parallel tree boosting. The portability claim comes from the fact that the same code runs on multiple distributed environments: Kubernetes, Hadoop, SGE, Dask, Spark, and PySpark. That is not a trivial promise. Each backend requires a different integration layer, and the project has to maintain those separately. The documentation and the paper referenced in the README describe the system as scalable and portable, but the practical behavior depends heavily on which backend you choose.
Getting It Running: Installation and First Steps
The README points to the official documentation for installation, but it also lists the package repositories. For Python, you can install xgboost from PyPI with pip install xgboost. For R, the package is available on CRAN. There are also conda packages for conda-forge under the name py-xgboost. The project is written in C++, and the Python and R packages are wrappers around the core library. That means you get the C++ performance without writing C++ yourself. The documentation is at xgboost.readthedocs.io, and the README links to a demo directory with examples. The README does not give a full code example, so you need to consult the docs for exact parameter names. The release notes for 3.4.0 and 3.4.1 are available through the documentation, and they are the place to check for breaking changes.
The 3.4.x Releases: What Changed and Why It Matters
The recent release history shows a steady cadence: 3.4.1 as a patch release on 15 August 2026, then 3.4.2 and 3.3.1 as patch releases on 15 September 2026. That distinction matters. A patch release implies bug fixes that do not add features but may change behavior. For a library as widely used as XGBoost, a patch release can be the difference between a model that trains correctly and one that silently produces wrong results. The README does not list the specific fixes, so you have to read the release notes. The last push, on 2 November 2026, suggests active maintenance. The project is not archived, and the default branch is master, which is typical for a mature project. The Apache-2.0 license is permissive, so you can use it in commercial products without paying a fee, but you must retain the copyright notice.
A Real Limitation: The Distributed Backends Are Not Interchangeable
The README's claim that the same code runs on Spark, Dask, and Kubernetes is true at the API level, but the operational reality is different. Each backend has its own cluster setup, its own failure modes, and its own performance characteristics. If you write code for Spark, moving it to Dask is not a one-line change. You have to rewrite the data loading and the training loop to match the new backend. The README does not address this, but it is a known trade-off in distributed machine learning. Also, the billion-example claim is a ceiling, not a guarantee. That scale requires a properly configured cluster, enough memory, and careful feature engineering. On a single machine, you are limited by RAM and CPU. XGBoost is the wrong tool if your data is truly massive and you cannot afford a cluster, or if your problem requires deep learning. For tabular data with millions of rows, it is often the best choice, but for image or text data, you should look elsewhere.
Alternative Approaches: LightGBM and CatBoost
The most direct alternative is LightGBM, which also implements gradient boosted trees. Another alternative is CatBoost, which handles categorical features natively and often requires less preprocessing. All three are open source and have similar licensing, so the choice often comes down to performance on your specific data and the ecosystem you already use. The README does not mention these competitors, but any engineer evaluating XGBoost should run a benchmark on their own data before committing.
Maintenance and Upgrade Cost
XGBoost has been under active development since its origin as a research project at the University of Washington. The README references the 2016 SIGKDD paper, which is a sign of academic grounding. The project has a contributor documentation page, which suggests a structured process for new contributors. The license is Apache-2.0, which is permissive and business friendly. The upgrade cost is moderate. Because the library is stable, you do not need to upgrade every release, but you should track the release notes for breaking changes. The 3.4.x series is a good example: if you are on the 3.3 line, upgrading to 3.4.2 gives you bug fixes but also requires retesting your training pipelines. The project has a CI infrastructure funded by sponsors, which is a positive sign for long-term maintenance. However, the README does not specify how long each version is supported, so you must plan your own upgrade cycle.
Editorial conclusion
Adopt XGBoost if you need a mature, Apache-2.0 licensed gradient boosting library that runs on a single machine or across Spark, Dask, or Kubernetes. Do not adopt it if you need native support for neural network architectures or if your primary workload is deep learning on tabular data. Before production use, verify the exact version you plan to deploy, because the 3.4.x patch releases fix bugs that may affect your training runs, and check the release notes for any changes to the distributed backends you rely on. The project's long history and active maintenance make it a safe default, but only if you confirm that your chosen backend and version are still supported.
Frequently asked questions
What is XGBoost used for?
XGBoost provides parallel tree boosting, also known as GBDT or GBM, implementing machine learning algorithms under the gradient boosting framework. The project describes it as solving many data science problems quickly and accurately, and the demos include multiclass classification, survival analysis, a C API example, a Dask example and two competition datasets.
Is XGBoost AI or ML?
The project frames it as machine learning. It states that XGBoost implements machine learning algorithms under the gradient boosting framework and calls itself a distributed gradient boosting library, with no claim of being an AI system in its own right.
Is XGBoost CPU or GPU?
The project page does not state hardware requirements, and it does not list a GPU enablement flag or a compute device option. There is an rmm_plugin example in the demos directory and NVIDIA appears among the sponsors, but sponsorship is stated to fund continuous integration and testing infrastructure rather than any particular feature.
Is XGBoost better than random forest?
The project makes no comparison, and nothing on the page supports one. It describes parallel tree boosting under the gradient boosting framework and says the same code runs on a single machine and on distributed environments including Kubernetes, Hadoop, Spark and Dask, which is a portability claim rather than an accuracy claim.
How do you install XGBoost?
The project page publishes no install command. It links to the Python package index, to CRAN for R, to the conda-forge channel, and to the hosted documentation, and it states the library is written in C++ and also available for Python, R, Java, Scala and more.
Official sources
Where this project is recommended
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Reverse Engineering Block Blastdev.to · Oct 31, 2026 · 6 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/dmlc-xgboost)Star history chart for your README
[](https://hysenlabs.com/projects/dmlc-xgboost)Was this useful?