TensorFlow: two stable language APIs, two pip package names, and a build table with gaps
TensorFlow supplies the tools to build, train, and deploy machine-learning models across servers, browsers, and edge devices.
At a glance
- What is it?
- TensorFlow is the end-to-end machine learning platform built by the Machine Intelligence team at Google Brain, with 2.22.0-rc0 as its newest release. The interesting parts for an adopter are the edges: Python and C++ carry the compatibility promise while other language APIs do not, the CPU-only build is a separate pip name, DirectX and MacOS-metal arrive as device plugins, and parts of the official build table have nothing behind them.
- Who is it for?
- TensorFlow is a defensible choice when your work sits on the Python or C++ API, or when you want a documented GPU path on Linux or Windows with CUDA. Be more careful if your code reaches it through another language, because the backward compatibility promise stops at those two.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
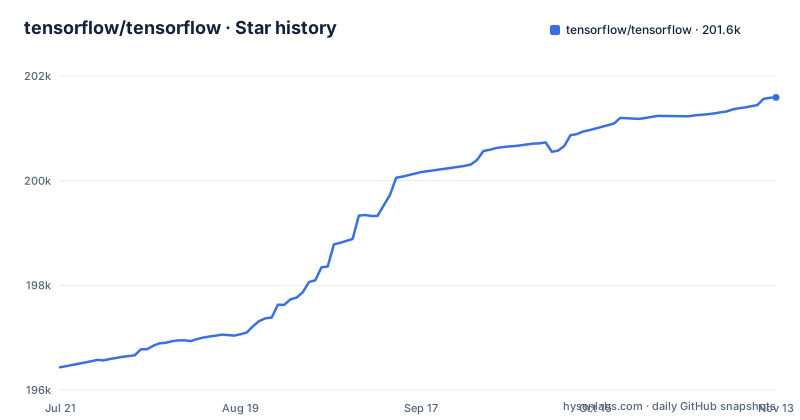
- tensorflow/tensorflow201,591 ★ · +5,157
| Repository | 2026-07-21 | 2026-11-13 |
|---|---|---|
| tensorflow/tensorflow | 196.4k | 201.6k |
5,157 Stars in the last 115 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The string constant in the project example comes back as bytes, not str
The fastest way to read TensorFlow's programming model is the snippet the project ships itself. You start a Python session, the first call is an add of 1 and 2, and the value is read straight back as a NumPy array, with no session object, no placeholder and no graph in between. Then the string case does something that catches people out. A constant built from a plain Python string reads back as b'Hello, TensorFlow!', with a b prefix, so what arrives is bytes rather than text, and the example passes no argument to change that. The consequence is that code which compares, decodes or formats that value expecting a str fails on the type rather than on anything TensorFlow reports, and nothing in the example hints that asking for a different type is your job.
The compatibility promise covers Python and C++ and stops there
The stability contract is drawn around two languages. The project calls the Python API stable and the C++ API stable, and describes the API offered for other languages as non-guaranteed backward compatible. That is a much narrower promise than the number of language bindings suggests, and no table is published saying which language tracks which TensorFlow release or how far behind a binding is allowed to fall. The release list shows 2.21.0 published on 2026-03-06 and 2.22.0-rc0 on 2026-09-24. The practical effect lands on the side of your system you did not choose. If training happens in Python and serving happens elsewhere, an upgrade can move underneath the serving layer without your training code changing, and you learn about it from that layer's behaviour rather than from a release note.
tensorflow and tensorflow-cpu are two names for the same library
The framework has two entry points on PyPI, and the choice between them is a decision rather than a preference:
pip install tensorflowThat is the current release, and it includes support for CUDA-enabled GPU cards on Ubuntu and Windows. If you do not want the GPU dependency or have no card, there is a separate, smaller package:
pip install tensorflow-cpuTo move an existing install to the newest version you add the --upgrade flag to either command. Sitting on top of both are the nightly channels, tf-nightly and tf-nightly-cpu, published for testing. Four names that all answer to TensorFlow is where the bookkeeping gets expensive: a requirements file, a container image and a colleague's machine can each sit on a different channel, and there is no version-to-channel table in the documentation to reconcile them against.
DirectX and MacOS-metal come from device plugins, not from the wheel
GPU support is not one story, and the split matters before you choose a machine. The pip package covers CUDA-enabled cards on Ubuntu and Windows, and everything else is handled separately: DirectX and MacOS-metal are supported using device plugins, with an available devices page behind that link. A Windows box without CUDA and an Apple Silicon laptop are therefore not the same install with a different flag switched on. They are cases where an extra component carries device support, and the core package on its own will not do the work. The consequence is that a GPU problem on either platform is a question about which plugin is installed and whether it matches your TensorFlow version, and the documentation does not say how plugin versions are pinned against core releases, so a core upgrade can quietly leave you with a plugin that no longer lines up.
Linux XLA lists no artifacts, and the Raspberry Pi rows point at 1.10.0 wheels
The continuous build table is worth reading closely, because two of its rows are not what a fast skim assumes. The Linux XLA row has TBA in its artifacts column, so nothing has been published from that line. The two Raspberry Pi rows, one for version 0 and 1 and one for version 2 and 3, link to wheel files named for TensorFlow 1.10.0 carrying a cp34 tag, which is a Python 3.4 wheel, hosted under the tensorflow-nightly storage path. So the row tells you a build is tracked for that hardware while the artefact behind it belongs to a much older release and interpreter. Read the whole table that way and it becomes a tracking document rather than a download list: a listed row does not mean the artefact behind it matches the current release.
Bugs, questions and requests go to three different queues
Support routing is explicit and split three ways. GitHub Issues is where requests and bugs are tracked, the TensorFlow Forum is for general questions and discussion, and Stack Overflow is for specific questions. That split creates a triage tax rather than removing one. A behaviour that looks like a defect belongs in Issues by that routing, while a question about environment or setup belongs on the forum, where it is easier to miss as a duplicate. The documentation does not describe what happens to an issue that turns out to be a question, or whether anyone redirects it, so a misplaced report can sit without a reply. The practical point is to read your own report against those three categories before filing, since each queue has a different stated purpose.
A patch for your version means cherry-picking onto r2.8 and building the wheel
The documented recipe for fixing a bug or a security problem in a version you already run is four steps, and it ends with you owning a build. Clone the repository, switch to the branch for the version you need, for example r2.8 for version 2.8, apply the change by cherry-picking it and resolve any conflicts, run the TensorFlow tests and make sure they pass, then build the pip package from source. Nothing in that sequence offers a way to hand the result back for publication or to have someone host it for you, and the final step drops you into the Bazel side of the project. The consequence for an operator is that a targeted fix stops being a version number and becomes a private artefact you have to test, distribute, and keep in step with every later upstream release, which is a heavier commitment than upgrading a wheel.
Patch notices go out by mailing list, and fuzz findings split into two queues
Two details in the header show how defects are handled at this scale. Release announcements and security updates are distributed by subscribing to the [email protected] mailing list, so staying current on patches means holding a subscription rather than watching a page. Next to that sit two separate oss-fuzz issue trackers, one filtered to proj:tensorflow and one filtered to proj:tensorflow-py, which means crashes in the core and crashes in the Python bindings are queued and triaged independently. The header also carries a Zenodo DOI, a Core Infrastructure Best Practices badge, an OpenSSF scorecard link and an OSSRank listing, and the tree carries SECURITY.md, ISSUES.md, CODEOWNERS and CODE_OF_CONDUCT.md. The useful takeaway is that a defect you report belongs to a queue you pick deliberately, and a fix you need is something you have to be subscribed to hear about.
Editorial conclusion
TensorFlow is a defensible choice when your work sits on the Python or C++ API, or when you want a documented GPU path on Linux or Windows with CUDA. Be more careful if your code reaches it through another language, because the backward compatibility promise stops at those two. Before you install, check which of the four package names you are actually pinning, and read the build table as a tracking document rather than a download list, since the Linux XLA row lists no artifacts and the Raspberry Pi rows still point at Python 3.4 wheels from the 1.10.0 era.
Frequently asked questions
What is TensorFlow used for?
It is an end-to-end open source platform for machine learning, with tools, libraries and community resources for building and deploying machine learning powered applications. It originally came from the Machine Intelligence team at Google Brain.
Is TensorFlow a library or a framework?
The project describes itself as an end-to-end platform rather than a single library, and it ships separate APIs: stable Python and C++ APIs, plus a non-guaranteed backward compatible API for other languages.
how to install tensorflow
Run pip install tensorflow for the current release with CUDA-enabled GPU support on Ubuntu and Windows, or pip install tensorflow-cpu for the smaller CPU-only package. Add --upgrade to update, and the project also publishes tf-nightly and tf-nightly-cpu for testing.
how to use tensorflow to train a model
The project ships an install guide, tutorials, and an API documentation site at tensorflow.org/api_docs. Its own first example imports the module as tf, calls tf.add(1, 2) and reads the result with .numpy(), so values are inspected as NumPy arrays rather than through a session.
how to use tensorflow with gpu
The current release from the tensorflow package supports CUDA-enabled GPU cards on Ubuntu and Windows. DirectX and MacOS-metal are supported separately using device plugins, and a smaller CPU-only package is published as tensorflow-cpu.
Is TensorFlow replaced by PyTorch?
The documentation makes no such claim. What it states is a support contract: the Python and C++ APIs are stable, while the API for other languages is described as non-guaranteed backward compatible.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tensorflow-tensorflow)Star history chart for your README
[](https://hysenlabs.com/projects/tensorflow-tensorflow)Was this useful?