XLA: the compiler three ML frameworks agree to share
A machine learning compiler for GPUs, CPUs, and ML accelerators. XLA XLA (Accelerated Linear Algebra) is an open-source machine learning (ML) compiler for GPUs, CPUs, and ML accelerators.
At a glance
- What is it?
- XLA is the Accelerated Linear Algebra compiler that takes models from PyTorch, TensorFlow and JAX and optimises them for GPUs, CPUs and other accelerators. Its README tells ordinary users not to clone it, the build carries both WORKSPACE and MODULE.bazel, and the project still sits under TensorFlow governance with no GitHub releases.
- Who is it for?
- Use XLA when you are an integrator, meaning you maintain a frontend, a hardware backend or a debugging path for models running on accelerators, because that is the audience the README names. Do not clone and build it to use it, since the README says outright that anyone not contributing code does not need to, and a framework's own documentation is the supported path.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
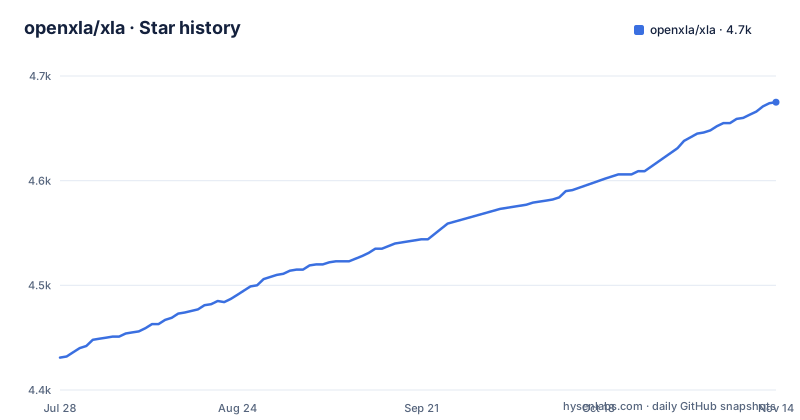
- openxla/xla4,675 ★ · +244
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| openxla/xla | 4.4k | 4.7k |
244 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The README tells ordinary users not to clone it
The most useful line in this README is a negative one. If you are not contributing code to the XLA compiler, you don't need to clone and build this repository.
Everything here is intended for two groups. The first is XLA contributors who want to develop the compiler. The second is what the README calls XLA integrators, who want to debug or add support for ML frontends and hardware backends.
That statement changes how you should read the rest of the documentation. There is no install section and no build command anywhere in the README, and that is not an omission. A machine learning compiler is not something an application imports; it is something a framework builds.
For anyone who does want to use XLA to compile a project, the README routes you to the documentation of your framework instead: PyTorch at pytorch.org/xla, TensorFlow at tensorflow.org/xla, and JAX through its own quickstart documentation. Three separate entry points, each maintained by the project that owns the frontend.
Three frontends, one compiler, and a hardware abstraction in between
XLA stands for Accelerated Linear Algebra, and it is described as an open-source machine learning compiler for GPUs, CPUs and ML accelerators.
The mechanism, as the README states it, is that the compiler takes models from popular ML frameworks such as PyTorch, TensorFlow and JAX and optimises them for high-performance execution across different hardware platforms, again GPUs, CPUs and ML accelerators.
Read that as a three-part structure: a frontend that hands the compiler a model, the compiler itself, and a hardware backend that executes the result. The reason the README addresses integrators separately from contributors is that the two jobs sit at opposite ends of that structure. A contributor changes the compiler; an integrator adds or debugs one of the ends.
The project's website is openxla.org, and the repository description says the same thing the README does, with the name XLA repeated twice before the expansion.
The build carries WORKSPACE and MODULE.bazel at the same time
The repository root describes a Bazel project in the middle of its own migration, and that is visible in the file names.
There is a `WORKSPACE` file for the legacy external dependency mechanism, a `MODULE.bazel` for the newer one, and five numbered files, `workspace0.bzl` through `workspace4.bzl`, which is the pattern used to split a large dependency declaration across files while keeping the legacy layout working.
Bazel configuration is spread across several places. There is `.bazelrc`, a `tensorflow.bazelrc` specific to TensorFlow builds, a `warnings.bazelrc` for warning handling, `.bazelversion` pinning the Bazel release, and `bazel_downloader.cfg` for fetching external dependencies.
Alongside that sit C++ tooling files that describe the same kind of discipline: `.clang-format`, `.clang-tidy` and a `.clangd` file for editor integration, plus a `.pre-commit-config.yaml` and a `.bant-macros` file.
`configure.py` is also present at the root.
Two Python lock files, one for 3.11 and one for 3.12
Among the Bazel machinery sit two requirements files: `requirements_lock_3_11.txt` and `requirements_lock_3_12.txt`.
Their names show that two Python interpreter versions are pinned with separate lock files rather than one range.
The repository's primary language is C++.
The rest of the root follows the same pattern of build infrastructure over source. There is `build_tools/`, `tools/`, `third_party/`, `docs/` and the `xla/` directory that holds the compiler, plus `BUILD.bazel` at the top level and `AUTHORS` and `AGENTS.md`.
Nothing in the README explains what the Python requirements are for, so an integrator who needs to run the build tooling will be reading the files rather than the documentation.
opensource_only.files marks the boundary of what can be released
One file in the root is unusual enough to be worth naming on its own: `opensource_only.files`.
The CI directory is the other signal. `.kokoro/` is present at the root, which is Google's internal continuous integration system exposed on GitHub, and it sits next to `.github/` for the workflows that run on the public side.
`GOVERNANCE.md` is not in the tree, while `CONTRIBUTING.md` is. Contribution process is documented, then, but governance is not, which is consistent with a project whose governance lives in the TensorFlow structure rather than in its own repository.
For anyone auditing what they would be building on, the file list and the presence of an internal CI directory are the two things to look at before the code.
SIG OpenXLA still answers to TensorFlow governance
The Code of Conduct section is the shortest in the README and it carries a governance fact. While under TensorFlow governance, all community spaces for SIG OpenXLA are subject to the TensorFlow Code of Conduct.
That is a stronger statement than a project having its own code of conduct. It means the community rules, and the process behind them, are inherited rather than defined locally, and a contributor joining SIG OpenXLA is joining a TensorFlow-governed group.
The contact section is correspondingly indirect: questions go to the maintainers, listed as maintainers at openxla.org. There is no issue template guidance, no chat channel and no mailing list in the README, only the community resources repository at github.com/openxla/community and the project website.
Contributing has two documents, `docs/contributing.md` titled How to Contribute, and `docs/developer_guide.md` as the developer guide. An `AGENTS.md` file also sits in the root, so there is machine-readable guidance for tooling in addition to the written guide.
The last push to the repository was on 2026-11-02, which tells you the compiler is still moving even though there is no release history here to show it.
No releases means versions arrive through the frameworks
The repository has no GitHub releases, and that is not unusual for a compiler that is consumed as part of a larger build.
In practice it means there is no tag to pin and no changelog to read on this repository. A PyTorch or TensorFlow build pulls a specific XLA revision, and the version you get is a property of that framework's release rather than of anything published here.
The consequence for evaluation is straightforward. If you want to know which XLA your model runs on, the question belongs to the framework you are using, and the answer is in that project's release notes rather than here.
The licence is Apache 2.0, with `LICENSE` in the root, which is the permissive end of the spectrum and about the only adoption fact this README settles on its own.
The primary language is C++, and the repository description names the same three hardware targets as the README, GPUs, CPUs and ML accelerators. Beyond that, the documentation burden sits with openxla.org and the three framework guides.
Editorial conclusion
Use XLA when you are an integrator, meaning you maintain a frontend, a hardware backend or a debugging path for models running on accelerators, because that is the audience the README names. Do not clone and build it to use it, since the README says outright that anyone not contributing code does not need to, and a framework's own documentation is the supported path. Before you start contributing, check three things: that your frontend or backend fits the interface the developer guide describes, that your Bazel version matches `.bazelversion` given that the tree carries both legacy `WORKSPACE` files and `MODULE.bazel`, and that you can work under the TensorFlow Code of Conduct, which the README says governs all community spaces for SIG OpenXLA.
Frequently asked questions
What is open xla?
OpenXLA is the project around XLA, Accelerated Linear Algebra, an open-source machine learning compiler for GPUs, CPUs and ML accelerators. The compiler takes models from frameworks such as PyTorch, TensorFlow and JAX and optimises them for execution across different hardware platforms. The compiler source is in this repository under the Apache 2.0 licence, and the project website is openxla.org.
What is Google XLA?
XLA stands for Accelerated Linear Algebra and is a machine learning compiler for GPUs, CPUs and ML accelerators, written primarily in C++. The README notes that the project is under TensorFlow governance, so all community spaces for SIG OpenXLA are subject to the TensorFlow Code of Conduct, and questions go to the maintainers listed at openxla.org.
xla vs openxla
XLA is the compiler, and this repository holds it. OpenXLA is the surrounding project and community, whose shared resources live in the openxla/community repository and whose website is openxla.org. If you are not contributing code, the README says you do not need to clone and build this repository, and it routes users to the documentation of PyTorch, TensorFlow or JAX instead.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Gemma 4 E2B in JAX on One TPU v5e: bf16 or 4-Bit, Python or Rust, and How It Stands Against vLLMdev.to · Nov 4, 2026 · 11 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openxla-xla)Star history chart for your README
[](https://hysenlabs.com/projects/openxla-xla)Was this useful?