SmartLLMLoader: LLM-Based Chunking for PDFs and Scanned Documents
smart-llm-loader is a lightweight yet powerful Python package that transforms any document into LLM-ready chunks. Spend less time on preprocessing headaches and more time building what matters. From RAG systems to chatbots to document Q&A, SmartLLMLoader handles the heavy lifting so you can focus on creating exceptional AI applications.
At a glance
- What is it?
- SmartLLMLoader wraps document conversion, OCR and chunking into one loader that calls a multimodal model through litellm. It is a reasonable fit for messy invoices and scans, and the wrong tool when you need deterministic, offline or cheap preprocessing.
- Who is it for?
- Adopt smart-llm-loader if your input is scanned or visually complex documents where a page-based splitter loses the table and header structure, and if you accept per-document model calls. Do not adopt it for large text-only corpora, offline environments, or pipelines that need byte-identical output across runs.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 104 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
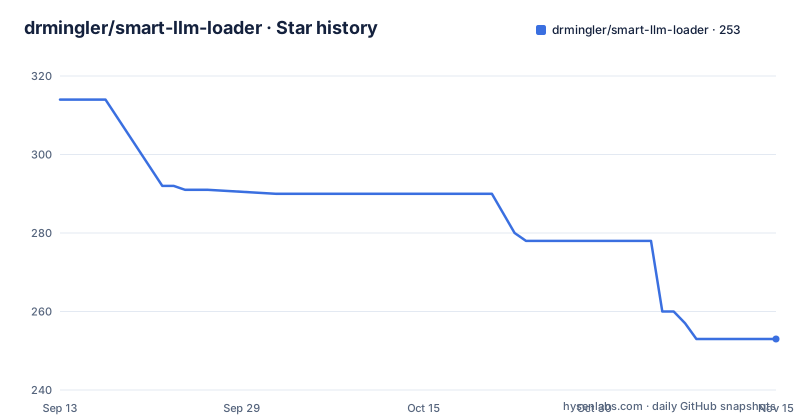
- drmingler/smart-llm-loader253 ★ · -61
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| drmingler/smart-llm-loader | 314 | 253 |
-61 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The preprocessing gap SmartLLMLoader targets
Most RAG pipelines break at the same place: the step between a file on disk and a list of text chunks. A PDF with a scanned invoice, a table of line items and a summary block does not survive a naive extractor. The README states the problem directly, saying the package "handles the entire document processing pipeline", and lists four stages: conversion to clean markdown, built-in OCR for scanned documents and images, context-aware chunking, and integration with LangChain and LlamaIndex. The intended user is someone building a document Q&A or chatbot system who would otherwise write glue code around pdfplumber, Tesseract and a recursive character splitter, then tune the splitter until tables stop getting cut in half. SmartLLMLoader's claim is that a multimodal model can do the segmentation and the semantic labelling in one pass, so the chunk boundaries follow the document's meaning rather than a character count. That is the whole proposition. It is not a retrieval library, not a vector store, and not an evaluation framework.
How the pipeline is wired: litellm, markdown, semantic themes
The loader subclasses LangChain's BaseLoader and exposes load_and_split(), which is the standard LangChain interface. Internally the package calls a multimodal model through litellm, and the README is explicit that "any arguments supported by litellm can be used", with a link to the litellm provider documentation. That single decision determines most of the package's behaviour. Your model choice is a string such as "gemini/gemini-1.5-flash", "openai/gpt-4o" or "anthropic/claude-3-5-sonnet", and the API key comes either from an environment variable in the provider's expected format (GEMINI_API_KEY, OPENAI_API_KEY, ANTHROPIC_API_KEY) or from the api_key constructor argument. The output is a list of LangChain Document objects. Each carries page_content and metadata. The README's invoice example shows the metadata fields in practice: page, source, and a semantic_theme string such as invoice_header, seller_information, client_information, items_table or summary_table. That theme label is the interesting part. A conventional splitter can only tell you which page a chunk came from. Here the model is also asked to name what the chunk is, which means downstream retrieval can filter on document structure rather than on similarity alone. The README notes the JSON in that example was reformatted for readability, so treat the exact field order as illustrative rather than contractual.
Installation and the Poppler dependency
Two installation steps are required, and the first is easy to miss. Poppler must be present for PDF processing. On Ubuntu or Debian the README gives sudo apt-get install poppler-utils. On macOS it is brew install poppler. On Windows there is no package manager command in the README; you download the Poppler for Windows release, extract it, and add its bin directory to your system PATH. That last step is the most common source of a first-run failure on Windows, and the error you get from a missing Poppler binary does not usually mention Poppler by name. The Python package itself installs with pip install smart-llm-loader or poetry add smart-llm-loader. There is one release in the repository, v0.1.1, dated 2025-02-14 and labelled "Initial Release". That matters for expectations: this is a young package with a single published version, so the API surface described in the README is the API surface you get, and there is no deprecation history to read.
Constructor parameters and the chunking strategies
The README reproduces the full __init__ signature, which is short enough to quote in full. file_path takes a string or Path. url takes a string, so you can point the loader at a remote document instead of a local file. chunk_strategy defaults to 'contextual', with 'page' and 'custom' as the other documented values. custom_prompt is optional and is the hook for the custom strategy. model defaults to "gemini/gemini-2.0-flash", which is a different default from the gemini-1.5-flash used in the quick-start example, so read the signature rather than the example when you set up a project. save_output is a boolean, and output_dir takes a string or Path; together they let you persist the converted output instead of only holding it in memory. api_key is optional and exists for cases where you would rather not put credentials in the environment. Everything else lands in **kwargs and is forwarded to litellm. The three strategies are meaningfully different. page keeps the page as the unit, which is predictable and cheap. contextual asks the model to find semantic boundaries, which is what produces the invoice_header and items_table labels. custom hands the segmentation decision to your own prompt, which is the escape hatch when neither of the built-in strategies matches your document type. Read the source if you need to know exactly what instruction the model receives for contextual or page.
Where the approach breaks down
The design puts a model call in the critical path of ingestion, and that has consequences the README does not discuss. Cost and latency scale with document count, not with token count alone, because each document is a model interaction. For a corpus of ten thousand text-only PDFs, you are paying a multimodal model to do work that a character splitter would do for free, and the output will differ between runs whenever the model's sampling or the provider's serving stack changes. That non-determinism is the real limitation. A page-based splitter produces the same chunks today and next year. A model-driven splitter does not, which makes regression testing of a retrieval pipeline harder: when answer quality moves, you cannot tell whether the retriever changed or the chunker did. There is a second, blunter failure mode. Long documents have to fit the model's context window, and the README says nothing about how oversized inputs are handled, whether pages are batched, or what happens when a single page exceeds the limit. If you are processing 200-page reports, that is the first thing to test. Finally, the contextual strategy is only as good as the model's judgement about where one semantic unit ends. On a dense technical standard with no visual structure, the model has less to work with than it does on an invoice, and the semantic_theme labels become correspondingly less useful.
SmartLLMLoader against PyMuPDF and plain splitters
The README's own comparison is against PyMuPDF, described there as "a popular traditional document loader". The difference in approach is not quality, it is where the decision about boundaries is made. PyMuPDF extracts text and layout from the PDF's internal structure, then a separate splitter cuts it by characters or tokens. That is deterministic, runs offline, costs nothing per document, and is fast. It also has no idea that a line beginning "Item table:" should stay attached to the rows beneath it. SmartLLMLoader moves the boundary decision into the model, which is why the README's invoice example produces a chunk whose content begins "Item table:" and carries the full markdown table intact, with the theme items_table attached. For that class of document the trade is straightforward: you pay per document and accept run-to-run variation in exchange for chunks that respect the document's own structure. For a corpus of plain prose, the trade does not pay off. A recursive character splitter with a sensible overlap is cheaper, reproducible and good enough, and it does not require Poppler, an API key or network access. The honest framing is that these are tools for different inputs, not competitors where one wins.
Maintenance, licence and what to check before adopting
The package is MIT licensed, which permits commercial use, modification and redistribution provided the copyright notice and permission notice are included. That is a permissive licence and does not impose copyleft obligations on your application. It says nothing about the terms of the model providers you call through litellm, and those are separate agreements you enter into directly. On maintenance, there is a single release, v0.1.1, tagged "Initial Release" and dated 2025-02-14, with the most recent push to the repository dated 2026-08-03. A recent push with no corresponding release suggests development activity that has not been cut into a version, so pin your dependency and read the diff before upgrading rather than tracking main. The upgrade cost is concentrated in two places: the litellm model strings, which follow provider naming and change when providers rename or retire models, and the chunk metadata schema, which downstream code will read. Both are worth asserting in a test. Verify first that Poppler is installed and reachable, that your chosen model string is multimodal (a text-only model will not do OCR), and what load_and_split() returns for your largest document. If those three checks pass on your own files, the package does what its README says it does.
Editorial conclusion
Adopt smart-llm-loader if your input is scanned or visually complex documents where a page-based splitter loses the table and header structure, and if you accept per-document model calls. Do not adopt it for large text-only corpora, offline environments, or pipelines that need byte-identical output across runs. Before committing, verify three things on your own files: that Poppler is installed and on PATH, that the litellm model string you pass is actually multimodal, and what the loader returns for documents that exceed the model context window.
Frequently asked questions
What does smart-llm-loader require before it will work?
A PDF rendering utility, because PDF processing shells out to it. On Debian-family systems that is one package install with elevated privileges, on macOS one formula install, and on Windows you download a release archive from a third-party repository, extract it and add its binary directory to your system path by hand. The package itself then installs from the standard index or through a Python dependency manager.
Which chunking strategies does smart-llm-loader support?
Three, named in the constructor: page-based, contextual, and custom. The contextual one is the default, and the custom strategy takes a prompt you supply. The chunks that come out carry the page number, the source path and a semantic theme label alongside the text.
Does smart-llm-loader integrate with LlamaIndex?
The feature list says two retrieval frameworks, but the dependency list declares only the LangChain packages and no LlamaIndex package. The loader class is written as a subclass of the LangChain base loader, so that is the framework it integrates with. On a LlamaIndex stack you would be wrapping its output yourself.
Which models can smart-llm-loader use?
Any model the routing layer it depends on supports, including any multimodal one, since the package calls out through that layer rather than a vendor client of its own. The constructor takes a model string and the quick start shows four vendors, each with its own environment variable. The default in the signature points at a different revision than the one the quick start sets explicitly.
Is smart-llm-loader actively released?
There is one tagged release, version 0.1.1, published in February 2025 and named as the initial release, and the last commit to the repository is in August 2026. The package metadata still reads 0.1.1, so the published artefact is roughly eighteen months behind the repository and the status is classified as beta.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/drmingler-smart-llm-loader)Star history chart for your README
[](https://hysenlabs.com/projects/drmingler-smart-llm-loader)Was this useful?