DuckDB: An In-Process Analytical SQL Engine for Embedded Data Workloads
GitHub describes it as DuckDB is an analytical in-process SQL database management system. The repository metadata lists C++ as its primary language. The metadata lists the MIT license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- DuckDB is an in-process analytical SQL database that runs inside your application, not as a separate server. It targets fast analytical queries on large datasets with a rich SQL dialect and simple file-based data import.
- Who is it for?
- Adopt DuckDB if you need an embedded analytical database that runs in-process, supports complex SQL, and can query CSV and Parquet files directly. Avoid it if you require a client-server architecture with concurrent multi-user access; DuckDB is not designed for that.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
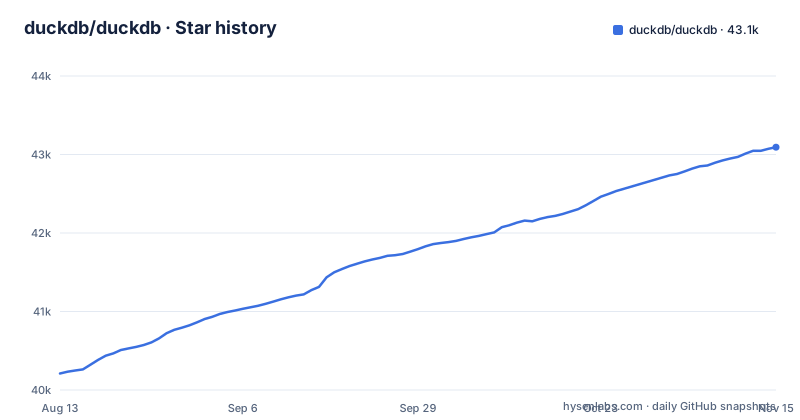
- duckdb/duckdb43,093 ★ · +2,883
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| duckdb/duckdb | 40.2k | 43.1k |
2,883 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What DuckDB Solves and Who It Is For
DuckDB solves the problem of running analytical SQL queries without the overhead of a separate database server. It is an in-process database, meaning the engine runs inside your application's process. This makes it a fit for data scientists, analysts, and developers who work with pandas, R, or Java and need to run complex queries on data that fits in memory or on local disk. The README emphasizes that it is designed to be fast, reliable, portable, and easy to use. It is not a replacement for a transactional OLTP database; its focus is purely analytical. If you are building a tool that needs to slice and aggregate large datasets, DuckDB removes the need to set up and maintain a standalone database instance.
In-Process Architecture and Data Flow
The core architectural choice is that DuckDB runs inside your application. The README says there is no separate server to manage and no external dependencies, although a DuckDB instance can optionally be turned into a server over HTTP via the quack protocol. The README describes it as an analytical in-process SQL database management system. Data flows through SQL queries that reference files directly. For example, you can run `SELECT * FROM 'myfile.csv';` or `SELECT * FROM 'myfile.parquet';` and DuckDB will read the file, parse it, and return results. This is a dramatic simplification over traditional ETL pipelines where you must first load data into a database. The engine is written in C++ and exposes clients for Python, R, Java, and Wasm, among others. The mechanism is straightforward: the database engine is linked into your application, and queries are executed locally. This design avoids network latency and serialization overhead, but it also means that the entire database is bound to the lifecycle of your process.
SQL Dialect and Extensions
DuckDB's SQL dialect goes beyond basic SQL. The README lists support for arbitrary and nested correlated subqueries, window functions, collations, and complex types such as arrays, structs, and maps. It also mentions several extensions designed to make SQL easier to use, which are documented under the 'Friendly SQL' section. This is a significant advantage for users who need advanced analytical queries without resorting to procedural code. The presence of nested correlated subqueries is particularly useful for complex business logic. However, this rich dialect also means that SQL written for DuckDB may not be directly portable to other databases. If you plan to move queries between systems, you may need to adjust syntax or functions. The documentation provides a full SQL reference, but the README itself only scratches the surface.
Getting Started: Installation and Simple Queries
Installation is handled through the official installation page, which is linked from the README. For developers who want to build from source, the requirements are CMake, Python 3, and a C++17 compliant compiler. In the root directory, running `make` compiles the sources. For a debug build, use `make debug`. The README advises running `make unit` and `make allunit` to verify the build after making changes. To run performance benchmarks, you can build with `BUILD_BENCHMARK=1 BUILD_TPCH=1 make` and then execute `./build/release/benchmark/benchmark_runner` from the root directory. For end users, the simplest path is to install a client package for your language, such as Python or R, and start querying. The README gives a clear example: `SELECT * FROM 'myfile.csv';` works directly on a CSV file. This is the fastest way to get value from DuckDB without any setup.
Limitations and When It Is the Wrong Tool
The most obvious limitation is that DuckDB is in-process. That means it is not designed for concurrent access from multiple users or applications. If you need a database that multiple services can connect to over a network, DuckDB is the wrong tool. It also implies that the database is only available while your application is running. If your app crashes, the in-memory data is lost unless you explicitly persist it to disk. The README does describe an optional quack protocol that turns a DuckDB instance into a server for other DuckDB clients over HTTP, but the primary use case remains in-process. Another limitation is that the documentation is extensive but the README alone does not cover how to manage large datasets that exceed memory. While DuckDB can handle data larger than memory by spilling to disk, the README does not provide specifics. You will need to consult the full documentation to understand memory management and performance tuning.
Alternative: SQLite and Other Embedded Databases
A direct alternative to DuckDB is SQLite, which is also an embedded SQL database that runs in-process. The key difference is that SQLite is designed for transactional workloads with row-level updates and small queries, while DuckDB is optimized for analytical queries with columnar execution and vectorized processing. SQLite is a serverless library that stores data in a single file, but it does not have the same analytical performance characteristics for aggregations and complex queries. DuckDB's ability to read Parquet files directly is a major advantage for data engineering workflows, something SQLite does not offer natively. If your workload is primarily transactional, SQLite is a better fit. If your workload is analytical and you want to query files directly, DuckDB is the more appropriate choice.
Maintenance and Licensing
DuckDB is licensed under the MIT license, which is permissive and allows commercial use, modification, and redistribution with minimal restrictions. The project is actively maintained, with recent releases including v2.0.0 (2026-10-21), v1.5.6 (2026-09-28, a bugfix release), and v1.5.5 (2026-07-22, a bugfix release). Because the newest release is a major version, read the release notes before upgrading. However, you should track the endoflife.date page linked in the README to understand support windows for each version. The maintenance cost is low if you use official clients, but if you build from source, you will need to keep up with C++ build requirements and the benchmark suite.
Conclusion: Who Should Adopt DuckDB
Adopt DuckDB if you are a data analyst or engineer who wants to run complex SQL queries directly on CSV or Parquet files without setting up a server. It is ideal for embedded analytics in applications, interactive data exploration, and ETL pipelines where data is processed in batches. Do not adopt it if you need a multi-user database with network access or if your primary workload is transactional with frequent updates. Before adopting, verify that your data sizes and query patterns fit within the in-process model and that the extensions you need are available for your language client. Check the release notes for the version you adopt, since v2.0.0 is the latest release. DuckDB's unique position as an in-process analytical database makes it a strong choice for many data tasks, but its architecture is a hard boundary you must respect.
Editorial conclusion
Adopt DuckDB if you need an embedded analytical database that runs in-process, supports complex SQL, and can query CSV and Parquet files directly. Avoid it if you require a client-server architecture with concurrent multi-user access; DuckDB is not designed for that. Before deploying, verify that your workload fits within the single-process model and that the extensions you need are available for your platform. Check the release notes for the version you adopt; the latest release is v2.0.0.
Frequently asked questions
What is DuckDB used for?
It is an in-process analytical SQL database management system, and the file calls it a high-performance analytical database system designed to be fast, reliable, portable and easy to use. The dialect covers arbitrary and nested correlated subqueries, window functions, collations, and complex types including arrays, structs and maps, and CSV or Parquet files are read by referencing them in the FROM clause.
Is DuckDB completely free?
The repository is MIT licensed and ships a LICENSE file. The README describes no commercial or enterprise edition and no paid tier, and it points at an endoflife.date page and a support options page under ducklabs.com for lifecycle and support questions.
how to install duckdb
The Installation section is a single sentence pointing at https://duckdb.org/docs/installation/. No command, package name or platform list appears in the file, and every command it does give is a contributor command such as `make`, `make debug`, `make unit` or `make allunit`.
how to use duckdb cli
A standalone CLI application is one of the available clients, linked at https://duckdb.org/docs/current/clients/cli/overview. The README gives no CLI invocation, no flags and no dot-commands, and its only runnable SQL is a file read such as `SELECT * FROM 'myfile.csv';`.
Is DuckDB faster than PostgreSQL?
The README makes no comparison with PostgreSQL or any other system, and reports no benchmark numbers. It describes DuckDB as fast, reliable, portable and easy to use, and points performance testing at `BUILD_BENCHMARK=1 BUILD_TPCH=1 make` followed by `./build/release/benchmark/benchmark_runner`, with details in the Benchmark Guide.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 2 in the last 30 days; newest first.
- DuckDB might soon support more than 38 digitsHacker News · Nov 15, 2026 · 2 points · 1 comments
- Duck: DuckDB for Swift. Powerful SQL inside iOS and macOS appsdev.to · Nov 14, 2026 · 2 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/duckdb-duckdb)Star history chart for your README
[](https://hysenlabs.com/projects/duckdb-duckdb)Was this useful?