AI-reads-books-page-by-page: a PDF knowledge extractor driven by OpenAI models
AI reads books: Page-by-Page PDF Knowledge Extractor & Summarizer. script performs an intelligent page-by-page analysis of PDF books, methodically extracting knowledge points and generating progressive summaries at specified intervals
At a glance
- What is it?
- The repository ships one Python script, read_books.py, that walks a PDF page by page, asks an OpenAI model for knowledge points, and writes interval and final summaries. It is a personal build, not a library, and it is configured by editing constants in the file.
- Who is it for?
- Adopt it if you already pay for OpenAI API access, your books are text-layer PDFs, and you are comfortable editing constants in read_books.py before each run. Do not adopt it if you need a CLI, a web interface, OCR over scanned pages, or per-run configuration without touching source.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 16 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
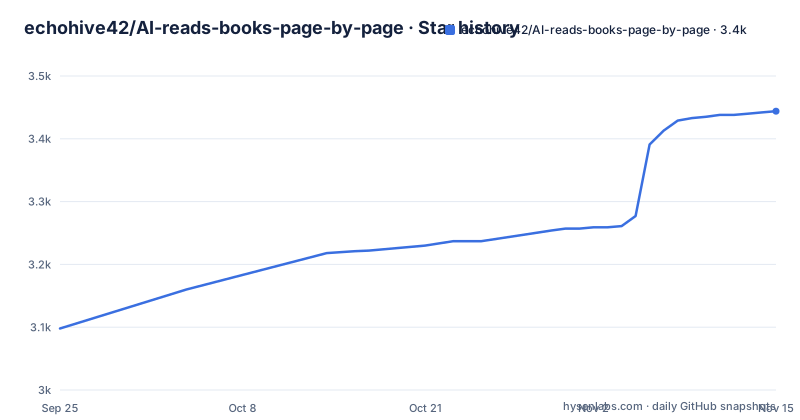
- echohive42/AI-reads-books-page-by-page3,444 ★ · +346
| Repository | 2026-09-25 | 2026-11-15 |
|---|---|---|
| echohive42/AI-reads-books-page-by-page | 3.1k | 3.4k |
346 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What read_books.py does that a chat window does not
Pasting a book into a chat box fails for the obvious reason: context limits and cost. This project takes the opposite route. It splits the work into one API call per page, so the model only ever sees a page of text plus whatever knowledge points have accumulated so far. Nothing about the whole book has to fit in a single request.
The intended user is someone with a PDF they want mined for ideas rather than skimmed: a technical book, a long essay collection, a textbook. The output is not a prose book report. The script stores a machine-readable knowledge base as JSON and generates Markdown summaries at intervals you choose. The README describes the knowledge base as persistent, which is what makes the resume path possible: if a run dies halfway, the JSON on disk still holds the earlier pages.
The scope is deliberately narrow. There is one script, one PDF name constant, one output tree. There is no package on PyPI, no CLI entry point, and no server. If you want a tool you install and point at arbitrary files, this is not that tool yet.
The page loop, the Pydantic schema, and where the state lives
The architecture is visible in the function list. main() calls setup_directories(), then load_or_create_knowledge_base(), then loops over pages calling process_page() for each one, then calls analyze_knowledge_base() for interval and final summaries.
process_page() is the core. It receives the OpenAI client, the page text, the current knowledge list and the page number, sends the page for analysis, and returns an updated list. The response is parsed into PageContent, a Pydantic model with two fields: has_content, a boolean, and knowledge, a list of extracted points. That boolean is how the smart content filtering works. Pages that look like a table of contents or an index come back with has_content false and contribute nothing, which is the mechanism behind the README's claim of skipping TOC and index pages.
State lives in one JSON file under book_analysis/knowledge_bases/. Every page appends to it and saves. That is a simple design with a real consequence: the knowledge base grows monotonically, and each later page is analyzed against everything extracted before it. Context therefore drifts as the book progresses, and a bad extraction on page 40 stays in the list for page 400. There is no pruning, no deduplication pass, and no scoring of which points matter. The README does not document any mechanism for removing a wrong entry other than editing the JSON yourself.
Two models are configured separately, MODEL for page processing and ANALYSIS_MODEL for summaries, which makes sense: per-page extraction runs hundreds of times and summarization runs a handful, so you can spend on the second and economize on the first.
Installing it and running a first book
There is no package to install. The README gives a clone-and-pip sequence, and the repository root contains requirements.txt listing pydantic, openai, pymupdf and termcolor.
git clone [repository-url]
cd [repository-name]pip install -r requirements.txtThe README leaves the repository URL and directory name as placeholders, so substitute the actual clone URL and folder name. The pip line works as written.
Configuration happens in the source file, not in a config file or environment variable. The README instructs you to place your PDF in the project root and update the PDF_NAME constant in read_books.py with the filename. The repository already contains infinite_math.pdf and meditations.pdf at the top level, so those two names are the ones that work out of the box. The README also lists ANALYSIS_INTERVAL, which sets how many pages pass before an interval summary is generated and can be set to None to skip interval summaries, and TEST_PAGES, which limits how many pages are processed and can be set to None to process the entire book.
python read_books.pyAfter the run, the README says output lands in three places: book_analysis/knowledge_bases/ for the JSON, book_analysis/summaries/ for Markdown interval and final summaries, and book_analysis/pdfs/ for a copy of the PDF. The setup_directories() function clears previously generated files, so do not treat an existing analysis directory as durable storage between runs.
Where this breaks: scans, cost, and the missing CLI
The extraction depends on pymupdf pulling a text layer out of each page. A scanned book, or a PDF exported as page images, has no text layer, and the README does not describe any OCR step. If your source is a scan, the page text handed to the model is empty or garbage and the knowledge base will be too. Check a PDF in a reader before running it.
Cost scales linearly with page count and there is no batching. A 500 page book means 500 extraction calls plus the summarization calls. Nothing in the repository estimates token usage, and the README does not discuss rate limits or retry behavior. A mid-run failure is survivable because the knowledge base is saved per page, but the script itself does not document a resume flag; the resume capability is a consequence of load_or_create_knowledge_base() reading the existing JSON.
The configuration model is the sharpest limitation. PDF_NAME, MODEL, ANALYSIS_MODEL, ANALYSIS_INTERVAL and TEST_PAGES are all module-level constants. Changing books means editing a Python file. There is no argument parsing, no environment variable, and no profile per book. If you process many PDFs, you will end up wrapping the script yourself or maintaining branches.
Finally, the repository is inseparable from its author's Patreon funnel. The README spends more space on membership tiers and weekly meetings than on the script. That is not a defect in the code, but it tells you what kind of project this is: a demonstration of a technique, published alongside a paid content business, not a maintained library with a roadmap.
Alternatives and the real difference in approach
The closest thing to a drop-in alternative is a general-purpose document question-answering stack: chunk the PDF, embed the chunks into a vector store, and query them with an LLM at question time. The difference is direction of work. This project processes the whole book up front, once, and produces a linear knowledge base and summaries. A retrieval stack does no work until you ask, then answers specific questions against retrieved chunks.
That distinction decides your use case. If you want to interrogate a book, ask about chapter 7, compare two passages, retrieval is the better shape, because the answer is grounded in the exact text rather than in an accumulated list of points. If you want a condensed reading of a book you have not read, and you want it as a document you can keep, this script's approach is more direct: the output exists whether or not you have a question.
The trade-off is fidelity. Retrieval keeps the original text and can quote it. This project keeps extracted points, which are a model's paraphrase, and the original page text is not preserved in the knowledge base. Once a point is extracted, you cannot trace it back to the sentence it came from. That is a real loss if you intend to cite the book. The README does not describe any citation or page-reference field in the PageContent model, so the provenance is simply not there.
Maintenance, licence, and what a fork costs you
The last push to the repository was on 2026-06-27. The repository has no published GitHub releases, so there is no version to pin and no changelog to read. Dependencies are unpinned in requirements.txt: pydantic, openai, pymupdf and termcolor with no version constraints. That matters because the code imports the OpenAI client and uses Pydantic models, both of which have had breaking changes across major versions. A fresh pip install today may pull versions the script was not written against, and the failure mode would be an import or validation error, not a subtle one.
The licence is MIT, which permits commercial use, modification and redistribution provided the copyright notice and permission notice are kept. That is the plain reading of the licence text, not legal advice; if you plan to ship a derivative inside a product, have your own counsel read it. Note that the licence covers the code, not the PDFs bundled in the repository or the model output you generate, and it says nothing about the OpenAI terms that govern your API usage.
Upgrade cost is low in one sense and awkward in another. The codebase is a single script, so reading all of it is feasible in one sitting. But there is no test suite, no CI configuration in the top-level entries, and no release process, so an upgrade is really a re-clone and a re-read. If you depend on this, pin your own dependency versions and keep a fork.
Editorial conclusion
Adopt it if you already pay for OpenAI API access, your books are text-layer PDFs, and you are comfortable editing constants in read_books.py before each run. Do not adopt it if you need a CLI, a web interface, OCR over scanned pages, or per-run configuration without touching source. Before committing, verify two things: that your PDF yields text through pymupdf rather than being a scan, and that the model names in MODEL and ANALYSIS_MODEL are ones your account can call.
Frequently asked questions
Is there an AI that can read a book?
AI-reads-books-page-by-page does exactly that in a limited sense: read_books.py feeds a PDF to an OpenAI model one page at a time and collects extracted knowledge points rather than reading the book as a single input.
Can ChatGPT read a book and summarize it?
The project uses the OpenAI API rather than the ChatGPT interface, and it works around context limits by processing one page per call and generating summaries at intervals set by ANALYSIS_INTERVAL.
Can ChatGPT read a book to me?
No. The script extracts knowledge points and writes Markdown summaries; the README describes no text-to-speech or audio output of any kind.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/echohive42-ai-reads-books-page-by-page)Star history chart for your README
[](https://hysenlabs.com/projects/echohive42-ai-reads-books-page-by-page)Was this useful?