Seedance 2.0 Skill OS: an agent skill that writes shot-by-shot video prompts, with lock lines because the model forgets across cuts
Comprehensive production pipeline for quad-modal AI filmmaking with Seedance 2.0
At a glance
- What is it?
- Emily2040/seedance-2.0 is an MIT-licensed agent skill that turns an idea into a directed prompt for the Seedance 2.0 video model. It plans shots, binds references and continues from an accepted clip, while generation and its cost stay with your video provider.
- Who is it for?
- This skill suits people who already have access to Seedance 2.0 through a video provider and keep paying for takes that drift between shots or get refused by moderation. Its lock lines, shot tables and moderation pre-screen target exactly those costs.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 44 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
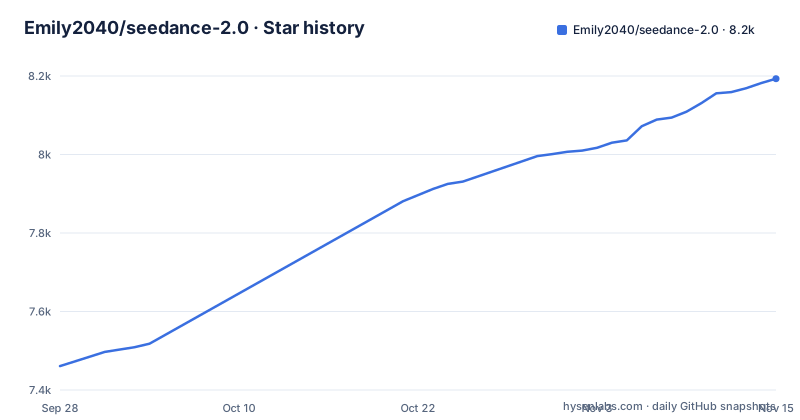
- Emily2040/seedance-2.08,193 ★ · +732
| Repository | 2026-09-28 | 2026-11-15 |
|---|---|---|
| Emily2040/seedance-2.0 | 7.5k | 8.2k |
732 Stars in the last 48 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
It writes the prompt; your provider renders and bills the video
Seedance 2.0 Skill OS is an agent skill, not a model and not a video service. It plans shots, binds references, and continues a sequence from a clip you have already accepted. The project states the boundary directly: your video provider handles generation and its costs.
For readers arriving from searches about running Seedance 2.0 for free or locally, this is the main thing to know. Nothing in this repository installs or hosts the Seedance 2.0 model. You still need an account with a provider that serves it, and each take you render is billed there. What the skill changes is how much you spend on takes that fail. The repository is MIT licensed and written mainly in Python, with a SKILL.md entry file alongside skills/, agents/, schemas/, references/, validation/, evals/ and tests/ folders. Five-minute quickstarts exist in English, Chinese, Japanese, Korean, Spanish and Russian.
Lock lines repeat light, people and position because nothing survives a cut
The central rule behind every prompt is that the model keeps nothing across a cut that the prompt does not repeat. So each shot ends with a lock line that restates the light, the people and where they stand.
The published boutique prompt shows what that costs in length. Every one of its five shots restates the lighting as soft grey daylight from the front window and warm spotlights on the shelves, and repeats the woman's description in full: thirties, dark hair tied back, white overalls stained with paint, tan work boots, plus where she is and which way she faces. The manager gets the same treatment once he appears. The consequence for a reader editing these prompts by hand is clear: deleting the repetition to tidy the text removes the thing that keeps a character in the same clothes from shot one to shot four.
One action per shot, and feelings written as a body
The skill directs for the model rather than for a human crew. The guidance in references/direct-for-the-model.md comes down to a few habits. Each shot gets one action while everyone else in frame keeps living. A reaction is written as a feeling plus one physical anchor. Prop work is written as a hand doing something.
The boutique prompt follows this closely. In shot three the manager is embarrassed, and the anchor is concrete: the polite smile fades and he swallows. In shot four the action is a single exchange: she points at one pair of shoes and he lifts it down with both hands. Sound is specified separately at the end, here rain on the glass door, boots on the carpet and his voice dropping, with no music and no subtitles. Prompts that pile several actions into one shot fall outside this method.
Shot tables let you check the geometry before paying for a take
Every published prompt was rendered from a shot table that is published beside it, documented in references/shot-table.md. The table starts with a floor plan. For the boutique, that means the glass front door at one end, the counter along the right wall, the wall of shoes opposite the door, the white chaise in the middle, where the manager and the assistants start, and where the daylight and the spotlights fall.
The purpose is to catch spatial mistakes on paper. If shot two has the camera on the counter side and shot four puts it behind the chaise, the table shows whether the woman can face the counter in both without contradicting herself. A take is paid for at the provider, so an error caught in the table is a render you do not buy. The limit is that the table only checks what you wrote down; a scene without a floor plan gets no such check.
The moderation pre-screen exists because classifiers refuse words
Every demo prompt went through a moderation pre-screen, described in references/moderation-prescreen.md, before it was published. The reasoning given is that a classifier refuses words, not intent. A prompt that describes a harmless scene can still be rejected because of the vocabulary it uses.
The brief people usually type for the first demo shows the problem: humiliated, disguised, plot twist. The prompt the skill wrote tells the same story through actions and objects, such as a soaked woman stopped at the door, a phone call, a trail of wet bootprints on a cream carpet. For the reader, the pre-screen is a step that runs before you submit, not a guarantee. Whether a prompt passes is decided by the provider's classifier at render time, so a prompt that clears the pre-screen can still be refused there.
The demo reel mixes rendered clips with slates that have no video yet
The showcase is seven scenes in five languages: English, Chinese, Korean, Japanese and Russian. Each is meant as a complete fifteen-second story cut in four or five shots, with the situation clear by shot two, a reversal, and a hold on whoever lost. Rendered clips were made on Seedance 2.0 from the exact prompt shown, as text to video, with no reference assets, one take and no post work.
Not every scene has a clip. Where one has not been rendered, a slate stands in its place, and the first demo, By appointment only, is marked slate: not rendered yet. Its metadata also carries a ladder value, Stretch: 4.5 beats with one insert at half, load 3, S = 2.0. The consequence is that you cannot judge every published prompt by its output. Check the evidence status section and the per-clip label before treating a prompt as proven.
Sequences continue from an accepted clip, with examples per workflow
Beyond single clips, the skill builds sequences that continue from a clip you accepted. The examples folder holds a standalone-clip case, a golden-prompts set and three sequence cases: sequence-airport-arrival, sequence-mixed-lane and sequence-observed-deviation. A top-level V6_SEQUENCE_PROMPT_COMPILER_MANIFEST.md sits next to SKILL.md, and Python dependencies are pinned in requirements-validation.lock and requirements-masthead.lock.
The version history moves quickly. v5.3.0 was released on 2026-05-08 and v6.7.0 on 2026-08-06, with the last push on 2026-10-03. A jump of a full major version in three months means prompts, schemas or workflows built against v5 may not carry over unchanged, so read the CHANGELOG.md before upgrading a pipeline that depends on it.
Editorial conclusion
This skill suits people who already have access to Seedance 2.0 through a video provider and keep paying for takes that drift between shots or get refused by moderation. Its lock lines, shot tables and moderation pre-screen target exactly those costs. It does nothing for someone looking for free or local access to the model, since it generates no video. Before relying on it, check which demo clips are actually rendered rather than shown as slates, and confirm your provider's pricing for the takes the prompts will trigger.
Frequently asked questions
What is Seedance 2.0 good for?
Seedance 2.0 Skill OS uses the Seedance 2.0 video model for short directed clips, such as fifteen-second stories cut in four or five shots, generated as text to video from a shot-by-shot prompt.
How much does Runway Seedance 2.0 cost?
Seedance 2.0 Skill OS is free under the MIT license, but it only writes prompts. Your video provider handles generation and charges for it.
how to use seedance 2.0
With Seedance 2.0 Skill OS you give an agent an idea, and the skill plans shots, writes a directed prompt with a lock line per shot, and passes it through a moderation pre-screen before you render it at your provider.
how to install seedance 2.0 locally
The Seedance 2.0 Skill OS repository installs an agent skill, not the Seedance 2.0 model. Video generation runs at your video provider.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/emily2040-seedance-2-0)Star history chart for your README
[](https://hysenlabs.com/projects/emily2040-seedance-2-0)Was this useful?