AI Novel Writing Assistant: an agent pipeline that tries to finish the whole book
AI-native, open-source engine for end-to-end novel creation -- from a single idea to a full novel -- using agents, worldbuilding, a writing engine, RAG and whole-book production workflows, with structured planning to help beginners.
At a glance
- What is it?
- ExplosiveCoderflome's AI Novel Writing Assistant is a TypeScript monorepo that turns one sentence of inspiration into a planned, executed and audited long-form novel. Its bet is completion over prose quality, and its documentation is written for people who have never structured a story before.
- Who is it for?
- Adopt it if you want a runnable reference implementation of a LangGraph-orchestrated long-chain writing workflow, or if you need a guided path through a first novel and accept that the first draft is a scaffold rather than a finished manuscript. Do not adopt it if you need a stable, clearly licensed dependency for a commercial product, or if you already have a working drafting process and only want better sentence-level suggestions.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
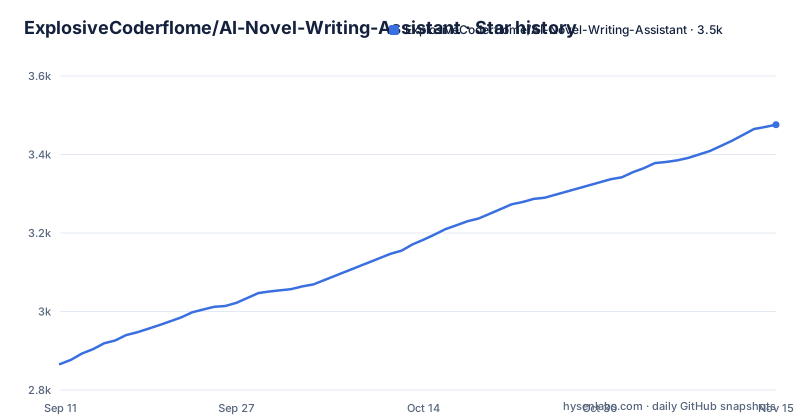
- ExplosiveCoderflome/AI-Novel-Writing-Assistant3,476 ★ · +610
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| ExplosiveCoderflome/AI-Novel-Writing-Assistant | 2.9k | 3.5k |
610 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem is not generation, it is book-length coherence
The README states the project's own framing plainly: most AI writing tools work the same way, you type a prompt, get a passage back, and retry if you dislike it. That is adequate for a short piece and falls apart over a novel, where the failure is not a bad paragraph but drift. Characters change names, a faction introduced in chapter three never returns, the middle sags because nothing was planned for it. The repository calls its product an AI director style long-form production system and says the target user is someone who does not know how to write at all, not an experienced author who already designs structure. That ordering matters. The stated priority is finishing the book first and refining the prose later, which explains why so much of the codebase is planning, checkpointing and state feedback rather than prompt tuning. It is aimed at two audiences at once: beginners who want to get to a complete draft, and developers who want to study how an agent workflow behaves when the task runs for days instead of seconds.
Auto-director: from one sentence to a writable book
The entry point is a single line of inspiration. According to the README, the auto-director takes that line, organizes the project settings, aligns a book-level framing, and then generates several complete directions for the book along with matching title sets. The user can regenerate, revise one specific proposal, or redo only the titles of one proposal, so dissatisfaction does not force a full restart. From there the chain moves through story macro planning, this-book world, character preparation, volume strategy and volume skeleton, pacing board, chapter list, chapter refinement, chapter execution, review and repair. Each stage supports checkpoint recovery, manual takeover and retrying with a different model. The README notes that in fully automatic mode the system stops rather than retrying forever when a model is unavailable, quota is exhausted, repairs fail repeatedly, or replanning is required, and that all state is written back to a director follow-up record so work resumes from the original checkpoint. It also states that after each batch of chapters the system confirms pending candidate characters, promotes them into the official roster and triggers a dynamic rebuild, which is the mechanism offered against character consistency drift later in the book.
Creative Hub, tool registry and the chapter execution chain
Creative Hub is described as a single creative center that carries dialogue, follow-up questions, planning, tool calls, task state and turn summaries, replacing what would otherwise be scattered feature buttons. Inside it the repository names a Planner, a Tool Registry, a Runtime, approval nodes, state cards and an interrupt-recovery path. Natural-language intent is routed either to an auto-director stage or to a chapter task. The chapter side is where the design gets specific. Chapter generation context filters the character resource ledger by the participants of that chapter rather than stuffing every character into the prompt. Confirmed ledger entries and pending proposals go through separate audit paths, so the prose does not treat an unconfirmed resource as established fact. The execution chain covers draft generation, AI review, repair of fixable issues, recording of quality debt, write-back of character state, facts and foreshadowing, and the entry point for the next chapter. Single-chapter runs, chapter execution and the whole-book batch pipeline are said to converge on the same chain, which is the kind of decision that prevents two divergent code paths from drifting apart. The release notes also mention a concrete fix: the LLM rate limiter evicts old limiters when provider configuration changes, which the notes attribute to stable memory over long runs.
Getting it running: pnpm workspace, SQLite, optional Qdrant
The repository is a pnpm workspace monorepo with React and Vite on the front end, Express and Prisma on the back end, Plate as the editor, LangChain for model calls, LangGraph for agent orchestration, SQLite through Prisma as the default store, and Qdrant for RAG. The README states that the default SQLite setup is enough to run the main chain, and Qdrant is connected only when retrieval is needed. Runtime parameters such as RAG concurrency and rate limits were moved out of .env into a settings panel, and the README says changes take effect without a restart. Model routing supports OpenAI, DeepSeek, SiliconFlow and xAI among others, and planning, prose, review and book-splitting can be routed to different models per task; the September 2026 notes describe model routing management becoming its own settings entry, with provider pages limited to connection and model catalog. Custom providers can choose Bearer, x-api-key or no authentication, and the notes mention that a model URL already containing /models will not have the path appended twice. If you only want to use the tool rather than build it, the README points at GitHub Releases for a Windows desktop build, recommending Setup.exe over the portable option, and at a GitHub Pages introduction site on port 4173. The documentation set is listed as 34 public documents covering installation, troubleshooting, a first-novel walkthrough, stage-by-stage recovery manuals and the end-to-end production chain. The README does not give a full command sequence for building from source, so treat the desktop release as the documented path and read the installation document before attempting a local build.
RAG, the writing-style engine and where they actually attach
Retrieval is not a separate chat feature here. The README says book-splitting results and knowledge-base documents are fed back through RAG into planning, continuation and prose generation, and that book-splitting output is written into a facets index so recall includes analysis conclusions rather than raw text alone. Chunk hashing deduplicates vectors on rebuild, and a retrieval trace on the backend shows why a given passage was recalled. Embedding and Qdrant writes run concurrently with adjustable parallelism. The writing-style engine is the more unusual piece. Instead of a paragraph of style instructions inside a prompt, style is stored as an asset that can be saved, edited, bound, test-written and reused. Features can be extracted from existing text along with source samples, collected into a visible feature pool, enabled or disabled item by item, and the rules are recompiled when the pool changes. The engine participates in generation, detection and correction, and there is a set of anti-AI rules aimed at reducing template feel, over-explanation and vague phrasing. The honest reading is that this is a rule system with a feedback loop, not a learned style model. Its quality depends entirely on how well the extracted features are chosen, and the documentation does not quantify how much the anti-AI rules change output. What it does give you is a place to put style decisions that survives across chapters, which a prompt does not.
What the design does not solve
The licence is the first problem. The repository metadata reports NOASSERTION, meaning no recognized licence could be determined from the repository. The README does not discuss licensing at all. If you intend to ship anything derived from this code, or to depend on it in a commercial pipeline, resolve that question directly with the repository owner before you build on it. This is not a legal opinion. The second limitation is scope. The README says the derivative workshops for comics and short drama are not opened until the main chain works, because they consume chapters, characters and scenes the novel has already produced. That is a sensible dependency order, but it means the visual and screenplay features are downstream features, not parallel ones. Third, the target user is explicitly the beginner. A writer with an existing method will find the auto-director's book-level framing and volume strategy constraining rather than helpful, and the professional mode still routes through the same stage structure. Fourth, RAG is optional in the sense that SQLite alone runs the main chain, but the recall behavior described for planning and prose depends on Qdrant and embeddings being present. Running without it is possible; running without it and expecting the documented recall behavior is not. Finally, the release cadence visible here is three releases in two days, with 0.4.17, 0.4.18 and 0.4.19 landing on 2 and 4 September 2026. That is a fast-moving codebase, and the stage-by-stage recovery manuals will lag behind it.
Ani Book Skill and the difference in approach
The README points to a companion project, Ani Book Skill, for people who want to keep writing inside Codex. The split is stated directly: use this repository when you want a visual workbench, model configuration, live run status and novel asset management; use Ani Book Skill when you want to continue writing in Codex through local files, stage artifacts and a Skill. The difference is architectural rather than cosmetic. Ani Book Skill organizes direction judgement, story engine, chapter progression, review and repair, and continuity management as a recoverable and traceable process driven by files in a local workspace. This project puts the same concerns behind a server, a database and a UI, with an agent runtime mediating between them. If your objection to AI writing tools is that they hide state inside a service you cannot inspect with a text editor, the Skill route addresses that objection and this one does not. If your objection is that a file-based flow gives you no visibility into what the agent is doing mid-run, this project addresses that and the Skill route does not. Neither is a superset of the other, and the README presents them as complementary entry points rather than competitors.
Maintenance cost and who this is actually for
The maintenance surface is large. A pnpm workspace with a React client, an Express and Prisma server, a desktop build, a documentation site and a GitHub Pages introduction site means several independent build targets, and the README confirms they are separately buildable. Model provider churn is a recurring cost: the September 2026 notes retire older DeepSeek candidates in favor of V4 Flash and V4 Pro, keep old models only when existing configuration or historical routing needs them, and add a thinking-depth setting with a default of high. Every provider you route to is another surface that can change under you. The mitigation the project offers is model routing as a separate settings page, so swapping a task to a different model does not require touching the stage definitions. The checkpoint and recovery design is the other mitigation: if a run stalls, the documented expectation is that you resume from the last checkpoint rather than restart the book. Whether that holds in practice is the thing to verify yourself, and the fastest way is to run one short book end to end and deliberately interrupt it mid-chain. The 30 to 59 chapter compact-book path described in the notes, which arranges opening, turn and finale across three volumes, is a reasonable first test case because it exercises volume planning without a long generation run.
Editorial conclusion
Adopt it if you want a runnable reference implementation of a LangGraph-orchestrated long-chain writing workflow, or if you need a guided path through a first novel and accept that the first draft is a scaffold rather than a finished manuscript. Do not adopt it if you need a stable, clearly licensed dependency for a commercial product, or if you already have a working drafting process and only want better sentence-level suggestions. Before committing, verify three things in the repository: the actual licence file, whether the Qdrant and embedding path is required for the workflow you plan to use, and whether the checkpoint recovery described in the docs matches the version you install.
Frequently asked questions
What is the AI Novel Writing Assistant project?
It is an open-source AI production system for long-form novels, aimed first at readers who do not know how to write. It covers planning from one line of inspiration, project settings, macro story planning, character preparation, volume strategy and skeleton, rhythm and chapter breakdown, chapter execution, review and repair, and whole-book batch production, with checkpoint recovery, takeover and model switching available at every stage of that chain.
How do I run the AI Novel Writing Assistant locally?
It is a pnpm workspace of five scoped packages with a shared, server, client, site and desktop package. The dev scripts first run a local dependency check and a log runner, the client waits for the server on port 3000 before starting, and the desktop shell waits for ports 3000 and 5173. SQLite is the default database with PostgreSQL as a commented option, and the documentation site is served on port 4173.
Which model providers does the AI Novel Writing Assistant support?
The example environment file preconfigures seven: OpenAI, DeepSeek, SiliconFlow, Anthropic, xAI, Kimi and GLM, each with a base URL and default model names. Every API key in the file is left empty, and one provider's embedding model is blank while the others have one, so embeddings are not uniformly configured across the set.
What does the .env.example file for this project do?
Its own comment says the backend reads a file in the server directory and the frontend reads files in the client directory, so the root copy is an aggregate reference rather than the default load entry point. It also sets a 20 megabyte JSON limit, a retention count of ten automatic snapshots per novel with manual snapshots exempt, and a five minute default timeout for image generation.
Is there a desktop version of the AI Novel Writing Assistant?
Yes, a Windows one. The readme directs users to the GitHub releases, recommends downloading the Setup.exe installer first, and offers a portable variant for anyone who would rather not install or wants to run it from a USB stick or a temporary directory. The newest release is 0.4.28.
Is it legal to write a novel with AI, and can you tell if a novel was written by AI?
This page addresses neither question. It is a project readme in Chinese and English that covers product scope, the intended user, the workflow, the model providers and the desktop download. The only adjacent feature is a set of anti-AI rules described as reducing templated feel, explanatory feel and vague expression in the project's own generated prose.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/explosivecoderflome-ai-novel-writing-assistant)Star history chart for your README
[](https://hysenlabs.com/projects/explosivecoderflome-ai-novel-writing-assistant)Was this useful?