Smart Second Brain: the split between what works offline and what waits on a provider
A free, open-source Obsidian plugin that makes your vault smarter: better search, an interactive knowledge graph, and an AI assistant that knows your notes.
At a glance
- What is it?
- An Obsidian plugin whose keyword search and link graph need no model at all, while its semantic layer, agents and WebGL charting sit behind configuration this README describes only loosely. The manifest, the release tags and the test vault say more about how it is built than the feature list does.
- Who is it for?
- Install Smart Second Brain first for the parts that need nothing: keyword search and a graph built from your links and tags work immediately, with no provider and no key, and the privacy claim covering that state is specific enough to check. Judge the rest on evidence this repository does not give you.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 33 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
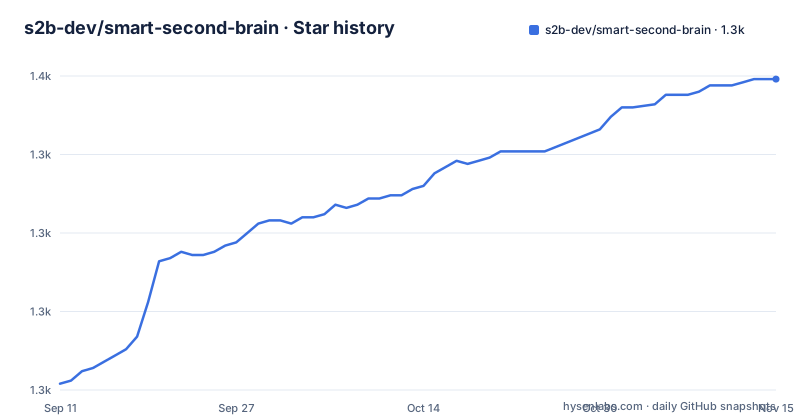
- s2b-dev/smart-second-brain1,349 ★ · +97
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| s2b-dev/smart-second-brain | 1.3k | 1.3k |
97 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Search works with no provider, meaning does not
The feature list advertises search that combines keyword matching with meaning, and a Smart Graph that works out what your vault is about from your links, your tags and what you wrote. The install section sets a lower floor for both. Search and the Smart Graph work immediately with no configuration and no AI provider, and only after you add an embedding model and pick it for search and for the graph do you get semantic search and topics that read what your notes say rather than how they link. A fresh install therefore gives you keyword matching plus a graph over the link and tag structure you already maintain by hand, which is the part that needs no account and no key. Agents wait behind that same embedding step, with an AI provider on top of it. Decide early whether keyword search over your existing structure is enough, because that is the tier you can evaluate before spending anything.
One outbound request, and only the update check gets a menu path
Privacy here is stated in specifics rather than adjectives. Out of the box none of your data leaves your machine, your notes only go to the providers you configure, there is no telemetry, and the single other network request is a daily update check that fetches this plugin's manifest.json from GitHub while sending nothing about you. That one request has a named off switch: Settings → General → Check for updates. The embedding model and the AI provider get no such clarity in this file. There is no menu path for them, no list of which providers are supported, and no statement of whether the embedding step runs on your own machine or at a remote endpoint. A privacy page under a models path is linked from the install section, so the question of where note text travels first is answered somewhere other than here. Check that page before wiring a provider to a vault.
private: true, no dependencies key, one bundle
The manifest is marked private and declares no dependencies at all. package.json points main at main.js, sets private to true, and has no dependencies key; Svelte 5, Vite 7, TypeScript 5.9, Codemirror state and view, Tailwind 3.4, Biome, Vitest 4 and PostCSS all sit under devDependencies. An Obsidian community plugin loads a single bundle from its plugin folder, so the runtime pieces have to be compiled into that one file, which is also why there is no npm artifact and the install path is Obsidian's community plugin list. Two entries point at packages nothing declares: @types/d3-force and @types/stopword are present while d3-force and stopword are absent, so those types either arrive through another package's tree or the manifest is incomplete. The events shim is declared with no types package because it ships its own. Two configs at the root would normally emit a stylesheet, yet no styles.css appears in the root listing while .gitignore does.
A WebGL plotting build next to a claim about mobile
The plugin states that it runs on desktop and mobile, and the agents feature draws charts and dashboards live from your notes as widgets. The charting package is plotly.js-gl3d-dist-min, the WebGL build, and @types/d3-force sits in the same manifest, so two graphics stacks travel in one bundle. Mobile Obsidian is a WebView, where WebGL contexts are capped, and a 3D-capable plotting build is the heaviest item in a dependency list otherwise made of text editors and type checkers. Nothing visible separates the platforms. build is a single vite build at production mode and dev is the same command with development flags and watch, so both targets come out of one compile with no code splitting visible in the scripts. Whether mobile receives a smaller bundle than desktop is not stated anywhere in the file. That is the first thing to try on a phone.
Three tags in thirteen days, two minutes from push to release
Tags landed in quick succession: 2.1.2 on 2026-09-15, 2.2.0 on 2026-09-18 and 2.3.0 on 2026-09-28. package.json already reads 2.3.0, so the manifest and the newest tag agree, which is not always true of projects moving this fast. The last push is dated 2026-09-28T09:54:27Z and the 2.3.0 release was published at 09:56:35Z the same morning, roughly two minutes later, so the tag follows the push rather than preceding it. Two minor bumps inside a fortnight is quick for a plugin that stores its own state inside your vault. The project began as a university project and is worked on in spare time, so nothing schedules that pace. CHANGELOG.md sits at the root and is where to look before an upgrade rewrites settings you configured by hand.
Bun and Nix pin the same toolchain, and dev needs a POSIX shell
The root carries .bun-version, bun.lock, flake.nix and flake.lock, so Bun fixes the runtime while Nix fixes the environment, and the scripts themselves name no runner. The visible script list is short enough to read in full:
"dev": "NODE_ENV=development vite build --mode development --watch",
"build": "vite build --mode production",
"check": "svelte-check --tsconfig ./tsconfig.json && svelte-check --tsconfig ./tsconfig.test.json",
"check:src": "svelte-check --tsconfig ./tsconfig.json",
"check:test": "svelte-check --tsconfig ./tsconfig.test.json",
"format": "biome format --write ./src ./test ./integration",
"lint": "biome lint --write ./src ./test ./integration",
"lint:unsafe": "biome lint --write --unsafe ./src ./test ./integration",
"test": "vitest run",
"test:watch": "vitest",
"test:coverage": "vitest run --coverage",
"test:integration": "vitest run --config vitest.integration.config.ts"
Two details stand out. dev sets NODE_ENV by prefixing the command, which is shell syntax rather than tool syntax, so that line behaves differently on a Windows command shell than on macOS or Linux. And format, lint and lint:unsafe all pass --write, so invoking the linter or the formatter edits files under ./src, ./test and ./integration as a side effect rather than just reporting.
The test vault receives a symlink, not a copy
Integration tests run against a real vault directory rather than a fixture object. test:integration points at its own config, vitest.integration.config.ts, and setup-vault creates integration/S2B Test Vault/.obsidian/plugins/smart-second-brain before linking the build output into that plugin folder. The setup line is visible only as far as the link itself, ending partway through its relative target at ln -sf ../../../../../build/sm, so what it points at is not spelled out in the scripts you can see. A link rather than a copy means the vault exercises whatever currently sits in the local build directory and not a published bundle, which is what you want while developing and the wrong arrangement for reproducing a release. The vault folder name carries spaces and is quoted accordingly, and the relative target climbs five levels out of the vault before turning toward build.
The project asks contributors to mark which commits an agent wrote
This project states out loud how much of it was written by machines. Much of the code is written with AI coding agents, with review, testing and standing behind every change, and commits and pull requests say when an agent was involved. The tree backs that up: AGENTS.md and CLAUDE.md at the root, a .claude directory, greptile.json for automated review and .codesearchrc.json for code search. CONTRIBUTING.md holds the development setup and the policy for AI-assisted contributions, and questions route to a Q&A discussion board while shared skills and workflows go to a Show and tell board. A plugin that publishes its own agent instructions and asks contributors to flag agent-written commits makes provenance easier to check than in most projects, and puts the reading duty on whoever reviews the pull request. It is a process claim, so the commits are where you verify it.
Editorial conclusion
Install Smart Second Brain first for the parts that need nothing: keyword search and a graph built from your links and tags work immediately, with no provider and no key, and the privacy claim covering that state is specific enough to check. Judge the rest on evidence this repository does not give you. Semantic search and the agents both wait on an embedding model and an AI provider, and no menu path, provider list or statement of where the embedding step runs appears here, so read the privacy page for the model before connecting anything to a vault you care about. Two minor versions in a fortnight, from maintainers working in spare time, means stored settings can move under you: read CHANGELOG.md and pin a version you liked. Test the bundled WebGL plotting build on a phone first, because one vite build serves desktop and mobile alike.
Frequently asked questions
Is Smart Second Brain free, and what does running it cost?
The plugin is free and MIT licensed, installed from Obsidian's community plugin list. Its semantic search and agents need an embedding model and an AI provider that you supply, and what those providers charge is outside anything this repository sets.
Does Smart Second Brain send my notes anywhere?
Out of the box none of your data leaves your machine, and your notes only go to the providers you configure. The one other network request is a daily update check that fetches the plugin's manifest.json from GitHub, and it can be switched off under Settings → General → Check for updates.
What does an AI second brain actually do inside Obsidian?
Search surfaces your notes, the graph groups them into topics from links, tags and note text, and agents read and write notes while drawing charts and dashboards from them as widgets. Search and the graph work with no AI provider; semantic behaviour waits until an embedding model is added and selected.
Can I install Smart Second Brain from npm, or do I have to build it?
Not from npm. package.json is marked private and declares no dependencies, so the install path is Obsidian's community plugins list, and the alternative is running the manifest's own build command, vite build --mode production, against a checked-out copy.
Does Smart Second Brain work on mobile as well as desktop?
The plugin states it runs on desktop and mobile. Its charting dependency is the WebGL build of Plotly, and the build scripts define no separate mobile target, so both platforms come out of one compile.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/s2b-dev-smart-second-brain)Star history chart for your README
[](https://hysenlabs.com/projects/s2b-dev-smart-second-brain)Was this useful?