facebookresearch/seamless_communication: What the SeamlessM4T Repository Actually Gives You
Foundational Models for State-of-the-Art Speech and Text Translation
At a glance
- What is it?
- The Seamless family covers speech-to-speech translation, expressive prosody transfer and streaming ASR under one repository. The install path is narrow, the licence is split, and the CLI is where the real work starts.
- Who is it for?
- Adopt it if you need speech-to-speech or streaming ASR across roughly 100 languages and you can run Linux x86-64 or Apple silicon with fairseq2 available. Do not adopt it if you need a supported commercial SLA, a Windows install path, or a single unambiguous licence across the whole repository.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 68 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
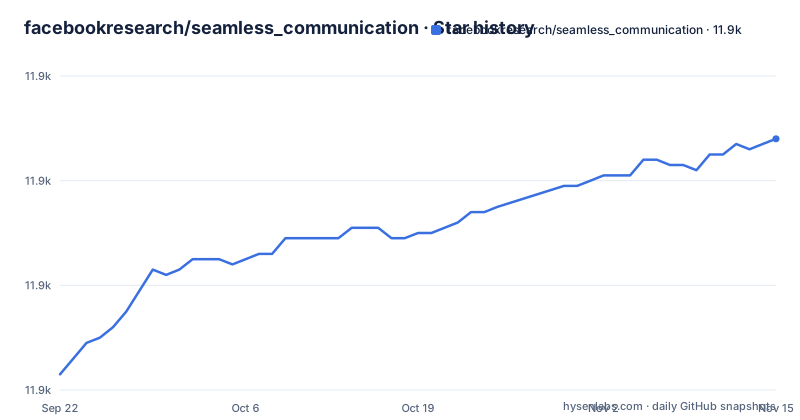
- facebookresearch/seamless_communication11,908 ★ · +45
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| facebookresearch/seamless_communication | 11.9k | 11.9k |
45 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What problem SeamlessM4T solves, and for whom
Most translation stacks force a choice. You pick a speech recogniser, then a text translator, then a synthesiser, and you lose prosody at every hop. The Seamless family collapses that pipeline. According to the README, SeamlessM4T is a single model covering speech-to-speech translation, speech-to-text translation, text-to-speech translation, text-to-text translation and automatic speech recognition across roughly 100 languages.
The audience is narrower than the language count suggests. This is a research repository from Meta's Fundamental AI Research group, published with a NeurIPS 2023 tutorial notebook and a set of papers. The people who get value from it are engineers evaluating multilingual speech translation, researchers reproducing or fine-tuning the models, and teams building a demo where latency and prosody matter. It is not a drop-in localisation service.
Two variants sit on top of the base model. SeamlessExpressive preserves speech rate, pauses and voice style during speech-to-speech translation. SeamlessStreaming handles simultaneous translation and streaming ASR, taking speech in and emitting speech or text. Seamless itself is the combination: expressive streaming speech-to-speech translation.
How the model family is layered
The architecture is best read as a stack rather than a monolith. W2v-BERT 2.0 is the speech encoder, open-sourced in December 2023 and described in section 3.2.1 of the Seamless paper. It feeds the translation models. SeamlessM4T v2 uses the UnitY2 architecture, which the README says improves both quality and inference latency in speech generation tasks compared with v1.
Above that sit the two specialised models. SeamlessExpressive and SeamlessStreaming are combined into Seamless, the unified model. The streaming side is where the interesting engineering sits: simultaneous translation means the model emits output before the speaker has finished, which is a different problem from translating a complete audio file.
The repository reflects that layering in its layout. Model-specific documentation lives under docs/m4t, docs/expressive and docs/streaming, each pointing at a separate Hugging Face model card. Entry points are split the same way, with m4t_predict, expressivity_predict and their evaluation counterparts registered as separate console scripts in setup.py. There is also a ggml directory, and the README points to a unity.cpp section for running S2TT and ASR natively without Python, which matters if you want to avoid a PyTorch dependency at inference time.
Installing seamless_communication and running a first translation
The documented install is a single pip command from the repository root. The README gives it without extras or flags.
pip install .That command hides the hard part. One prerequisite is fairseq2, and the README states its pre-built packages exist only for Linux x86-64 and Apple-silicon Macs. fairseq2 in turn depends on libsndfile, which the README notes may not be installed on your machine. If the install fails, the project points you at the fairseq2 README rather than offering a fallback. Transcribing inference audio for metric computation uses Whisper, which is installed automatically, and Whisper needs the ffmpeg command-line tool present on the system.
Once installed, the console scripts are the entry point. A speech-to-speech translation takes an input audio path, a task name, a target language and an output path:
m4t_predict <path_to_input_audio> --task s2st --tgt_lang <tgt_lang> --output_path <path_to_save_audio>Text-to-text works the same way but adds a source language, because the model cannot infer it from a string:
m4t_predict <input_text> --task t2tt --tgt_lang <tgt_lang> --src_lang <src_lang>The README directs you to the inference README under src/seamless_communication/cli/m4t/predict for the supported source and target languages per modality. Read that before assuming a language pair is available: the headline figure of around 100 languages does not mean every task supports every pair in both directions. The same setup.py also registers m4t_evaluate, m4t_finetune, m4t_prepare_dataset and m4t_audio_to_units, so fine-tuning and dataset preparation are first-class commands rather than notebook-only exercises.
Where the repository gets in your way
Platform support is the first wall. The fairseq2 dependency restricts pre-built packages to Linux x86-64 and Apple silicon. A Windows workstation or an older Intel Mac is not covered by the documented path, and the README offers no workaround beyond reading fairseq2's own instructions.
The licence is the second. The repository carries both a LICENSE and an MIT_LICENSE file plus a separate SEAMLESS_LICENSE, and setup.py declares the package licence as Creative Commons. GitHub reports the licence as NOASSERTION, and the setup.py header says the source is licensed under the MIT_LICENSE file. Anyone planning to redistribute or ship a product built on these models needs to read the individual files rather than assume the MIT file governs everything. This is a factual boundary in the repository, not a legal opinion.
The repository has no GitHub releases and no changelog among its top-level files, and it ships a tutorial notebook, so treat it as a research artefact rather than a versioned SDK.
SeamlessM4T against the Whisper plus NMT pipeline
The obvious alternative is the conventional cascade: run a speech recognition model, feed the transcript to a text translation model, then synthesise. OpenAI's Whisper is already in this repository's dependency list for metric transcription, and it is the recogniser most teams would reach for first.
The difference is what each approach optimises. A cascade gives you inspectable intermediate text at every stage, which makes debugging far easier: if the transcript is wrong, you know where the failure is. SeamlessM4T goes straight from speech to speech or speech to text in one model, which removes that inspection point. In exchange it can carry prosody through, which a cascade discards the moment it converts audio to a transcript.
Streaming is the sharper split. A Whisper-plus-translation pipeline is inherently batch: it needs a complete audio segment before it produces anything. SeamlessStreaming is built for simultaneous translation, emitting output while the speaker is still talking. If your use case is transcribing recorded files, the cascade is simpler and its failure modes are legible. If your use case is live interpretation where waiting for the full utterance is unacceptable, the cascade is the wrong shape entirely.
Maintenance, upgrade cost and licence checks
The repository is not archived, and the last push was on 2026-09-08, so the codebase is being touched. That is a statement about commit activity, not about support commitments. The repository has no published GitHub releases, which means there is no tagged version to pin against and no release notes describing breaking changes. Upgrading means tracking main and reading diffs.
The dependency set is pinned tightly, which cuts both ways. setup.py requires fairseq2==0.2.*, sonar-space==0.2.*, datasets==2.18.0 and simuleval~=1.1.3. Those constraints reduce the chance of silent breakage but also make it hard to move a single dependency forward without the others. Because fairseq2 ships pre-built packages for only two platform families, an upgrade of the underlying toolchain is a platform question before it is a code question.
On licensing, the repository's own structure is the signal: MIT_LICENSE, SEAMLESS_LICENSE and LICENSE sit side by side, and the package metadata says Creative Commons. Treat the model weights and the code as potentially different grants and check which file applies to what you redistribute. GitHub reports the licence as NOASSERTION, and the setup.py header points to MIT_LICENSE for the source.
Editorial conclusion
Adopt it if you need speech-to-speech or streaming ASR across roughly 100 languages and you can run Linux x86-64 or Apple silicon with fairseq2 available. Do not adopt it if you need a supported commercial SLA, a Windows install path, or a single unambiguous licence across the whole repository. Before committing, confirm which of SEAMLESS_LICENSE and MIT_LICENSE covers the models you plan to ship, and check that fairseq2 has a pre-built package for your target platform, since the README states those packages exist only for Linux x86-64 and Apple-silicon Macs.
Frequently asked questions
What does seamless_communication actually do?
It packages the Seamless family of models: SeamlessM4T for multilingual multimodal translation, SeamlessExpressive for prosody and voice style preservation, and SeamlessStreaming for simultaneous translation and streaming ASR. Together they cover speech-to-speech, speech-to-text, text-to-speech, text-to-text translation and automatic speech recognition across roughly 100 languages.
What are the requirements to install seamless_communication?
The documented install is pip install . from the repository root. The README states that fairseq2 is a prerequisite with pre-built packages only for Linux x86-64 and Apple-silicon Macs, that fairseq2 depends on libsndfile, and that Whisper requires the ffmpeg command-line tool.
How do I run a speech-to-speech translation with SeamlessM4T?
Use the m4t_predict console script with the s2st task, passing the input audio path, a target language and an output path. The README gives the form m4t_predict <path_to_input_audio> --task s2st --tgt_lang <tgt_lang> --output_path <path_to_save_audio>.
Does seamless_communication work on Windows?
The README does not document a Windows path. It states that the fairseq2 prerequisite has pre-built packages available only for Linux x86-64 and Apple-silicon Mac computers, and refers readers to the fairseq2 README for installation issues.
What licence applies to seamless_communication?
The repository contains both an MIT_LICENSE file and a SEAMLESS_LICENSE file alongside LICENSE, and setup.py declares the package licence as Creative Commons. The setup.py header says the source is licensed under the MIT_LICENSE file, while GitHub reports the licence as NOASSERTION, so check the individual files for anything you plan to redistribute.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/facebookresearch-seamless-communication)Star history chart for your README
[](https://hysenlabs.com/projects/facebookresearch-seamless-communication)Was this useful?