Running a 2.78-trillion-parameter model on a laptop: inside kimi-k3-in-c
A 2.78-trillion-parameter Kimi K3 running inference on a single CPU in 8.24 GB of RAM. Portable C99: no BLAS, no framework, no GPU.
At a glance
- What is it?
- FareedKhan-dev's kimi-k3-in-c is a portable C99 inference engine that streams a 2.78T-parameter MoE model from disk, using as little as 8.24 GB of RAM. It trades speed for memory and promises byte-identical output at any memory budget.
- Who is it for?
- Adopt kimi-k3-in-c if you need to run a specific 2.78T-parameter base model on hardware without a GPU and can accept roughly 5 to 30 seconds per token, or if you want to study how extreme quantization and disk streaming can be done in portable C. Skip it if you need multi-model support, or interactive speeds; the repository is a single-model proof of concept.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 43 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
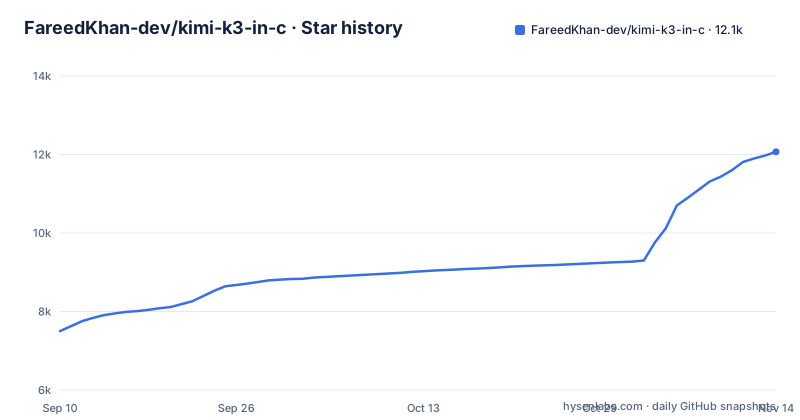
- FareedKhan-dev/kimi-k3-in-c11,972 ★ · +4,471
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| FareedKhan-dev/kimi-k3-in-c | 7.5k | 12k |
4,471 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A model that should not fit, on a machine that cannot hold it
Kimi K3 is a 2.78-trillion-parameter mixture-of-experts model. Its checkpoint on disk is 1.56 TB. The author of kimi-k3-in-c decided that the model should run on an ordinary laptop with 8 GB of RAM, and wrote a C99 inference engine to prove it. The README reports a peak resident set size of 8.24 GB during a run that generated 8 tokens at 32.69 seconds per token with the laptop preset. The same model, the same prompt, and byte-identical output at every memory budget between 8 GB and 224 GB. The project is for people who want to run a specific huge model on hardware they already own, not for people who want a general-purpose LLM runtime.
The four reductions that make it possible
The README describes four decisions about where bytes live. The first is that the model already ships in a compressed form: the 1.45 TB of routed experts are stored in packed 4-bit format, which the README calls half a byte per weight. Another is the streaming architecture itself: the dense trunk of the model stays resident in memory to a configurable depth, and the rest streams from disk on every token. The routed experts are never fully resident; they are multiplied directly from their packed form. These reductions together let a 1.56 TB checkpoint run in 8 GB of RAM, at the cost of reading from disk continuously when the model does not fit in memory.
How streaming and memory presets change the clock
The README gives a table of memory budgets and their effect on time per token. On an ordinary laptop with 8 GB of RAM, the whole model streams off the disk on every step, and each token takes 26.5 seconds. With 32 GB, some of the model sits in memory and the time drops to 24.2 seconds. At 64 GB it is 19.8 seconds. Only at 128 GB or more does the model fit entirely in memory, and then the disk wait disappears, giving 5.6 seconds per token. The README notes that a machine with 124 cores and a fast NVMe drive still reads from disk each step for the first three rows, so a slower drive makes those rows slower. The output is byte-identical regardless of memory size. More memory only buys speed, never a different answer.
Building and running: commands from the README
The README shows a quick start that clones, builds, and verifies in about a minute with no model. The full setup requires a checkpoint and a trunk file. The run command is: ./bin/k3 ~/k3model --trunk ~/k3trunk --preset laptop --tok ~/k3model --prompt "The capital of France is" --gen 8 --incremental. The --preset option selects a memory profile; the README mentions presets named laptop and server. The server preset, run on a machine with 128 GB or more, produced 28 tokens at 10.69 seconds per token and a peak RSS of 127.92 GB. The laptop preset produced 8 tokens at 32.69 seconds per token and 8.24 GB peak RSS. There are also prompt options, memory options, generation options, diagnostic options, exit codes, and environment variables documented in the README.
The config reader that refuses to guess
One of the documented invariants is a config reader that refuses to guess. That means the engine will not silently assume a wrong model dimension or a wrong number of experts. If the checkpoint does not match the expected format, the program should fail rather than produce garbage. This is a deliberate design choice, and it has a consequence: the engine is tied to the exact checkpoint layout of Kimi K3. It is not a general model loader. The tokenizer is also handled byte for byte, which matters for reproducing the exact same output across machines. The README emphasizes that the answer is byte-identical from the smallest machine to the largest, which implies a strict floating-point contract in the kernels as well. The section on kernels with a floating point contract suggests that arithmetic is done in a way that is deterministic regardless of memory layout or disk speed.
What the engine does not do
The batch example deliberately asks for a raw continuation: the prompt "The capital of France is" generates " Paris." and then a continuation, not a conversational reply. For answers and multi-turn history the README points to a separate XTML REPL chat mode, since the official Kimi K3 checkpoint is also chat-capable. The engine is also single-model: it is built for Kimi K3 specifically, not for arbitrary transformer checkpoints. The speed is a real limitation: 26 seconds per token on a laptop is not interactive. Generating a 100-token answer would take over 40 minutes on 8 GB of RAM. This is a tool for batch generation or for demonstrating that the model can run at all, not for real-time use.
Alternatives and what they do differently
The obvious alternative is llama.cpp, which also runs LLMs on CPU with quantization and no GPU. The difference in approach is that llama.cpp is a general-purpose inference engine that supports many model architectures and uses GGUF quantization, typically 4-bit or lower, but it does not attempt to run a 2.78T-parameter model in 8 GB of RAM. Another alternative is to run the model on a GPU or a cluster with more memory, which is the conventional route. kimi-k3-in-c is unique in its focus on one model and on making the disk the primary storage for weights, with a resident trunk that is configurable. That is a fundamentally different trade-off: it accepts extreme slowness in exchange for an extreme memory footprint.
Maintenance, license, and what to verify
The project is released under Apache-2.0, which permits commercial use, modification, and redistribution with attribution. The repository has a CHANGELOG.md and recent releases: v0.1.0 on 2026-08-02, v1.0.0 on 2026-08-07 and v1.1.0 on 2026-10-02. The last push was 2026-10-02, so it is actively maintained as of that date. The README mentions CI and a Makefile, and the Makefile names Linux/x86-64 as the reference platform, with macOS/arm64 and Windows (MSYS2 MinGW64) builds also supported. The engine is C99 and zero-dependency, which helps portability, and `make portable` builds without -march/-mcpu=native for distribution. There is no BLAS, no framework, and no GPU. The main maintenance cost is that this is a single-model project; if Kimi K3 updates its checkpoint format, the engine will need changes. Before adopting it, verify that you can obtain the model checkpoint legally and that your disk has enough free space for 1.56 TB, since the model streams from disk on every token when you have less than 128 GB of RAM.
Editorial conclusion
Adopt kimi-k3-in-c if you need to run a specific 2.78T-parameter base model on hardware without a GPU and can accept roughly 5 to 30 seconds per token, or if you want to study how extreme quantization and disk streaming can be done in portable C. Skip it if you need multi-model support, or interactive speeds; the repository is a single-model proof of concept. Before relying on it, verify that your disk can stream 1.56 TB repeatedly if you have less than 128 GB of RAM, and that you have the exact checkpoint format the code expects, since the config reader refuses to guess.
Frequently asked questions
what is kimi k3 in c
A from-scratch inference engine for the Kimi K3 model written in portable C99, with no BLAS, no framework and no GPU. It keeps part of the dense trunk in memory and multiplies the routed experts directly from their packed 4-bit form, which is why it runs a 2.78-trillion-parameter model on one CPU in 8.24 GB of resident memory.
Can I run Kimi K3 locally?
Yes, on CPU only. The readme reports a checkpoint of 1.56 TB on disk, 8.24 GB peak memory measured on an ordinary laptop, and 26.5 seconds per token there, dropping to 5.6 seconds per token on a machine with 128 GB or more where the model fits entirely in memory. The build is tested with no checkpoint at all, so the fast verification is a build check rather than an inference run.
What GPU is required to run Kimi K3?
None. The project lists zero GPUs as one of its headline figures and describes itself as inference on a single CPU with no BLAS and no framework. Everything is compiled from C99 with a portable build target for distribution, and the measured results in the readme come from a CPU machine with 124 cores.
What are the uses of Kimi K3?
The repository does not enumerate applications. What it demonstrates is running the model locally on consumer hardware, for both raw text generation and a multi-turn chat mode: the readme describes both a batch command that asks for a raw continuation and a REPL for answers and history.
What is Kimi K3 in Ollama?
kimi-k3-in-c is its own runner rather than an Ollama model. It ships its own engine as a C program built with make, plus three example scripts, and it publishes its own measurement output rather than relying on a hosted runtime, so it is a self-contained implementation rather than a packaging of someone else's.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Kimi-k3-in-C: A 2.78T-parameter model. No GPU. 8 GB of RAMHacker News · Nov 3, 2026 · 2 points · 1 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/fareedkhan-dev-kimi-k3-in-c)Star history chart for your README
[](https://hysenlabs.com/projects/fareedkhan-dev-kimi-k3-in-c)Was this useful?