FlashInfer: A Kernel Library That Puts Attention, GEMM, and MoE Behind One API
FlashInfer: Kernel Library for LLM Serving. It provides unified APIs for attention, GEMM, and MoE operations with multiple backend implementations including FlashAttention-2/3, cuDNN, CUTLASS, and TensorRT-LLM.
At a glance
- What is it?
- FlashInfer is a Python library and kernel generator for LLM inference on NVIDIA GPUs, unifying attention, GEMM, and MoE operations across multiple backends. This review covers its architecture, installation paths, and the trade-offs you should check before adopting it.
- Who is it for?
- Adopt FlashInfer if you serve LLMs on NVIDIA GPUs from Turing to Blackwell and need a single API for prefill, decode, and MoE without writing custom CUDA. Do not adopt it if you target non-NVIDIA hardware, need every feature on every GPU, or prefer a stable package that never compiles at runtime.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
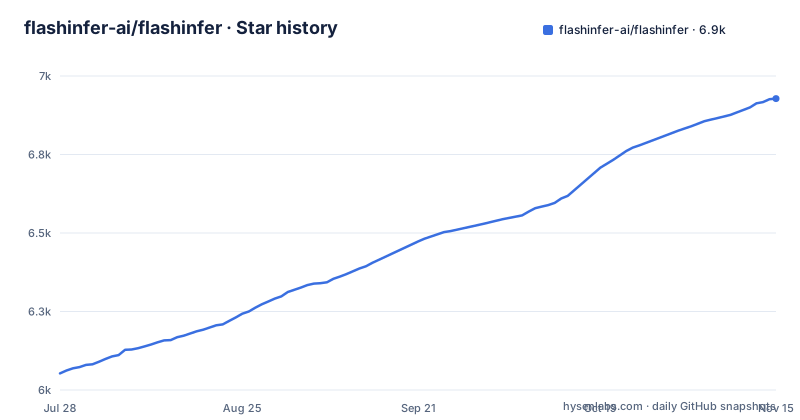
- flashinfer-ai/flashinfer6,928 ★ · +875
| Repository | 2026-07-28 | 2026-11-15 |
|---|---|---|
| flashinfer-ai/flashinfer | 6.1k | 6.9k |
875 Stars in the last 110 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One Kernel Library for the Full Inference Stack
FlashInfer solves a specific problem: LLM serving frameworks historically stitch together separate kernels for attention, matrix multiplication, and mixture-of-experts routing, each with its own tuning and memory layout. The README presents FlashInfer as a library and kernel generator that provides unified APIs for these three operator families, with multiple backend implementations underneath. The target user is an engineer building or maintaining a serving stack who wants to avoid reimplementing attention variants like paged KV-cache or MLA. The project covers prefill, decode, and mixed batching scenarios, which are the three phases that dominate inference latency. It also includes sampling kernels, RoPE, normalization, and activations, so the scope is broader than attention alone.
Backend Selection and the Kernel Compilation Pipeline
The core mechanism is a dispatch layer that selects among FlashAttention-2/3, cuDNN, CUTLASS, and TensorRT-LLM implementations based on hardware and workload. The README says it automatically selects the best backend for your hardware and workload. The package is split into three components: flashinfer-python, which compiles or downloads kernels on first use; flashinfer-cubin, which ships pre-compiled binaries for all supported architectures; and flashinfer-jit-cache, which provides a pre-built kernel cache for specific CUDA versions. This split is the heart of the design. The first-use compilation is a deliberate trade-off: it keeps the base package small, but it shifts cost to runtime. The two optional packages exist to move that cost back to install time, which matters for production environments without network access or with strict startup latency budgets.
Installation Paths and the JIT Cache Trade-off
The quickstart is a single pip command: pip install flashinfer-python. After that, a minimal decode attention call is a few lines of PyTorch code, creating query, key, and value tensors and passing them to flashinfer.single_decode_with_kv_cache. For faster initialization, the README recommends running flashinfer install-cubin-wheel and flashinfer install-jit-cache-wheel after the base install. These commands pull pre-compiled binaries, which is the documented route for offline use. Building flashinfer-jit-cache from source requires setting FLASHINFER_JIT_CACHE_PROVIDER_ARCH for a provider wheel and FLASHINFER_JIT_CACHE_PROVIDER_ARCHS for the shim, with an SM90a (9.0a) example. Those environment variables are a concrete knob you must set correctly, otherwise the cache may not cover your GPU. For Blackwell (SM100+) CuTe DSL kernels, the README says to use the cu13 extra: pip install flashinfer-python[cu13]. This extra is tied to CUDA 13, so check your driver version before using it.
GPU Coverage Is Wide but Feature Support Is Uneven
The README lists support from Turing (SM 7.5) through Blackwell (SM 12.1), including Jetson Thor and DGX Spark. That is a broad range, but the README includes a warning: not all features are supported across all compute capabilities. This is a genuine limitation. For example, BF16 GEMM is listed for SM10.0+ only, and FP4 GEMM is specifically for Blackwell. If you run an A100 (SM 8.0), the BF16 GEMM (SM10.0+) and FP4 GEMM (Blackwell) paths are not available. The practical consequence is that you cannot assume a uniform feature set across your fleet. You need to check the documentation for each operator against the compute capability of each GPU model you deploy. The project also lists multiple Blackwell compute capabilities, including SM 11.0 for Jetson Thor and SM 12.0/12.1 for RTX 50 series, which suggests the codebase has architecture-specific branches that may not all be equally mature.
The Feature List: What Is Actually Covered
The attention kernels cover paged and ragged KV-cache, decode, prefill, append, MLA for DeepSeek models, cascade attention for shared prefixes, block-sparse attention, and POD-attention, which fuses prefill and decode for mixed batching. The GEMM section includes BF16, FP8 with per-tensor and groupwise scaling, FP4 with NVFP4 and MXFP4 variants, and grouped GEMM for LoRA and multi-expert routing. MoE kernels support DeepSeek-V3, Llama-4, and standard top-k routing, with FP8 and FP4 expert weights. Sampling kernels are sorting-free for Top-K, Top-P, and Min-P, which the README links to a dedicated blog post. There is also speculative decoding with chain speculative sampling, plus custom AllReduce, MNNVL support for multi-node inference and NVSHMEM integration for distributed memory operations. This is a wide surface. You should treat the list as a menu of capabilities, not a promise of production readiness for every item.
A Real Alternative: CUTLASS or cuDNN Directly
The most direct alternative is to use the underlying libraries directly, CUTLASS for GEMM and cuDNN for attention, instead of going through FlashInfer. The difference in approach is control and maintenance. With CUTLASS, you write your own kernel selection logic, manage your own compilation pipeline, and handle each attention variant as a separate implementation. FlashInfer wraps those same libraries behind a unified API, which saves you that integration work but adds a dependency layer. If you only need one attention variant on one GPU architecture, writing directly against cuDNN may be simpler and give you fewer moving parts. If your workload spans multiple architectures and requires MLA or cascade attention, FlashInfer's unified API is likely less effort than assembling those kernels yourself. The trade-off is that FlashInfer's backend selection is a black box, while direct use of CUTLASS or cuDNN gives you explicit control over which kernel runs.
Licence, Maintenance, and Upgrade Cost
The project is licensed under Apache-2.0, which is permissive for commercial use, though you should review the full license text for any notices. The repository shows active maintenance, with release v0.7.3rc1 dated 2026-10-30, after v0.7.2.post1 on 2026-10-23 and v0.7.2rc6 on 2026-10-22. Nightly builds are documented in the README, which is useful for testing new features but also signals that the project moves fast. The upgrade cost is tied to the JIT cache: when you upgrade flashinfer-python, you likely need to rebuild or reinstall flashinfer-jit-cache to match the new kernel set. There is also a build requirement of setuptools>=77, and the README warns about an editable install error if setuptools is too old. Plan for a few minutes of build time and a possible cache rebuild on each major version bump.
Editorial conclusion
Adopt FlashInfer if you serve LLMs on NVIDIA GPUs from Turing to Blackwell and need a single API for prefill, decode, and MoE without writing custom CUDA. Do not adopt it if you target non-NVIDIA hardware, need every feature on every GPU, or prefer a stable package that never compiles at runtime. First verify that your exact GPU compute capability is supported for the operations you need, check whether the flashinfer-cubin wheel covers your architecture, and test the torch.compile path with your serving framework before committing.
Frequently asked questions
What does FlashInfer do?
It is a library and kernel generator for inference that provides unified APIs for attention, GEMM and MoE operations, with backend implementations including FlashAttention-2/3, cuDNN, CUTLASS and TensorRT-LLM. Backend selection is automatic based on hardware and workload, and support runs from SM 7.5 Turing through Blackwell.
How do I install FlashInfer?
The quickstart is `pip install flashinfer-python`, which compiles or downloads kernels on first use. For faster initialization and offline use, also run `flashinfer install-cubin-wheel` and `flashinfer install-jit-cache-wheel`, then confirm the result with `flashinfer show-config`. Blackwell CuTe DSL kernels need the CUDA 13 extra: `pip install flashinfer-python[cu13]`.
flashinfer is not available
The core package compiles or downloads kernels the first time they are used, so a slow first call is the documented cold-start behaviour rather than a missing install. `flashinfer-cubin` with pre-compiled binaries for all supported architectures and `flashinfer-jit-cache` with architecture-specific pre-built providers exist to remove that step, and `flashinfer show-config` prints the resolved configuration.
flashinfer vs flash attention 3
FlashAttention-3 is one of the backends FlashInfer dispatches to, alongside FlashAttention-2, cuDNN, CUTLASS and TensorRT-LLM, behind a unified API rather than as a competitor you choose between. The repository carries a `benchmarks/` directory; for your own workload, measure it yourself.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/flashinfer-ai-flashinfer)Star history chart for your README
[](https://hysenlabs.com/projects/flashinfer-ai-flashinfer)Was this useful?