vLLM-Omni: Installing and Serving Omni-Modal Models Past Text
A framework for efficient model inference with omni-modality models.
At a glance
- What is it?
- vLLM-Omni extends the vLLM serving stack from text autoregressive generation to diffusion, TTS, world-model and robot-policy checkpoints, wired as a pipeline whose stages can sit on different hosts. You gain model coverage and per-stage resource control; you take on an installer that resolves dependencies from your accelerator and a release line tied to upstream vLLM.
- Who is it for?
- vLLM-Omni fits teams that already depend on vLLM and need one serving process for an omni-modal, TTS, diffusion or robot-policy checkpoint, and that can track the even-numbered upstream vLLM releases. It does not fit a text-only deployment, where vLLM does the same job with fewer moving parts.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
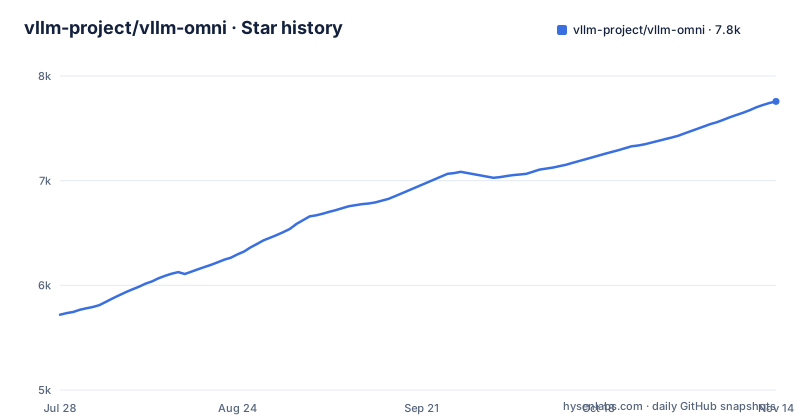
- vllm-project/vllm-omni7,757 ★ · +2,038
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| vllm-project/vllm-omni | 5.7k | 7.8k |
2,038 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Why vLLM-Omni exists: the output contract stops at text upstream
Upstream vLLM was designed for text-based autoregressive generation, and its paged KV cache, continuous batching and scheduler all assume a next-token loop. vLLM-Omni keeps that loop and widens the contract at both ends. On the input side, one deployment handles text, image, audio, video and action data. On the output side, a request can return text, multimodal payloads or action sequences. In between, it extends the autoregressive path to Diffusion Transformers and other parallel generation models, which emit many positions per step and do not fit a scheduler that thinks one token at a time.
Two kinds of team care about this. The first already runs vLLM for text and now holds a Qwen3-Omni checkpoint, a TTS model or a Diffusion Transformer that the text-only deployment refuses to load. The second serves a diffusion checkpoint that has outgrown a node graph and wants batching, streaming and an HTTP front end from the same process.
The project is also explicit about lineage. vLLM-Omni is an extension of vLLM rather than a replacement, and its autoregressive throughput rests on the KV cache management it inherits from that engine.
OmniConnector splits stages across hosts, not just across GPUs
Internally the framework models a request as a set of stages rather than a single decode loop. Each stage gets its own placement, stages overlap so one waits on I/O or a neighbour while another computes, and resources are allocated per stage instead of per server. That arrangement is what the project calls full disaggregation, and it is carried by a component named OmniConnector.
Disaggregation here means more than spreading one model over a GPU pair. Release 0.30.0 in 2026-09 added native cross-stage KV and multimodal payload transfer, including a Mooncake handoff from the autoregressive stage into a DiT stage plus NIXL connectors. Release 0.28.0 in 2026-08 introduced a unified paged KV cache runtime for the AR and DiT sides, so both halves share one cache implementation rather than two. Release 0.26.0 in 2026-08 added distributed layerwise offload for diffusion, which lets a large denoising model spill layer by layer instead of living on a single accelerator.
Inside a stage, parallelism covers tensor, pipeline, data and expert modes. Across requests, diffusion gained request-level batching, and output writes no longer wait for a finished asset.
Four model families, four different pipeline shapes
Coverage is organised by output family, and each family places the stages differently. Omni-modality models such as Qwen3-Omni, MiniCPM-o 4.5, Cosmos3, HunyuanImage and BAGEL take mixed input and return mixed output. TTS models such as Qwen3-TTS, Tencent AuK, Breeze-TTS-2 and CosyVoice3 return audio only. Diffusion models for image, video and audio generation include MiniMax H3, LingBot World, MAGI-2, LTX-2.5 and Wan2.2, where the 0.26.0 notes describe joint video and audio generation for H3 and the 0.30.0 notes describe realtime turbo inference on NVIDIA Blackwell and Ascend 950 hardware. Robot-policy and action models such as pi0.5, GR00T-N1.7, DreamZero-DROID and InternVLA-A1 emit actions.
Two capabilities cut across those families. World models get interactive serving, with LingBot World called out in the 0.30.0 notes. Streaming outputs let a client render audio or video before generation finishes, and the OpenAI-compatible API server puts that stream behind a familiar HTTP shape.
Downstream, VeRL-Omni v0.2.0 in 2026-08 uses the serving stack for diffusion RL with request-level and step-wise batching on FA3, and for Qwen3-Omni multimodal training with DPO and GSPO.
One install command, resolved against the accelerator you actually have
Installation is a single command, and the interesting part is what runs before your first import. The packaging metadata declares both the version and the dependency list as dynamic, so setup.py decides them. The stated reason is that dependencies are managed based on the detected hardware platform, with no extras like cuda to remember.
pip install vllm-omniThat command resolves the platform-specific set for you. The order is fixed inside detect_target_device(): an explicit VLLM_OMNI_TARGET_DEVICE environment variable wins first, then torch backend detection for cuda, rocm, npu, xpu or musa, then CPU as the fallback. Declared Python support runs from 3.11 up to but not including 3.14.
After the install, runnable examples are split into examples/offline_inference/ and examples/online_serving/, and examples/model_display_names.yml keeps display names in one place. The README points first-time users at the hosted documentation for the installation page, the quickstart and the supported model list, and at deployment recipes. A nightly CUDA image built from the latest main is published to Docker Hub when you would rather not resolve a CUDA build locally.
On a ROCm box the installer deletes onnxruntime before it installs anything
The installer writes to your environment before it writes anything of its own. On ROCm targets, setup.py calls uninstall_onnxruntime(), which runs pip uninstall -y against onnxruntime whenever that distribution is present, because onnxruntime may conflict with ROCm-specific dependencies. If something else in the same environment depends on onnxruntime, that dependency disappears as a side effect of installing this package, and the breakage surfaces later as an unrelated failure in the other tool. Check what is installed before running the command on a shared host or a CI image you do not own.
Dropping extras has a second cost. There is no way to ask for CUDA or ROCm as a suffix on the install command, so the environment variable is the only control, and it is read at install time rather than at run time. Requirements live in the requirements/ directory split per platform, which means auditing what you are about to install means reading that directory instead of one lock file.
The dev extra is pinned hard, which shows what the project expects to test with: pytest 9.1.1, pytest-xdist 3.8.0 and websockets 16.1.
Stable releases track the even-numbered upstream vLLM minors
Since 0.14.0 in 2026-06, the project publishes a stable release aligned with every even-numbered upstream vLLM minor version, and it says so in the release history. The cadence ran 0.16.0, 0.18.0, 0.20.0 and 0.22.0, then 0.24.0 in 2026-07, 0.26.0 and 0.28.0 in 2026-08, 0.30.0 in 2026-09, and 0.32.0 on 2026-10-28. Release candidates sit alongside those lines: 0.31.0rc1 on 2026-10-06 and 0.32.0rc1 on 2026-10-19 appear next to the final 0.32.0 in the release list.
Riding an upstream line has a cost worth planning for, because a rebase is not a patch. The 0.24.0 notes record a major refactoring of the Omni stage runtime, and 0.28.0 folded separate AR and DiT cache paths into one runtime. Code that reaches into stage internals will move. So pin one vLLM-Omni number and re-test when you move.
Two status facts frame the risk. The package classifier still reads Development Status :: 3 - Alpha. The repository is not archived and the last push was on 2026-10-31, so the work is current even where a feature is labelled experimental, as the full-duplex realtime runtime was in 0.26.0 before 0.28.0 extended it and 0.30.0 rebuilt it around engine-owned sessions.
Where vLLM-Omni costs you more than it covers
Start with the case against it. A text-only deployment gains nothing here. vLLM already does autoregressive text serving with the KV cache this project reuses, and routing the same traffic through vLLM-Omni adds a pipeline abstraction, an installer that rewrites your dependency set, and a release line coupled to upstream vLLM. Reach for it when a checkpoint produces audio, video, actions or mixed modalities.
The CPU fallback deserves a warning. If none of cuda, rocm, npu, xpu or musa is detected, the install resolves the CPU dependency set instead, and that set will not carry the diffusion or TTS families at a rate anyone would call serving.
Throughput for stage overlap, KV transfer and paged cache behaviour across the AR/DiT boundary is worth measuring on your own accelerators before capacity planning.
Editorial conclusion
vLLM-Omni fits teams that already depend on vLLM and need one serving process for an omni-modal, TTS, diffusion or robot-policy checkpoint, and that can track the even-numbered upstream vLLM releases. It does not fit a text-only deployment, where vLLM does the same job with fewer moving parts. Before adopting it, check that your checkpoint has a recipe under recipes/, that the resolved dependency set matches your accelerator, and that the vLLM-Omni version you pin lines up with the vLLM release your other components were built against.
Frequently asked questions
What are the differences between vLLM and vLLM-Omni?
vLLM was built for text-based autoregressive generation. vLLM-Omni keeps that path and adds text, image, audio, video and action inputs, Diffusion Transformers and other parallel generation models, and heterogeneous outputs from text to multimodal and action, organised as a pipeline whose stages can be disaggregated across devices.
What is vLLM-Omni?
A framework from the vLLM community for omni-modality model inference and serving, released in November 2025 under Apache-2.0. It ships an OpenAI-compatible API server, streaming outputs and full-duplex realtime serving with streaming audio input and output.
Which open-source models are supported by vLLM-Omni?
Four families are named: omni-modality models such as Qwen3-Omni, MiniCPM-o 4.5, Cosmos3, HunyuanImage and BAGEL; TTS models such as Qwen3-TTS, Tencent AuK, Breeze-TTS-2 and CosyVoice3; diffusion models for image, video and audio such as MiniMax H3, LingBot World, MAGI-2, LTX-2.5 and Wan2.2; and robot-policy models such as pi0.5, GR00T-N1.7, DreamZero-DROID and InternVLA-A1.
how to install vllm omni
Run pip install vllm-omni on Python 3.11 through 3.13. Dependencies are resolved at install time from the detected accelerator, with VLLM_OMNI_TARGET_DEVICE as an explicit override and CPU as the fallback. A nightly CUDA image built from the latest main is also published to Docker Hub.
What are omni-modal models?
Models that handle more than text. vLLM-Omni covers text, image, audio, video and action data processing, with heterogeneous outputs ranging from ordinary text generation to multimodal and action outputs, and it extends autoregressive serving to Diffusion Transformers and other parallel generation models.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vllm-project-vllm-omni)Star history chart for your README
[](https://hysenlabs.com/projects/vllm-project-vllm-omni)Was this useful?