PyTorch Lightning 2.6: Structuring PyTorch Training Without Giving Up Control
Pretrain, finetune ANY AI model of ANY size on 1 or 10,000+ GPUs with zero code changes.
At a glance
- What is it?
- PyTorch Lightning wraps PyTorch training loops to handle backpropagation, mixed precision, and multi-GPU scaling behind a LightningModule interface, while Lightning Fabric offers a lower-level alternative for those who want less abstraction.
- Who is it for?
- Adopt PyTorch Lightning if you want to remove repetitive training boilerplate from your PyTorch code and need a path from single-GPU experiments to multi-node training without rewriting your model. Skip it if you prefer minimal abstraction and are comfortable writing your own training loops, or if you need fine-grained control over every distributed call.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 16 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
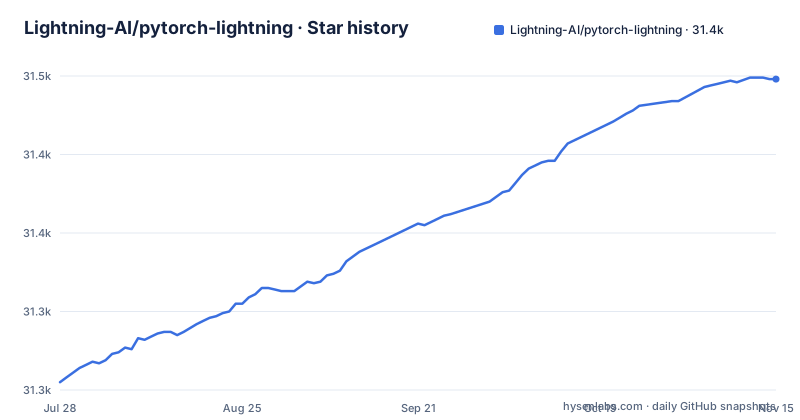
- Lightning-AI/pytorch-lightning31,448 ★ · +193
| Repository | 2026-07-28 | 2026-11-15 |
|---|---|---|
| Lightning-AI/pytorch-lightning | 31.3k | 31.4k |
193 Stars in the last 110 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Repetitive Engineering Problem Lightning Targets
Plain PyTorch training loops repeat the same infrastructure code across projects. Handling backpropagation, mixed precision, multi-GPU, and distributed training is error-prone and often reimplemented for every project, as the README puts it. PyTorch Lightning organizes PyTorch code to automate this infrastructure while keeping control over model logic. The target user is a researcher or engineer who wants to focus on model architecture and loss functions instead of writing distributed sampler code. The README's analogy, PyTorch is Javascript and Lightning is ReactJS, captures the intent: a higher-level structure for a lower-level library. This is not a new model library; it is a framework that sits on top of PyTorch and standardizes the training workflow.
LightningModule and Trainer: The Two Core Abstractions
The README shows a concrete example: you define a LightningModule, which is a subclass of nn.Module, and it defines a full system, such as an autoencoder or an LLM. In the toy example, LitAutoEncoder defines an encoder as a small nn.Sequential of linear layers. The README states that Lightning disentangles PyTorch code to decouple the science from the engineering. You write the science, Lightning handles the engineering, and scales from CPU to multi-node GPUs without changing your core code, according to the README.
Getting Started: Installation and First Run
The README gives a direct installation path: pip install lightning. That installs both PyTorch Lightning and Lightning Fabric, since the README says Lightning has 2 core packages. There is also a conda option: conda install lightning -c conda-forge. For a stable release from source, you can run pip install https://github.com/Lightning-AI/lightning/archive/refs/heads/release/stable.zip -U. For a nightly build, the README offers pip install https://github.com/Lightning-AI/lightning/archive/refs/heads/master.zip -U, with a warning that nightly has no guarantees. To run the toy example, you need torchvision as well: pip install torchvision, then python main.py.
Lightning Fabric: The Lower-Abstraction Sibling
The README introduces Lightning Fabric as the second core package, aimed at expert control. The description says Lightning gives you granular control over how much abstraction you want to add over PyTorch. Fabric is positioned as an alternative to the full LightningModule workflow. Fabric is aimed at PyTorch experts who want expert-level control. This is a genuine design split: you can choose the high-level Trainer or the low-level Fabric. But the existence of this option means Lightning is not a one-size-fits-all abstraction; it offers a spectrum. For teams that find LightningModule too restrictive, Fabric provides a middle ground.
Scaling Claims and What They Actually Mean
The tagline says pretrain and finetune ANY AI model of ANY size on 1 or 10,000+ GPUs with zero code changes. This is a bold claim. The zero code changes part refers to the core model code, not the entire project. You may need to configure the Trainer with a strategy for multi-node training. The README mentions Lightning Cloud as a way to run without managing infrastructure, with autoscaling and monitoring, but that is a separate service. The reality is that scaling to 10,000 GPUs is not a free lunch; you still need to design your data loading and model for distributed training. Lightning handles the distributed communication, but the model must be compatible. The README's claim should be read as a marketing statement, not a guarantee. For small teams, the practical benefit is that you can start on a single GPU and later add more by changing Trainer arguments, not by rewriting the model.
Where Lightning Falls Short
The main limitation is the added abstraction layer. If you need to debug a specific PyTorch operation inside the training loop, Lightning's Trainer can obscure the flow. The README offers Fabric for expert control. Another failure mode is when you have a custom distributed communication pattern, such as synchronous gradient averaging across heterogeneous devices, that does not fit Lightning's strategies. This is a general trade-off with any framework that standardizes training. Also, the README's example is a toy autoencoder; real models like LLMs may require custom callbacks or hooks that are not covered in the quick start. If your project has unusual training logic, such as reinforcement learning with environment interactions, Lightning's structure may fight you. In that case, plain PyTorch or a specialized library might be better.
Alternatives: Plain PyTorch and Hugging Face Accelerate
The most direct alternative is writing your own training loop in pure PyTorch. That gives you complete control, but you reimplement distributed training and mixed precision for each project. The README's analogy suggests Lightning exists because that repetition is painful. Another alternative is Hugging Face Accelerate, a known approach. Accelerate provides a lighter wrapper that keeps your training loop visible while handling device placement and mixed precision. The difference is that Accelerate does not require you to restructure your model into a LightningModule; you keep your loop and add accelerator calls. Lightning, on the other hand, imposes a structure with training_step and validation_step methods. If you want a middle ground, Fabric is closer to Accelerate than the Trainer is. The choice depends on whether you prefer a structured framework or a set of utilities.
Maintenance, Upgrades, and License
PyTorch Lightning is licensed under Apache-2.0, which is permissive for commercial use. The repository shows active maintenance with recent releases: 2.6.6 on 2026-09-10, 2.6.5 on 2026-05-27, and 2.6.4 on 2026-05-20. This indicates a regular release cadence, but that also means you need to track version changes. The README offers a stable release channel and a nightly channel, so you can choose stability or bleeding-edge features. Upgrade cost depends on how tightly you couple your code to Lightning APIs. For a long-lived project, you should pin the version and test upgrades in a separate branch. The license does not impose copyleft obligations, so you can integrate it into proprietary software without releasing your code.
Editorial conclusion
Adopt PyTorch Lightning if you want to remove repetitive training boilerplate from your PyTorch code and need a path from single-GPU experiments to multi-node training without rewriting your model. Skip it if you prefer minimal abstraction and are comfortable writing your own training loops, or if you need fine-grained control over every distributed call. Before adopting, verify that the abstraction level matches your team's expertise: LightningModule suits those who want structure, Fabric suits those who want near-plain PyTorch. Check the current version's release notes for any API changes and test your existing PyTorch code before committing.
Frequently asked questions
What is PyTorch Lightning used for?
It automates the repetitive engineering around a PyTorch model: backpropagation, mixed precision, multi-GPU and distributed training. Your model logic stays yours, and the same core code runs from CPU to multi-node GPUs.
How do I install PyTorch Lightning?
The quick start is pip install lightning. Variants cover optional dependencies with pip install lightning['extra'], conda with conda install lightning -c conda-forge, a release/stable zip, a master zip, and the testing index with pip install -iU https://test.pypi.org/simple/ pytorch-lightning.
What is a PyTorch Lightning module?
A LightningModule is an nn.Module subclass that defines a full system rather than a single layer. The README names an LLM, a diffusion model, an autoencoder and a simple image classifier as things that fit inside one.
What is PyTorch Lightning Fabric?
Fabric is the second of the project's two core packages, the expert-control end of the range. Where PyTorch Lightning automates the training loop, Fabric gives PyTorch experts more direct control over how much abstraction sits over PyTorch.
What is PyTorch Lightning vs PyTorch?
PyTorch is the tensor library you would otherwise hand-write backpropagation, mixed precision, multi-GPU and distributed training for on every project. PyTorch Lightning is organized PyTorch that automates those four, which the README compares to putting ReactJS or NextJS on top of Javascript.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/lightning-ai-pytorch-lightning)Star history chart for your README
[](https://hysenlabs.com/projects/lightning-ai-pytorch-lightning)Was this useful?