FlashLib: GPU classical ML operators on Triton and CuteDSL
Fast and memory-efficient classical machine learning operators
At a glance
- What is it?
- FlashLib packages kmeans, kNN, IVF-Flat, IVF-PQ, CAGRA, PCA, SVD, UMAP and t-SNE as flash_* functions and sklearn-style classes for NVIDIA GPUs. The interesting part is not the primitive list but the trade-off it documents: CAGRA for online serving, IVF-Flat above roughly 0.99 recall, IVF-PQ when memory is the binding constraint.
- Who is it for?
- Adopt FlashLib when your workload is already torch tensors on CUDA and you want kmeans, kNN or an ANN index without leaving Python. Do not adopt it if you need CPU execution, a non-NVIDIA accelerator, or a stable API: pyproject.toml declares version 0.3.0 and Development Status 3 - Alpha.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 32 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
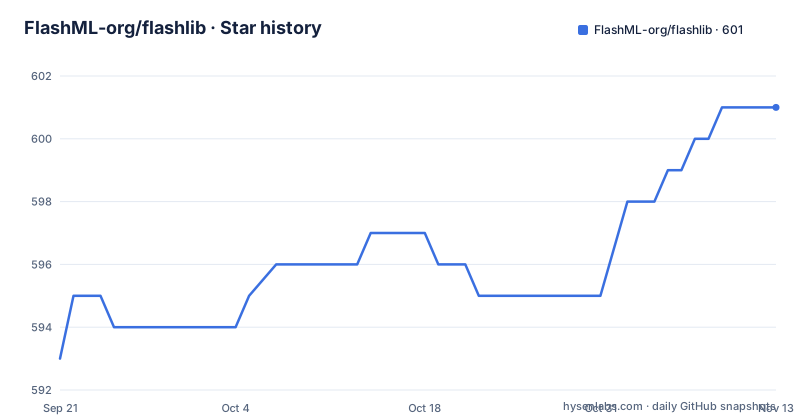
Star history
- FlashML-org/flashlib601 ★ · +8
| Repository | 2026-09-21 | 2026-11-13 |
|---|---|---|
| FlashML-org/flashlib | 593 | 601 |
8 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap FlashLib targets: classical operators left off the GPU
PyTorch moved dense linear algebra to the GPU years ago. Clustering, neighbour search, dimensionality reduction and classical regression largely did not follow, at least not in a form that keeps the same array type. In practice that means a pipeline written around torch tensors has to hand a NumPy copy to scikit-learn, run it on the CPU, and copy the result back. FlashLib's stated goal is to close that seam: the README describes it as "a GPU library for classical machine-learning operators" covering kmeans, knn, ivf-flat, pca, svd, dbscan, hdbscan, umap, t-sne, regression and GEMM, built on Triton and CuteDSL.
The audience is narrower than "data scientists". The package metadata lists torch>=2.0 and Triton as dependencies and the classifiers include Environment :: GPU :: NVIDIA CUDA, so the intended user already has an NVIDIA GPU and a torch-based stack. The README's own example allocates a million float32 rows and 128 columns directly on the device, which is a workload that would be painful to shuffle to the CPU and back. FlashLib is for people whose bottleneck is the operator, not the data loading.
Two APIs over the same kernels: flash_* functions and sklearn-style classes
The README states that every primitive is exposed twice: as a top-level flash_* function and as a sklearn-style class (KMeans, PCA, HDBSCAN and so on). The functional form returns plain tensors, as in the kmeans example where labels, centroids and n_iter come back from a single call. The class form exists for code that already follows the fit/transform convention.
The index-based primitives break the pattern deliberately. IVF-Flat, IVF-PQ and CAGRA are built once and queried many times, which matches how approximate nearest neighbour search is actually used: a large database tensor is fitted into an index, then many batches of queries are run against it. The README shows fit returning the index object and kneighbors taking the query tensor plus n_neighbors. Distances are documented as squared L2 for IVFFlat and CAGRA, and as ADC squared L2 for IVFPQ. That distinction matters, because squared L2 is monotonic with L2 so ranking is unaffected, but any code that compares distance values to a threshold needs to know which one it is holding.
A third surface, flashlib.info, is separate from the GPU path entirely. The README says it predicts runtime, FLOPs and HBM bytes for any primitive in about 5 microseconds on pure CPU, and that it does not import torch, triton or cutlass. That is a design choice worth noting: cost estimation is available in environments where execution is not, which is why the README mentions an LLM agent calling it without a GPU.
Installing FlashLib and running a first kmeans on CUDA
The README gives a single pip command for the released package. Because the dependency list includes Triton and CuteDSL backends, this is not a CPU-only install; the classifiers name Linux and Windows as supported platforms and the environment classifier names NVIDIA CUDA.
pip install flashlibBuilding from source follows the usual editable-install route. The repository root contains pyproject.toml, a flashlib/ package directory, benchmarks/ and tests/, so the layout is a standard setuptools project with the build backend set to setuptools.build_meta.
git clone https://github.com/FlashML-org/flashlib.git
cd flashlib
pip install -e .
The first real use is the README's kmeans example. It allocates a million rows of 128 float32 values on the device, then asks for 1024 clusters over at most 20 iterations. The call returns three values: labels, centroids and the number of iterations actually run.
import torch
from flashlib import flash_kmeans

x = torch.randn(1_000_000, 128, device="cuda", dtype=torch.float32)
labels, centroids, n_iter = flash_kmeans(x, n_clusters=1024, max_iters=20)
If that runs, the next step is the index workflow, because it is where the tuning knobs live. Fitting an IVFFlat index and querying it separates the expensive build from the cheap search.
import torch
from flashlib import IVFFlat

db = torch.randn(1_000_000, 128, device="cuda")
queries = torch.randn(10_000, 128, device="cuda")

index = IVFFlat(nlist=1024, nprobe=16).fit(db)
distances, indices = index.kneighbors(queries, n_neighbors=10)  # squared L2
The README is explicit that nprobe is the recall knob, and that at a fixed (nlist, nprobe) the probed candidate set, and therefore recall, matches a reference IVF-Flat implementation such as FAISS or cuVS. Treat that as the claim to verify on your own data rather than a property you can assume.
The three ANN indexes and the recall band where each one stops winning
FlashLib ships three approximate nearest neighbour indexes, and the README does something unusual: it states which one wins where. The measurements are attributed to an H100 with 1M rows, so they are the authors' numbers, not a general guarantee.
CAGRA builds a proximity graph through an exact kNN graph, detour pruning and reverse edges, then answers queries with a fused greedy traversal. The implementation detail the README highlights is that one Triton program handles one query, the priority buffer stays in registers, candidates are read in bf16 and the final top-k is re-ranked in exact fp32. The knobs are graph_degree and itopk_size, with itopk_size described as the recall knob. Per the README, at equal recall the fused traversal outruns cuVS CAGRA on H100 across the 0.9 to 0.99 recall band.
The stated crossover is the useful part. CAGRA wins online and small-batch serving at every recall, and batched search up to about 0.99 recall. IVFFlat wins batched search above about 0.99, because its GEMM fine-scan shares list reads across the batch on tensor cores; the README cites roughly 1.5x at recall 0.999 on SIFT-1M and says the gap widens with dimensionality. IVFPQ does not compete on recall at all. It trades a lower recall ceiling for 8 to 32x memory compression by storing each vector as m one-byte product-quantization codes, with a compression_ratio attribute the README prints as 32.0 for m=16 on 128-dim fp32 input.
That is a coherent story, and it is also a story with a short shelf life. The frontier is measured on one GPU model, one dataset scale and specific recall points. If your vectors are 768-dimensional embeddings rather than 128-dimensional ones, or your batch is one query at a time, the crossover may sit somewhere else entirely.
CuteDSL version bounds and the alpha-status caveats
The dependency block in pyproject.toml pins nvidia-cutlass-dsl>=4.4,<4.7, and the accompanying comment explains why the upper bound exists: the private MLIR helper imports used by the kNN Hopper kernel moved from cutlass.base_dsl._mlir_helpers to cutlass._mlir_helpers in version 4.6. This is a library reaching into private module paths of a dependency, and the pin is the mitigation. Anyone who forces a newer cutlass-dsl into the environment is outside what the maintainers validated.
The same block shows platform-specific Triton packages: triton>=3.6 on Linux and triton-windows>=3.6 on Windows. numba is listed as a dependency for hdbscan tree-condensation helpers on the CPU side, so hdbscan is not a pure-GPU path even though it is exposed as flash_hdbscan. Python 3.9 through 3.12 are the declared versions.
The status signals are unambiguous. The package version is 0.3.0 and the classifier is Development Status :: 3 - Alpha. The last push to the repository was on 2026-08-31, which is recent, but the repository has no published GitHub releases, so there is no published changelog to read for upgrade guidance. The README does not document a deprecation policy, a versioning scheme beyond the 0.x number, or a rollback procedure for a kernel regression.
Where FlashLib is the wrong choice
The clearest limitation is hardware. The library is built on Triton and CuteDSL kernels for NVIDIA GPUs, and the metadata says so. There is no documented CPU fallback for the flash_* primitives, and no mention of AMD or Apple silicon support. If your deployment target is a CPU-only container or a non-NVIDIA accelerator, FlashLib does not address it.
The second limitation is the alpha status combined with no published GitHub releases. A 0.3.0 package with Development Status 3 - Alpha and an undocumented upgrade path is a reasonable dependency for research code and a risky one for a service whose availability depends on kernel behaviour staying stable across upgrades.
The third is narrower and worth stating plainly: the README's performance claims are tied to specific hardware and datasets. The CAGRA comparison is scoped to H100, and the IVFFlat advantage above 0.99 recall is scoped to SIFT-1M and 1M rows. The README also notes that at a fixed (nlist, nprobe) the candidate set matches a reference IVF-Flat, which is a recall-equivalence claim rather than a speed claim. Reading the crossover table as a general ranking across GPUs and dimensionalities would overstate what was measured.
Finally, the informative API is a cost model, not a profiler. It predicts runtime, FLOPs and HBM bytes. Predictions are useful for budgeting a pipeline before launching it, and they are not a substitute for measuring the kernel you actually run.
FlashLib compared with FAISS and cuVS
FAISS and cuVS are the obvious alternatives for GPU nearest neighbour search, and the README names both. The difference is scope rather than quality. FAISS is an ANN library: it gives you IVF, PQ, HNSW and graph indexes, with its own index types and serialization, and it is not a torch-first API. cuVS is NVIDIA's vector search library and is the reference the README compares CAGRA against.
FlashLib's approach is to make ANN one family among many inside a single Python package that also contains kmeans, PCA, SVD, UMAP, t-SNE, regression and classification, all sharing the flash_* naming and the sklearn-style class convention. If your pipeline is kmeans followed by an ANN index followed by a logistic regression, and all three inputs are torch tensors on the device, that uniformity is the actual product. You are not converting between a FAISS index, a NumPy array and a torch tensor.
The cost of that uniformity is that FlashLib's ANN surface is smaller. Three index types are documented: IVF-Flat, IVF-PQ and CAGRA. FAISS exposes considerably more, and its index serialization and CPU fallback paths are mature in a way that a 0.3.0 alpha library's are not. If all you need is an ANN index and you already run FAISS in production, FlashLib's broader primitive set is not a reason to switch.
Licence and the cost of keeping up
FlashLib is Apache-2.0, declared in pyproject.toml as license = "Apache-2.0" with license-files = ["LICENSE"], and the README points to the same file. Apache-2.0 is a permissive licence with an explicit patent grant, which is generally the least complicated option for commercial use among the common open source licences. That is a description of the licence text, not legal advice; if the patent or notice clauses matter to your organisation, read LICENSE in the repository.
The upgrade cost is more concrete. Dependencies include torch>=2.0, Triton, nvidia-cutlass-dsl with a narrow upper bound, numba and numpy. The cutlass-dsl bound is the one to watch, because the comment in pyproject.toml ties it to private MLIR helper imports in the kNN Hopper kernel. Until those imports are replaced with a public interface, adopting a newer cutlass-dsl means running outside the validated combination, and a future FlashLib release that raises the bound is the event that makes upgrading possible again. The repository has no published GitHub releases, so tracking that means watching the repository rather than a release feed.
Editorial conclusion
Adopt FlashLib when your workload is already torch tensors on CUDA and you want kmeans, kNN or an ANN index without leaving Python. Do not adopt it if you need CPU execution, a non-NVIDIA accelerator, or a stable API: pyproject.toml declares version 0.3.0 and Development Status 3 - Alpha. Before committing, install it in a Linux environment with an NVIDIA GPU, run the README's flash_kmeans snippet on a tensor you already own, and check that the recall and QPS numbers you care about are reproducible with benchmarks/vs_cuml/cagra.py rather than taken from the README's H100 figures.
Frequently asked questions
What is FlashLib used for?
FlashLib provides GPU implementations of classical machine learning operators. The README lists kmeans, kNN, IVF-Flat, IVF-PQ, CAGRA, PCA, truncated SVD, DBSCAN, HDBSCAN, UMAP, t-SNE, linear and logistic regression, multinomial naive Bayes, random forest and a standard scaler, plus low-level linear algebra and multi-precision GEMM variants.
Does FlashLib work without an NVIDIA GPU?
The package metadata classifies the environment as NVIDIA CUDA and the library is described as built on Triton and CuteDSL kernels for NVIDIA GPUs. The one exception is the flashlib.info submodule, which the README says does not import torch, triton or cutlass and runs on pure CPU to estimate runtime, FLOPs and HBM bytes.
Which FlashLib ANN index should I pick?
The README states that CAGRA wins online and small-batch serving at every recall and batched search up to about 0.99 recall, while IVFFlat wins batched search above about 0.99. IVFPQ trades a lower recall ceiling for 8 to 32x memory compression by storing each vector as m one-byte codes.
Is FlashLib production-ready?
pyproject.toml declares version 0.3.0 and the classifier Development Status :: 3 - Alpha. The repository has no published GitHub releases, and the README does not document a deprecation policy or rollback procedure. The last push to the repository was on 2026-08-31.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/flashml-org-flashlib)Star history chart for your README
[](https://hysenlabs.com/projects/flashml-org-flashlib)Was this useful?