KittenTTS now ships a 1.7B voice-cloning model beside its tiny ONNX voices, and the 25 MB tagline only fits one of them
State-of-the-art TTS model under 25MB 😻
At a glance
- What is it?
- KittenML's kittenml package loads two model families through one KittenTTS constructor: Kitten-TTS 2, a 1.7B-parameter 1-bit speech language model with cloning and expression tags, and the 15M to 80M parameter ONNX models from version 0.8. What you download, what hardware you need and how mature each feature is depend on which family you pick.
- Who is it for?
- KittenTTS fits developers who want local text-to-speech in Python with voice cloning and many built-in voices, and who can spare about 6 GB of RAM or 8 GB of GPU memory for Kitten-TTS 2. If you only need a tiny CPU voice, the 0.8 ONNX models are the relevant part, but the default pip install still brings PyTorch.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
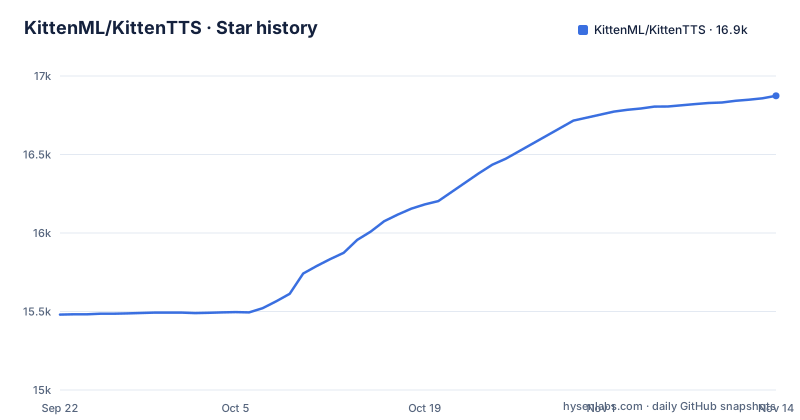
- KittenML/KittenTTS16,874 ★ · +1,394
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| KittenML/KittenTTS | 15.5k | 16.9k |
1,394 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two model families load through one KittenTTS constructor
The repository's tagline still says a TTS model under 25MB, but the project has grown past that. The flagship is now Kitten-TTS 2, a 1.7B-parameter, 1-bit speech language model with in-context voice cloning and expression control, published on Hugging Face as KittenML/kitten-tts-2. Alongside it, the library keeps the lightweight 0.8 ONNX models, which run on CPU with no GPU:
kitten-tts-mini has 80M parameters and is 80 MB. kitten-tts-micro has 40M parameters and is 41 MB. kitten-tts-nano has 15M parameters and is 56 MB in fp32 or 25 MB as int8. Only that last variant matches the 25 MB headline.
Both families load through the same KittenTTS(...) constructor, so switching between them is a change of model ID. The practical consequence is that a reader comparing download sizes needs to know which family a size refers to: the 25 MB figure and the 1.7B model are two very different footprints.
Kitten-TTS 2 needs gigabytes, not megabytes
The quick start prerequisites are Python 3.10 or later, either a CUDA GPU with roughly 8 GB free or a CPU with about 6 GB of RAM, and about 2 GB of disk for the model and audio decoder plus Python dependencies. Install the package and run a first generation:
pip install kittenmlfrom kittenml import KittenTTS
import soundfile as sf
m = KittenTTS("KittenML/kitten-tts-2")
audio = m.generate("Hi! umm.. how are you, I guess? .. uh.. nice to meet you??",
voice="WeatherPresenterCheerful")
sf.write("output.wav", audio, m.sample_rate)The weights come in two sizes. The default is 954 MB and lossless. Passing weights="emb4" downloads a 492 MB file that quantises the token embedding, which costs a little quality. Only the file you request is downloaded.
m = KittenTTS("KittenML/kitten-tts-2", weights="emb4") # half the downloadOutput is 24 kHz. Running Kitten-TTS 2 on a CPU has its own section in the project's docs, and a C++ inference path is offered through KittenML's fork of llama.cpp, kitten-tts-2-cpp.
The default install pulls PyTorch even if you only want the ONNX voices
pip install kittenml installs everything Kitten-TTS 2 needs, including voice cloning, plus the small ONNX runtime for the 0.8 models. That means torch and torchaudio 2.6 or newer, transformers 4.55 or newer, the s3gen vocoder stack (einops, diffusers, omegaconf, hydra-core, s3tokenizer, resemble-perth, pyloudnorm), and espeakng_loader, phonemizer and onnxruntime for the legacy models. With the default install, an edge deployment that only needs kitten-tts-nano still carries PyTorch.
The brotli dependency is there for a specific failure: without it, httpx can fall back to brotlicffi, whose decoder errors mid-stream on some Hugging Face CDN responses and fails the download.
NVIDIA users need a PyTorch CUDA build that matches their driver; on Windows, a missing Visual C++ runtime error from PyTorch is fixed by installing Microsoft's runtime. Two optional backends are not installed by default:
pip install "kittenml[mlx]"
pip install "kittenml[vllm]"
The mlx extra applies only to Apple silicon (mlx 0.29.0 or newer), and the vllm extra pins vllm 0.31.0 and installs only on Linux.
Cloning feeds the reference clip in two ways and runs Whisper when you skip the transcript
Voice cloning uses the same generate method; you pass reference= instead of voice=. The clip should be 5 to 30 seconds of a single speaker, and no fine-tuning or Hugging Face login is needed.
audio = m.generate("This is my own voice, cloned.", reference="my_voice.wav")

# Supplying the transcript skips the Whisper pass
audio = m.generate("This is my own voice.", reference="my_voice.wav",
                   reference_text="what is actually said in the clip")
The transcript is part of the prompt. Leave it out and Whisper transcribes the clip for you, which adds a step to every call; supplying reference_text removes it. The reference reaches the model by two independent routes: a speaker embedding through the projection head, and the clip itself as codec tokens in the prompt, so speaker identity holds up when one route is weak.
KittenML's own measurements on the built-in voices give 0.49 to 0.72 speaker similarity against a clip's own reference and 0.01 to 0.18 against the other 37, and 0.81 when cloning an unseen recording. A reference with two speakers falls outside the stated 5 to 30 second single-speaker input, so cut clips before passing them in.
115 built-in voices keep the eight 0.8 speakers under the same names
m.available_voices returns 115 built-in voices. Eight of them, Bella, Jasper, Luna, Bruno, Rosie, Hugo, Kiki and Leo, are the same speakers as in KittenTTS 0.8, so code written against the ONNX models keeps working when pointed at Kitten-TTS 2.
Decoding presets let each request trade stability against expressiveness, and there is a helper that writes straight to disk:
# Trade stability against expressiveness
audio = m.generate("Hello, world.", voice="Matthew", preset="expressive")

# Save directly to a file
m.generate_to_file("Hello, world.", "output.wav", voice="Bruno")
Kitten-TTS 2 covers 20 languages: English, Arabic, Chinese, French, German, Hindi, Italian, Portuguese, Russian, Spanish, Japanese, Korean, Turkish, Dutch, Swedish, Danish, Finnish, Swahili, Greek and Hebrew. Text preprocessing expands numbers, currencies, dates, units and abbreviations automatically, using the kitten-text-processing package, which is pure Python and reproduces the normalization Kitten-TTS 2 was served with. Long input is split with sentence-aware chunking, and a streaming example ships as example_streaming.py.
Expression tags are beta and steer delivery without guaranteeing it
Kitten-TTS 2 accepts three kinds of markup in the input text: [emotion] tags, inline <event> tags, and (((emphasis))) spans. The expression controls section is marked beta, and KittenML states that emotion control steers delivery rather than guaranteeing it, with the effect varying.
For anyone building a product on top of it, that wording matters. A tag that sounds right on one voice or sentence is not promised to behave the same on another, so expressive output needs listening checks per voice rather than a single test. Combining tags with preset="expressive" adds another variable. The repository includes example_expression.py and a voices-and-expression guide in docs/ for the tag syntax, and a Gradio demo you can run locally:
pip install kittenml gradioThen run python gradio_demo.py. A hosted Kitten-TTS 2 API is also offered free at platform.kittenml.com, with commercial support, custom voices and enterprise licensing available on request.
Package metadata disagrees on the license and GitHub releases trail PyPI
Two pieces of metadata do not line up. The repository license and pyproject.toml say Apache 2.0, while the classifiers in setup.py declare the MIT License. Both are permissive, but a compliance check that reads classifiers will report a different license from the one in LICENSE. Check the LICENSE file and, for commercial work, ask KittenML directly.
Versions also diverge. pyproject.toml and setup.py both say 0.9.7, but the newest GitHub release is 0.8.1 from 2026-02-24, preceded by 0.8 on 2026-02-19 and 0.1 on 2025-08-05. The last push to the repository was 2026-10-27, so work continues, but the GitHub releases page is not where you will see it. The setup.py classifier marks the package as Development Status 3, Alpha, and lists Python 3.10 through 3.12.
Editorial conclusion
KittenTTS fits developers who want local text-to-speech in Python with voice cloning and many built-in voices, and who can spare about 6 GB of RAM or 8 GB of GPU memory for Kitten-TTS 2. If you only need a tiny CPU voice, the 0.8 ONNX models are the relevant part, but the default pip install still brings PyTorch. Before shipping, confirm the license in the LICENSE file given the conflicting metadata, treat expression tags as beta, and track changes through the PyPI version rather than GitHub releases.
Frequently asked questions
What is kitten TTS?
KittenTTS is KittenML's open-source text-to-speech library. Its flagship Kitten-TTS 2 is a 1.7B-parameter 1-bit model with voice cloning and expression control, and it also ships 15M to 80M parameter ONNX models that run on CPU.
How to install Kitten TTS?
Run pip install kittenml with Python 3.10 or later. It installs Kitten-TTS 2 with voice cloning plus the ONNX runtime for the lightweight models; Apple silicon and Linux NVIDIA users can add the kittenml[mlx] or kittenml[vllm] extras.
How to use Kitten TTS?
Create KittenTTS("KittenML/kitten-tts-2"), call generate with your text and a built-in voice such as WeatherPresenterCheerful, and write the audio with soundfile at m.sample_rate. Pass reference= with a 5 to 30 second clip instead of voice= to clone a speaker.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/kittenml-kittentts)Star history chart for your README
[](https://hysenlabs.com/projects/kittenml-kittentts)Was this useful?