jaredpalmer/kev: small Jev-like decision models you can train and run yourself
Jev-like family of decision models built on top of Qwen3.5/3.8 you can train and run on your own
At a glance
- What is it?
- Kev is a family of decision models built on Qwen3.5 and Qwen3.8 that answers yes/no, multiple-choice and rating questions in one request. It ships pretrained weights from 0.8B to 27B and an API that matches TypeSafe's System One, but the Python package is still classified Alpha and the hardware ceiling is real.
- Who is it for?
- Adopt Kev if you need calibrated probabilities over a fixed set of questions and you want the model on your own hardware, since Kev-4B runs on a 32 GB Mac or an L40S and the TypeSafe Python SDK points at a local server unchanged. Avoid it if you need a general chat model, if you have no GPU or Apple Silicon machine, or if your accuracy target is Jev's 0.857 on new sources, because Kev-27B reaches 0.851 and needs an 80 GB GPU.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
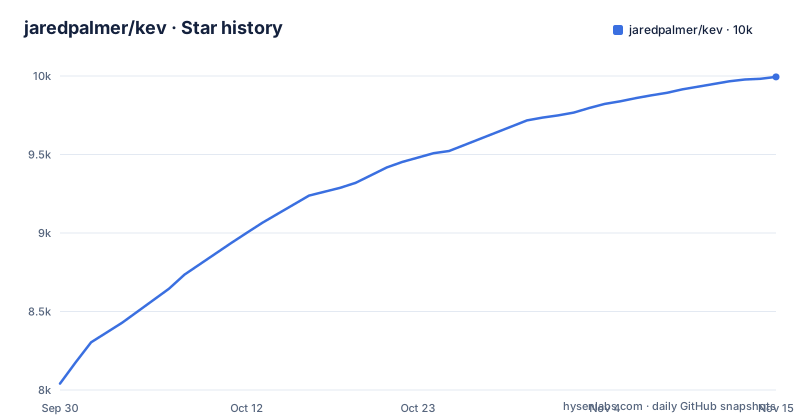
- jaredpalmer/kev9,994 ★ · +1,953
| Repository | 2026-09-30 | 2026-11-15 |
|---|---|---|
| jaredpalmer/kev | 8k | 10k |
1,953 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Kev actually decides, and who it is for
Kev is not a chatbot. It takes a piece of text and a set of questions about that text, and returns answers with probabilities. The README describes three question types: noul for yes/no, choice for multiple-choice, and score for rating. All three go in a single request and share the input text, but the questions cannot read each other's answers. That constraint matters. If you want the model to condition one judgement on another, you have to make two calls.
The intended user is someone who already has a decision task with a known set of labels. Ticket routing is the example the README uses: which department should handle this, does it need urgent human attention, how frustrated is the customer. The model returns probabilities, not just the top label, so you can set your own threshold. The project targets people who want that behaviour without sending text to a hosted API, and who are willing to install Python and download weights.
The lineage is explicit. Kev is based on the architecture described in Jev's Architecture Unmasked, built on Qwen3.5 and Qwen3.8 base models, and its API matches TypeSafe's System One so their Python SDK works against a Kev server. If you have never heard of Jev, the useful framing is simpler: Kev is a small model trained to emit calibrated answers to a fixed question schema.
How the model is built and how a request flows
The repository is a Python package named kev, version 0.1.0, with a pyproject.toml that pins transformers to >=5.17,<6 and torch to >=2.6,<2.9, and requires Python >=3.12,<3.14. Training uses peft, so the 0.8B, 4B and 9B checkpoints are small adapters on a frozen Qwen base, while Kev-27B ships as 51 GB of fully fine-tuned weights rather than an adapter. That is why the first run of a smaller model downloads both an adapter and a base model.
Serving is a separate optional dependency group. The serve extra pulls fastapi, uvicorn, typesafe-sdk and, on Apple Silicon only, mlx-lm. The environment marker means MLX is a no-op on Linux and Windows, where the code path falls back to CUDA or ROCm through torch. The README states that the server picks CUDA or ROCm if you have a GPU and MLX on Apple Silicon.
The API surface is one endpoint, /v1/systemone. You post a state string, a model name, and a questions object. Each question carries a type and instructions, and choice and score questions also carry criteria. The response echoes the model name and returns an answers object keyed by your question names, plus a usage block with input_tokens. For choice, the answer includes a choice, a confidence, and a probabilities map over the criteria. For noul, it returns a single probability. For score, it returns a numeric score, a confidence, a legend mapping indices to labels, and probabilities per index.
Calibration is handled at the checkpoint level. The README says each checkpoint ships with a fitted temperature, so probabilities are intended to be usable without post-hoc fitting on your side. The response example shows a choice answer with confidence 0.21 while the top probability is 0.47. Confidence and probability are not the same field, and you should read the model card for the size you run before treating either as a decision threshold.
There is a training path too. The README mentions a coding-agent skill that runs the whole loop on Modal, from finding your questions to serving the result, and the repository has a modal_app.py at the top level to support it. The details live in the skill, not in the README.
Installing Kev and sending a first request
The README requires Python 3.12 or 3.13 and uv. The repository's .python-version file makes uv sync use 3.13, and the README notes torch has no wheels for 3.14 yet. Clone the repository, sync the serve extra, and start Kev-4B on port 8009.
git clone https://github.com/jaredpalmer/kev.git && cd kev
uv sync --extra serve
uv run --extra serve python -m kev.serve --run jaredpalmer/kev-4b --port 8009
The first run downloads the adapter and the base model, so expect a wait before the server is ready. The --run flag also accepts a local checkpoint directory or a Hub revision in the form jaredpalmer/kev-4b@qwen3, which is how you pin a specific adapter revision rather than tracking the default.
Once the server is up, send it a support ticket. The README's example asks three questions at once: a choice question for the department with three criteria, a noul question about escalation, and a score question for frustration on a three-point scale.
curl -s localhost:8009/v1/systemone -H 'content-type: application/json' -d '{
  "state": "Shoes arrived two weeks late and in the wrong size. Also I see two charges on my card.",
  "model": "kev-latest",
  "questions": {
    "department":  {"type": "choice", "instructions": "Which team should handle this?",
                    "criteria": {"returns": "Exchanges, refunds, wrong or damaged items",
                                 "shipping": "Delivery status, delays, lost packages",
                                 "billing": "Charges, invoices, payment problems"}},
    "escalate":    {"type": "noul",  "instructions": "Does this need urgent human attention?"},
    "frustration": {"type": "score", "instructions": "How frustrated is the customer?",
                    "criteria": ["Calm", "Frustrated", "Very angry"]}
  }}'
The README shows a response from Kev-4B running in bf16 on an Apple M5. The department answer comes back as returns with probabilities 0.47, 0.28 and 0.25 across returns, shipping and billing. The escalation probability is 0.93. The frustration score is 1.44 with a legend mapping 0 to Calm, 1 to Frustrated and 2 to Very angry. Note that the ticket mentions two charges, and the model still puts billing third. That is the kind of result worth inspecting before you wire the output into an automated action.
If you would rather not install anything, the README points to a Hugging Face Space that runs Kev-4B and Kev-0.8B in the browser.
Where Kev is the wrong tool
The README's own numbers set the boundary. On new sources, meaning datasets and policy rules Kev never saw during training, Kev-4B scores 0.817 development and 0.838 test. Kev-27B reaches 0.851 and 0.889. Jev, the hosted system Kev imitates, scores 0.857 on the development sets. The README is direct that Jev has only been run on development sets and that the comparison is not controlled, because nobody knows what Jev was trained on. So on unfamiliar questions, Kev is close to Jev but not equal to it.
The trained-source column is held-out examples from the datasets Kev was trained on. Those numbers are higher, which is expected, and they are not a guide to your own data. If your questions look like the training distribution, Kev will look better than it is.
Hardware is the other hard limit. Kev-0.8B runs on any Apple Silicon Mac or an L4. Kev-4B and Kev-9B need a 32 GB Mac, an L40S or an H100. Kev-27B needs a B200, H200 or an H100 with 80 GB. The serve extra installs MLX only on darwin arm64, and the README describes serving on CUDA or ROCm GPUs and on Apple Silicon.
Finally, the pyproject classifier says Development Status :: 3 - Alpha and the package version is 0.1.0, although the README presents the models as Kev 1.0. The README says each model card gives the document length before accuracy drops.
Kev compared with calling Jev directly
The obvious alternative is Jev through TypeSafe's API. The API shape is the same, which is the point: the Kev README says the TypeSafe Python SDK works against a Kev server unchanged, so switching is a base URL change rather than a rewrite.
The difference is operational. Jev is hosted, so you send your text to someone else's servers. Kev runs on your machine, which means the text stays local and the marginal cost of a request is electricity. The trade is accuracy and maintenance. Jev scores 0.857 on new sources in the development column, and Kev-27B scores 0.851, so the gap is within a point at the top end. But Kev-27B needs an 80 GB GPU, and Kev-4B, which fits on a 32 GB Mac, gives up about four points on the same measure.
There is a second alternative worth naming: fine-tuning a general instruct model on your own labelled examples. Kev's advantage there is the output contract. A general model needs prompt engineering and parsing to produce a labelled answer with a probability, and the probabilities it produces are not calibrated by default. Kev ships a fitted temperature per checkpoint, which is the specific thing you would otherwise have to build. If your task is open-ended generation rather than a fixed question set, Kev is the wrong shape entirely and a general model is the right one.
Maintenance, licensing and what it costs to keep running
The repository is not archived, and the last push was on 2026-11-02. The latest releases listed are kev-1.0 on 2026-10-01, kev-family (marked superseded by Kev 1.0) on 2026-09-20, and v0.1.0 on 2026-09-17 for kev-0.5b. The README says earlier versions are kept as Hub tags on each model card, and the kev-1.0 GitHub release has the 0.8B, 4B and 9B checkpoints with SHA-256 checksums; Kev-27B's 51 GB of weights are on the Hub only. That gives you a way to pin a specific artifact rather than tracking a moving default.
The README points to release notes in docs/releases/kev-1.0.md listing what changed since the previous family release and what is known not to work well, and lists a Hub revision and temperature for each Kev 1.0 model. The dependency pins are tight, with torch capped below 2.9 and transformers capped below 6, so a major bump in either will require a coordinated update. The dev group pins modal to exactly 1.5.5, which suggests the Modal training path is sensitive to that version.
Licensing is Apache-2.0 for the repository, and the pyproject declares license = "Apache-2.0" with license-files pointing at LICENSE. Apache-2.0 includes a patent grant and requires attribution and notice retention. The README's model table lists the base-model licence for each size as Apache-2.0, and each model card has the details. Check the model card for the size you intend to deploy before shipping anything. This is a description of what the files say, not legal advice.
Editorial conclusion
Adopt Kev if you need calibrated probabilities over a fixed set of questions and you want the model on your own hardware, since Kev-4B runs on a 32 GB Mac or an L40S and the TypeSafe Python SDK points at a local server unchanged. Avoid it if you need a general chat model, if you have no GPU or Apple Silicon machine, or if your accuracy target is Jev's 0.857 on new sources, because Kev-27B reaches 0.851 and needs an 80 GB GPU. Verify first that your questions resemble the new-source evaluation rather than the trained-source one, and read the model card for the size you plan to run before downloading weights.
Frequently asked questions
What hardware does jaredpalmer/kev need to run?
The README lists Kev-0.8B as running on any Apple Silicon Mac or an L4, Kev-4B and Kev-9B on a 32 GB Mac, L40S or H100, and Kev-27B on a B200, H200 or H100 with 80 GB. The server uses CUDA or ROCm on a GPU and MLX on Apple Silicon, and the MLX dependency is installed only on darwin arm64.
Can jaredpalmer/kev replace Jev in an existing application?
The README states that the API matches TypeSafe's System One and that the TypeSafe Python SDK works against a Kev server unchanged, so the integration can stay the same. Accuracy does not match exactly: on new sources Kev-27B scores 0.851 against Jev's 0.857, and the README notes the comparison is not controlled because Jev's training data is unknown.
Which jaredpalmer/kev model should I start with?
The README says to start with Kev-4B, move to Kev-9B with a bigger GPU, and use Kev-27B if you have an 80 GB GPU and want the most accurate Kev. Kev-0.8B is for when size matters more than accuracy.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- Kev: Tiny Jev-like family of decision models built on top of Qwen3.5Hacker News · Sep 21, 2026 · 463 points · 210 comments
- kev: Jev-like model built on Qwen2.5-0.5BHacker News · Sep 19, 2026 · 3 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jaredpalmer-kev)Star history chart for your README
[](https://hysenlabs.com/projects/jaredpalmer-kev)Was this useful?