Karpathy LLM Wiki for Obsidian: Graph Retrieval Without Embeddings
Karpathy's LLM Wiki implementation plugin for Obsidian - turns notes and PDFs into a linked, LLM-powered knowledge base with entity pages, concept pages, graph-powered Q&A, and local-first privacy.
At a glance
- What is it?
- An Obsidian plugin that builds entity and concept pages from your notes and PDFs, then answers questions by walking the wiki link graph instead of a vector store. The interesting part is the retrieval design; the caveat is that the README is the only evidence you get.
- Who is it for?
- Adopt it if you already write in Obsidian, want wiki pages generated from your own notes, and would rather pay for a graph walk than maintain a vector database. Skip it if you need retrieval over hundreds of thousands of chunks, if you cannot accept a plugin holding your provider API key, or if you want a headless pipeline outside the editor.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
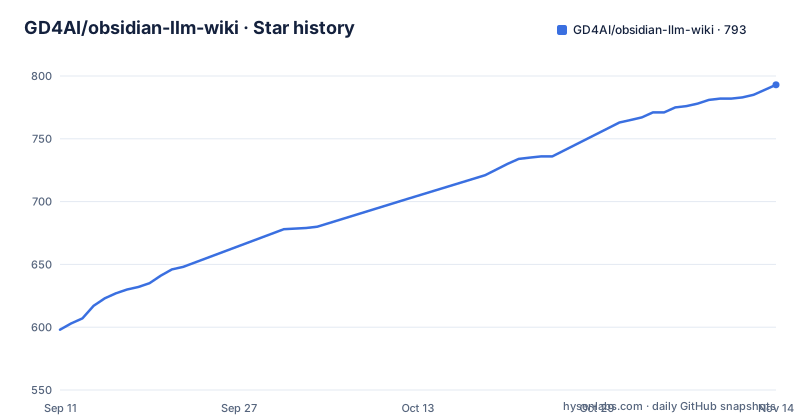
- GD4AI/obsidian-llm-wiki793 ★ · +195
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| GD4AI/obsidian-llm-wiki | 598 | 793 |
195 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem is not search, it is that your notes never became a wiki
Obsidian users accumulate folders of Markdown. The links between those files exist only where the author typed them, and nobody types them consistently for two years. Karpathy's LLM Wiki gist proposed a fix: have a model read the corpus and emit entity pages and concept pages, then treat those pages as the retrieval index. This plugin is one implementation of that idea, shipped as a community plugin with the id karpathywiki. The target user is someone who already lives in Obsidian and wants the generated wiki to sit next to the source notes rather than in a separate application. The repository lists direct competitors that are not Obsidian plugins: a Tauri desktop app, a skill bundle for coding agents, and a TypeScript CLI. The distinguishing claim in the README is packaging, not capability.
Personalized PageRank instead of a vector index
The README names the retrieval mechanism precisely: Personalized PageRank, citing Haveliwala 2002, with a Monte Carlo approximation attributed to Fogaras 2005 and a five-stage seed-selection cascade. In plain terms, the seed stage picks starting notes for a query, then the rank propagation spreads weight along wiki links, and the top-ranked nodes become context for the model. There is no embedding step and no vector database, which is why the project can claim zero runtime dependencies beyond the bundled Vercel AI SDK v6. The README also publishes one number, PPR @5 at 27.1% against pure kNN at 24.1% on the project's own corpus, and labels it the only published number in this space. Treat that as a single self-reported figure on an undisclosed corpus, not as a general result. The architecture has a second consequence worth stating: retrieval quality depends on link density. A vault with few internal links gives the rank propagation little to walk.
Ingest, duplicate detection and the gates around generated text
Beyond Markdown, the plugin ingests PDFs and, through MinerU, images and Office formats. The README describes PDF ingest as cache-only with OCR paths, and points to a separate PDF-OCR guide. Generated output is not written unconditionally. The release notes for 1.27.1 mention a sourced-paragraph rewrite guard, contradiction gates, and an ingest candidate gate, which suggests the pipeline checks proposed content against sources before committing it. There is also a lint health scan and a Smart Fix All action, and a vault-wide link repoint. Duplicate detection is split into Tier 1 and Tier 2. The README does not explain what separates the tiers, and that gap matters if you are deciding whether to point the plugin at a vault that already contains overlapping notes.
Installing it and the settings you actually touch
The plugin installs from the Obsidian community marketplace, where it is listed as karpathywiki. The README states a runtime requirement of Obsidian 1.11.4 or later, on desktop and mobile. Provider configuration covers 16 or more options, including Anthropic, OpenAI, Bedrock with either an API key or SSO/IAM, Gemini, DeepSeek, Qwen, Grok, Kimi, GLM, MiniMax, Step, Hunyuan, MiMo, Gemma, Ollama, LM Studio, OpenRouter, an Anthropic-compatible endpoint, and Codex OAuth. Local-first operation is a stated mode, which in practice means pointing the provider setting at Ollama or LM Studio so note content does not leave the machine. The README references a per-step taskPolicies UI, meaning different pipeline steps can be assigned different models or providers. Read docs/MODEL-GUIDE.md before assuming a given provider is wired for every step.
Where the design breaks down
The graph approach has a structural failure mode. If your vault is a flat pile of daily notes with almost no wikilinks, Personalized PageRank has nothing to propagate over, and the five-stage seed cascade is doing all the work. The README's own comparison is against kNN on the project corpus, which tells you nothing about how the margin behaves on a sparse graph. Second, the plugin runs inside Obsidian, so anything scheduled, scripted or run on a server is out of scope for the plugin itself; the repository points to a sister CLI project for that. Third, the feature list is long enough that version churn is a real cost: 46 commits between 1.27.0 and 1.27.1, and the release notes describe behavioural changes to generated text, not cosmetic fixes. Fourth, the README is unusually dense with claims and light on methodology.
The honest alternative is chunk-based retrieval
The README names atomicstrata/llm-wiki-compiler as a direct competitor, a TypeScript CLI using chunk-based retrieval. The difference is not cosmetic. A chunk-based system splits documents into passages, embeds them, and retrieves by vector similarity, which means it works on a corpus with no links at all and scales with index size rather than graph connectivity. The graph approach here instead depends on the structure your notes already have, and its answers are traceable to named wiki pages rather than to anonymous chunks. If your vault is well linked, the graph route gives you an explanation path. If your vault is not, the chunk route degrades more gracefully. Neither is universally better, and the README's single comparison number is not enough to settle it.
Licence, maintenance and what upgrading costs
The project is Apache-2.0, which permits commercial use and modification and includes an explicit patent grant, with the usual requirements around preserving notices and stating changes. That is a permissive licence, and it does not extend to the models you call: your provider's terms govern what happens to the text you send. On maintenance, the repository shows releases at 1.27.0 on 2026-08-27 and 1.27.1 on 2026-09-06, with the last push to main on 2026-09-10, so the cadence is roughly weekly. A patch that ships 46 commits and changes generated-text behaviour is not a drop-in update; if you have hand-edited generated wiki pages, back up the vault before pulling a new tag. The README claims 3993 tests as of 1.27.1. That is a count, not a coverage statement, and it says nothing about which paths the tests exercise.
Editorial conclusion
Adopt it if you already write in Obsidian, want wiki pages generated from your own notes, and would rather pay for a graph walk than maintain a vector database. Skip it if you need retrieval over hundreds of thousands of chunks, if you cannot accept a plugin holding your provider API key, or if you want a headless pipeline outside the editor. Before installing, verify three things: that your Obsidian build is at least 1.11.4, that the provider you intend to use appears in the supported list, and that the release tag you install matches a commit you can inspect.
Frequently asked questions
what is obsidian llm wiki
It is the Karpathy LLM Wiki idea built as an Obsidian community plugin named karpathywiki. It generates entity and concept pages from notes, PDFs, images and Office documents, then answers questions conversationally over the pages it wrote.
What is the difference between Obsidian and an LLM wiki?
Obsidian is the editor the plugin runs inside, on desktop and mobile, and it supplies the note graph, Graph View and the command palette. The LLM wiki part is the plugin's own work: multi-page knowledge generation from your notes and documents, plus a conversational query layer over the generated pages.
Does obsidian-llm-wiki use embeddings or a vector database?
No. Retrieval is graph-based, using Personalized PageRank with a Monte Carlo approximation over the wiki-link graph, seeded by a five-stage cascade, with duplicate detection in two tiers. The only published figure in this space is the project's own: 27.1 percent at five retrieved pages against 24.1 percent for pure kNN on its corpus.
Which LLM providers does the karpathywiki plugin support?
Sixteen or more, including Anthropic, OpenAI, Bedrock by API key or by SSO and IAM credentials, Gemini, DeepSeek, Qwen, Grok, Kimi, GLM, MiniMax, Step, Hunyuan, MiMo, Gemma, Ollama, LM Studio, OpenRouter, an Anthropic-compatible option and Codex OAuth. The provider SDK is bundled so the plugin needs no backend.
What can obsidian-llm-wiki ingest besides Markdown notes?
PDF, images and Office documents including DOCX, PPTX and XLSX, with MinerU used for the multi-format path, a cache-only PDF route and OCR paths. An ingest candidate gate decides what becomes a page, and quotes from the source page are kept verbatim with provenance footnotes.
What are the system requirements for obsidian-llm-wiki?
Obsidian 1.11.4 or newer on desktop or mobile, and Node 22 or newer for development since that is the declared engine. The package manager is declared as pnpm 10.14.0, and the plugin builds to a single main.js through esbuild. The licence is Apache-2.0.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/gd4ai-obsidian-llm-wiki)Star history chart for your README
[](https://hysenlabs.com/projects/gd4ai-obsidian-llm-wiki)Was this useful?