Maxun: A No-Code Robot Builder That Turns Websites into Structured APIs
🔥 The open-source no-code platform for web scraping, crawling, search and AI data extraction • Turn websites into structured APIs in minutes 🔥
At a glance
- What is it?
- Maxun is an open-source, no-code platform for web scraping, crawling, search, and AI-driven extraction. This review examines its robot-based architecture, setup, limitations, and whether it fits your data pipeline.
- Who is it for?
- Adopt Maxun if you want a no-code, self-hostable web data platform and can accept its AGPL-3.0 license and a young codebase (v0.1.0). Avoid it if you need a stable, production-grade scraper with a mature ecosystem or if AGPL is a dealbreaker.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
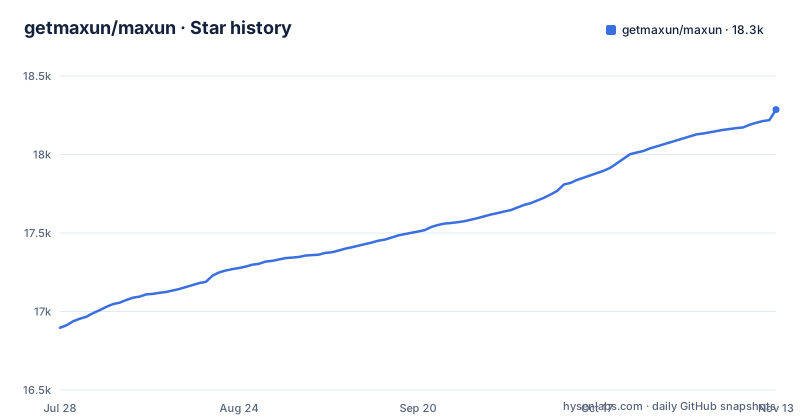
- getmaxun/maxun18,286 ★ · +1,390
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| getmaxun/maxun | 16.9k | 18.3k |
1,390 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Maxun Actually Solves
Maxun targets a specific pain: turning a website into a structured API without writing scraper code. The README frames it as a unified no-code platform for real-time scraping, crawling, search, and AI extraction. The intended user is someone who needs data from the web but does not want to maintain a custom scraper, or a developer who wants a quick way to expose a site's data as an API. The core promise is speed: record actions once, and get a reusable robot that can be triggered via a UI, CLI, or SDK. That is a real gap. Most scraping tools either require coding or are closed-source SaaS. Maxun offers an open-source middle ground, though its maturity is still early.
The Robot Architecture: Four Job Types
Maxun organizes everything around robots, each designed for a different data job. The Extract robot emulates real user behavior and captures structured data. It has two modes: Recorder Mode, where you record actions as you browse, and AI Mode, where you describe what you want in natural language and an LLM does the extraction. Scrape robots convert full webpages into clean Markdown or HTML and capture screenshots, which suits AI workflows and document processing. Crawl robots crawl entire websites and extract content across pages. Search robots search the web and extract results with time-based filters. The README also lists Agent robots that use AI to discover where the data lives, Monitoring robots that track websites and notify you of changes, and Document Extraction & Parsing. This division is practical: you pick a robot type based on the shape of the data you need, rather than writing a generic scraper.
Getting Started: Commands and Configuration
The README's Quick Start names the hosted version as the fastest route and links guides for running Maxun locally with Docker Compose or without Docker. Around that sits an ecosystem: there is a hosted app at app.maxun.dev, a docs site, and a CLI and SDK. The CLI creates robots, triggers runs, and retrieves data from the terminal. The SDK covers scraping, extraction, automation and more, and the README also lists an API and an MCP server for connecting AI agents. The install steps themselves live on the docs site, alongside an environment-variables reference, and the repository root carries a `docker-compose.yml` that runs Postgres, MinIO, backend and frontend services.
AI Mode and Recorder Mode: The Trade-Off
The two Extract modes represent a clear trade-off. Recorder Mode gives you deterministic control: you record clicks, inputs, and navigation, and the robot replays them. This works well for stable sites, but it breaks when the site's structure changes. AI Mode is more flexible: you describe what you want, and an LLM figures out the extraction. That is powerful for messy or dynamic pages, but it introduces non-determinism and a dependency on an LLM provider. The dependency list includes the Anthropic SDK, and the compose file sets `OLLAMA_BASE_URL` to a local Ollama instance by default. If you need reliable, repeatable extraction, Recorder Mode is safer. If you need to handle sites that change often, AI Mode may save time but at the cost of predictability.
Licensing and Maintenance: AGPL-3.0 and Early Versioning
Maxun is licensed under AGPL-3.0, which has real implications. If you self-host and expose the service to users over a network, you may be required to offer the source code to those users. That is a significant consideration for commercial use. The repository is on the develop branch, with the latest release at v0.1.0. The version number signals that this is pre-1.0 software. The last push date is October 2026, which suggests active development. The README lists sponsors like proxy providers, which indicates the project relies on external funding. That is not a quality signal, but it does point to a potential risk: if sponsorship dries up, maintenance could slow. You should check the release notes for breaking changes before upgrading.
Limitations and Failure Modes
The README itself only links out to the self-hosting guides, so a production setup depends on the docs site. Another failure mode is site breakage: any recorder-based scraper will fail when a site changes its HTML structure. The README's feature list does not describe CAPTCHA, login-wall or rate-limit handling; its sponsors are proxy providers, and the dependencies include browser fingerprint generation and injection. For sites with aggressive bot detection, Maxun may not be the right tool. AI Mode also needs an LLM: the dependencies include the Anthropic SDK, and the compose file points `OLLAMA_BASE_URL` at a local Ollama instance by default. These are gaps you must verify before committing.
Alternatives: How Maxun Differs
A direct alternative is Scrapy, a Python framework for building scrapers. Scrapy gives you full control over requests, parsing, and pipelines, but you must write code. Maxun is no-code, so it trades flexibility for speed. Another alternative is Playwright, a browser automation library. Playwright can record actions and extract data, but it is a library, not a platform. Maxun wraps similar browser automation into a robot model with a UI, CLI, and SDK. The difference is abstraction: Maxun hides the browser details behind robot types, while Playwright exposes them to you. If you need custom logic or deep integration, Playwright or Scrapy are better. If you want a quick, no-code solution, Maxun wins. The trade-off is control versus convenience, and Maxun leans heavily toward convenience.
Editorial conclusion
Adopt Maxun if you want a no-code, self-hostable web data platform and can accept its AGPL-3.0 license and a young codebase (v0.1.0). Avoid it if you need a stable, production-grade scraper with a mature ecosystem or if AGPL is a dealbreaker. Before adopting, verify the self-hosting requirements, the robot recorder's handling of dynamic sites, and the AI mode's dependency on external LLM providers. Test with a small extraction robot first, and check the docs for deployment and scheduling specifics.
Frequently asked questions
How do I run maxun on my own machine?
The repository documents two local paths, setup with Docker Compose and setup without Docker, both hosted on the documentation site, and the root carries a `docker-compose.yml` with Postgres 13, MinIO, backend and frontend services. Configuration comes from a `.env` file referenced by `env_file`, with the variable list documented separately.
What does maxun use a browser for?
Extraction emulates real user behavior, so the backend runs a Chromium browser through Playwright with `--no-sandbox` and `--headless=new` under a `seccomp=unconfined` security option. The dependency list adds browser fingerprint generation and an ad blocker alongside the browser driver, and cheerio handles HTML separately from the browser path.
Can I build maxun from source instead of pulling the published image?
Yes, by uncommenting the `build` block in the compose file, which sets `context: .` and points at `Dockerfile.backend` or `Dockerfile.frontend`. With those lines commented out, the backend service pulls `getmaxun/maxun-backend:latest` and the checked in Dockerfiles are not used.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/getmaxun-maxun)Star history chart for your README
[](https://hysenlabs.com/projects/getmaxun-maxun)Was this useful?