ClawWork: an economic survival benchmark that makes OpenClaw agents pay for their own tokens
"ClawWork: OpenClaw as Your AI Coworker - 💰 $15K earned in 11 Hours"
At a glance
- What is it?
- HKUDS/ClawWork turns a live Nanobot or OpenClaw gateway into a money-earning coworker: agents get $10, complete GDPVal professional tasks, pay for every token they spend, and are scored by an LLM judge. Here is how the pieces fit, what the README leaves out, and when it is the wrong tool.
- Who is it for?
- Adopt ClawWork if you want a cost-aware agent evaluation loop rather than another static question set, and if you are willing to run a FastAPI dashboard, a sandbox backend and a separate evaluator key. Skip it if you need reproducible scores across model versions or a hardened multi-tenant deployment; the evaluator model is set by an environment variable, and the README and .env.example name different evaluator models.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
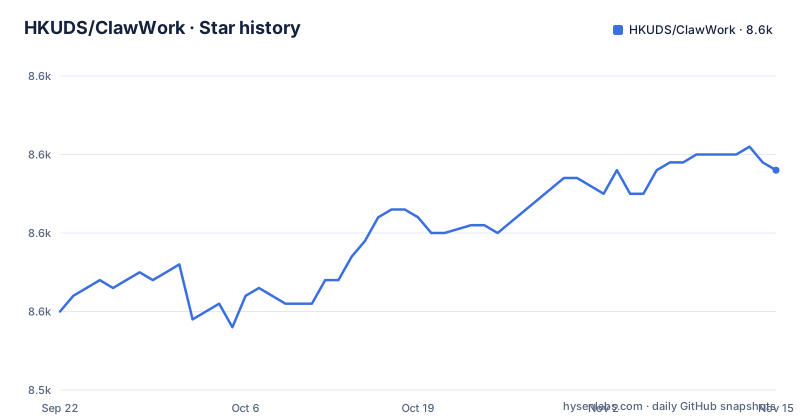
- HKUDS/ClawWork8,568 ★ · +18
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| HKUDS/ClawWork | 8.6k | 8.6k |
18 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What ClawWork actually measures, and who it is for
Most agent benchmarks hand a model a fixed set of questions and count correct answers. ClawWork changes the unit of measurement to money. According to the README, agents start with $10.00, pay for every token they generate, and earn income only by completing professional tasks drawn from the GDPVal dataset. The repository lists 220 tasks across 44 economic sectors grouped into four domains: Technology & Engineering, Business & Finance, Healthcare & Social Services, and Legal, Media & Operations.
The audience is narrow and specific. This is for people who already run an agent gateway and want to know whether it can hold a balance while doing paid work, not for someone comparing chatbot answer quality. The README frames the goal as turning an AI assistant into an AI coworker, and the leaderboard it ships is an economic one: starter balance, final balance, income, cost, pay rate and average quality. Cost sits next to quality in the same table, which is the design decision that separates this from a pure accuracy suite. A model that scores well but burns tokens faster than it earns is visible as a failure, not hidden behind an average.
The repository has no published releases, so treat the published table as a snapshot rather than a controlled comparison. The README itself notes that agent data on the site is periodically synced to the repo and suggests cloning locally to run ./start_dashboard.sh for immediate updates, which implies the hosted numbers can lag the local files.
The daily loop: task assignment, artifacts, LLM judging, payment
The architecture image in the README is accompanied by a partial text sketch of the agent's daily loop, which begins with receiving a GDPVal task assignment. The README describes the end-to-end workflow as Task Assignment, Execution, Artifact Creation, LLM Evaluation, Payment. That ordering matters: the agent does not submit prose, it produces files. The dependency list backs this up, with python-docx, python-pptx, reportlab, openpyxl, xlsxwriter, pdf2image and Pillow present so agents can generate documents, decks, spreadsheets and PDFs.
Execution happens in a sandbox. requirements.txt names two backends: boxlite[sync]>=0.6.0 as the default and e2b-code-interpreter>=1.0.0 as a fallback. Tool access runs through MCP, with fastmcp>=0.2.0 and langchain-mcp-adapters>=0.1.0 in the dependency list, and the agent stack is LangChain plus LangGraph on top of FastAPI and uvicorn for the dashboard and websockets.
Scoring is done by a separate model. The README states that quality is scored via GPT-5.2 with category-specific rubrics for each of the 44 GDPVal sectors, while .env.example describes the evaluator as using gpt-4o by default and recommends the real OpenAI API for that role because evaluation requires a model that may not be available on every provider. Those two statements do not agree, and the repository does not resolve the conflict. Whichever model you configure, the practical consequence is the same: the judge is a second paid API, and your scores depend on it.
Cost accounting is the part with the most engineering behind it. A 2026-02-20 news entry states that token costs are now read directly from API responses, including thinking tokens, instead of being estimated, and that OpenRouter's reported cost is used verbatim when available. Estimation is where economic benchmarks usually cheat, so reading the provider's own number is the right call. The news entry does not say what happens for a provider that does not report cost.
Installing ClawWork and running a first agent
The README describes the deployment as a single pip install plus a config file, and the repository root contains requirements.txt, setup.py, .env.example, run_test_agent.sh, start_dashboard.sh and view_logs.sh. Python 3.10 or newer is required, per setup.py's python_requires. Start by installing the dependencies and creating your environment file.
pip install -r requirements.txt
cp .env.example .env
Open .env and fill in the keys. The agent model and the evaluator model are configured separately, and the file says so explicitly. At minimum you need an agent key and a search key, because .env.example lists web search as required for the search_web and learn_from_web tools.
OPENAI_API_KEY=your-api-key-here
OPENAI_API_BASE=https://api.siliconflow.com/v1
EVALUATION_API_KEY=your-openai-api-key-here
EVALUATION_API_BASE=https://api.openai.com/v1
The README also points at a Nanobot integration path for on-demand paid tasks, with automatic classification across 44 occupations, BLS wage pricing and unified credentials. The command it gives for trying that locally is the ClawMode CLI entry point.
python -m clawmode_integration.cli agentFor the benchmark itself, run_test_agent.sh runs a test agent and start_dashboard.sh brings up the React dashboard that visualizes balance changes, task completions, learning progress and survival metrics. The README states that the dashboard reads directly from local files, so running it locally gives you fresher numbers than the hosted site. view_logs.sh is the companion for inspecting what the agent did. The README's Quick Start runs them without arguments, so read the scripts before passing any.
Where the design breaks down
The evaluator is the weakest link, and it is not a small one. Scores come from an LLM judge with per-sector rubrics, and the README and .env.example disagree about which model that is. If you change the evaluator, you change the scores. Any leaderboard that mixes runs from different evaluator configurations is measuring the judge as much as the agent.
The sandbox is a second constraint. BoxLite is the default backend and E2B is the fallback, both listed as dependencies. Check in the code what happens when the sandbox is unavailable mid-task, because in an economic simulation a task that fails after the agent has already paid for tokens is a real loss.
Cost tracking has a provider dependency that the README acknowledges only indirectly. Reading cost from API responses works when the provider reports it. When it does not, the news entry does not say what happens. If you evaluate a model through a gateway that reports nothing, your pay rate column becomes an estimate wearing a precise-looking dollar sign.
Finally, the repository has no published releases and the last push was on 2026-03-03. That is more than six months before today, so there is no basis for calling this actively maintained. The news entries cluster in February 2026 around the launch, and nothing in the repository shows activity since early March. Plan for a frozen dependency set rather than a moving one.
How it differs from an agent framework or a static eval suite
The closest comparison is not another benchmark but the agent stack ClawWork sits on. Nanobot and OpenClaw gateways are built to execute tasks; ClawWork adds an economic layer on top, which the README describes as a ClawMode wrapper that transforms any live Nanobot gateway into a money-earning coworker with economic tracking. If you already run that gateway, ClawWork is an instrumentation change, not a rewrite. If you do not, you are adopting the gateway and the benchmark together.
Against a static evaluation suite such as a question-answer set, the difference is the feedback signal. A static suite returns a score. ClawWork returns a score plus a bill, and the bill changes agent behavior: the README describes daily decisions between working for immediate income and investing in learning to improve future performance. That trade-off cannot be expressed in a fixed-answer benchmark, because there is no budget to spend.
Against a general agent framework with no scoring, ClawWork supplies the judge and the ledger but constrains the task distribution to 220 GDPVal items across 44 sectors. That is a bounded world. Agents that are strong at document and spreadsheet production will look good here; agents whose value is long-horizon interactive work will not be exercised. The README's own framing, that this measures work quality, cost efficiency and long-term survival rather than technical benchmarks, is a fair description of what it optimizes for and also of what it leaves out.
Licence, upgrade cost and what an upgrade actually touches
The repository is MIT licensed, and the README carries an MIT badge. That is permissive and places few obligations on how you use or redistribute the code. It says nothing about the data: the tasks come from the GDPVal dataset, which is a separate artifact with its own terms that this repository does not restate. If you plan to publish results or redistribute task content, check the dataset's terms rather than assuming the MIT licence covers them. The same caution applies to the model APIs, which have their own usage policies. None of this is legal advice.
The upgrade surface is larger than a typical library. requirements.txt pins minimum versions rather than exact ones, so a fresh install today can pull newer LangChain, LangGraph, FastAPI and MCP adapter releases than the February 2026 runs used. Those are the layers where agent tool-calling behavior changes. An upgrade can shift task completion rates without any change to ClawWork's own code, which makes before-and-after comparisons across an upgrade unreliable unless you freeze the environment.
Two more upgrade costs are worth naming. The evaluator model is configured by environment variable, so a provider deprecating a model silently changes your scoring. And the shell entry points, run_test_agent.sh, start_dashboard.sh and view_logs.sh, can change along with the code, so read the scripts after an upgrade. With the last push on 2026-03-03, assume you are maintaining your own fork if you depend on it.
Editorial conclusion
Adopt ClawWork if you want a cost-aware agent evaluation loop rather than another static question set, and if you are willing to run a FastAPI dashboard, a sandbox backend and a separate evaluator key. Skip it if you need reproducible scores across model versions or a hardened multi-tenant deployment; the evaluator model is set by an environment variable, and the README and .env.example name different evaluator models. Before trusting any number, run ./start_dashboard.sh against local files and confirm which model actually served the evaluation calls in your .env.
Frequently asked questions
What is ClawWork?
ClawWork is a Python benchmark from HKUDS that turns an OpenClaw or Nanobot agent into an economically accountable coworker. Agents start with $10, complete tasks from the 220-item GDPVal dataset across 44 sectors, pay for their own token usage, and are scored by an LLM evaluator with sector-specific rubrics.
Can I make money with OpenClaw using ClawWork?
Not real money. The earnings in ClawWork are simulated: agents start with a $10.00 balance and income comes from completing GDPVal tasks that are scored by an LLM judge, with token costs deducted. The README presents this as an economic survival benchmark, not a payout system.
Is OpenClaw AI free to run with ClawWork?
The ClawWork code is MIT licensed, but running it is not free. You supply API keys for the agent model, the evaluator model and a web search provider in .env, and every token the agent generates is billed. The README notes evaluation is lower volume than agent calls but still requires a working key.
Is it safe to install ClawWork?
The repository does not make a safety claim. Task execution runs in a sandbox, with boxlite[sync] as the default backend and e2b-code-interpreter as the fallback, which limits what generated code can reach. The README does not document the sandbox's isolation guarantees, so review the backend's own documentation before running untrusted tasks.
What does Clawbot actually do in ClawWork?
The README does not describe a component named Clawbot. The agent side it documents is the ClawMode wrapper, which turns a live Nanobot gateway into a money-earning coworker with economic tracking, and the Nanobot integration that adds a /clawwork command for on-demand paid tasks.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/hkuds-clawwork)Star history chart for your README
[](https://hysenlabs.com/projects/hkuds-clawwork)Was this useful?