Text Embeddings Inference: A Rust-Based Serving Layer for Embedding Models
A blazing fast inference solution for text embeddings models
At a glance
- What is it?
- Hugging Face's Text Embeddings Inference (TEI) is a Rust toolkit for serving embedding and sequence classification models with dynamic batching and Flash Attention. It trades broad model support for speed and operational simplicity, making it a strong fit for production embedding APIs.
- Who is it for?
- Adopt TEI if you serve supported embedding models (BERT, Qwen3, GTE, etc.) at scale and need low latency with token-based dynamic batching. Do not adopt it if you require models outside the supported list, need custom pooling beyond the provided options.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
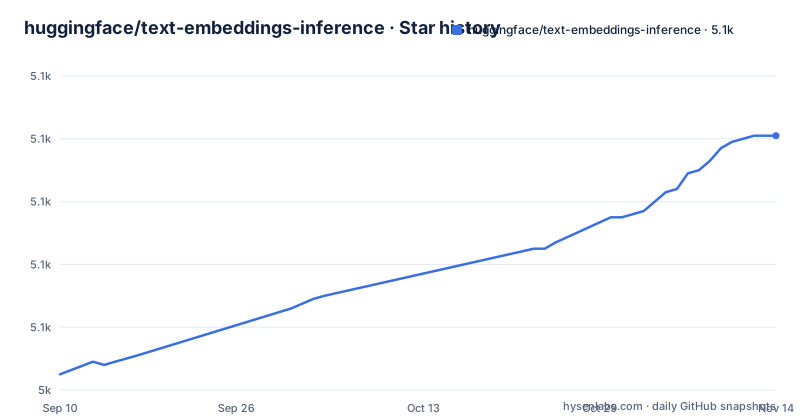
- huggingface/text-embeddings-inference5,121 ★ · +76
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| huggingface/text-embeddings-inference | 5k | 5.1k |
76 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What TEI Solves and Who Should Care
Text Embeddings Inference (TEI) addresses a narrow but painful problem: serving open source text embedding models with low latency and high throughput in production. If you have built a retrieval pipeline around models like BAAI/bge-base-en-v1.5 or Qwen3-Embedding, you know that Python-based inference servers often add graph compilation overhead or waste GPU cycles on static batching. TEI is written in Rust and designed to eliminate the model graph compilation step, load weights directly from safetensors or ONNX files, and batch requests dynamically based on token count rather than fixed batch sizes. The intended user is an engineer running a semantic search or RAG backend who wants a dedicated serving container that boots quickly and handles variable request loads without manual tuning.
The Architecture: Rust, Candle, and Dynamic Batching
The README lists Candle, Flash Attention, and cuBLASLt as the core compute dependencies. Candle is Hugging Face's Rust machine learning framework, which means TEI runs the model forward pass directly in Rust. Token-based dynamic batching is the other key mechanism. Instead of grouping requests by a fixed batch size, TEI fills each batch according to the number of tokens in the incoming requests. That reduces wasted compute on short sequences and improves GPU utilization when request lengths vary. The README also mentions safetensors and ONNX weight loading.
Getting It Running: Docker and Supported Models
The quickest path is Docker. The README has Docker and Docker Images sections, and the project homepage is huggingface.co/docs/text-embeddings-inference/quick_tour. The README also has an API Documentation section. You can also use gRPC, which the README lists as a feature. The README has sections on using a private or gated model and on air-gapped deployment. The supported model families are explicit: Nomic, BERT, CamemBERT, XLM-RoBERTa, JinaBERT with Alibi, Mistral, Alibaba GTE, Qwen2, MPNet, ModernBERT, Qwen3, and Gemma3. Sequence classification and re-ranking are limited to CamemBERT and XLM-RoBERTa. This list is a constraint, not a suggestion.
Real Limitations: Model Support and Hardware Assumptions
The biggest limitation is the hard boundary on model architectures. TEI will not serve a transformer model that falls outside the listed families. If your embedding model uses a custom position encoding or a non-standard pooling head, you cannot just point TEI at it. The README has a separate section for AMD Instinct GPUs (ROCm), and the repository ships a Dockerfile-rocm. The feature list names Metal support for local execution on Macs, and there is an Apple Silicon (Homebrew) local install section. That means TEI is not a drop-in replacement for a general inference server like vLLM or Triton. It is a specialized tool. Another practical issue: you must trust the versioned Docker images. The latest release is v1.9.4 from September 2026, and the project is actively maintained, but you still need to track release notes for changes in model support or API behavior.
Operational Features: Tracing, Metrics, and Serverless Readiness
TEI includes production features that matter for observability. The README lists distributed tracing with Open Telemetry and Prometheus metrics. That means you can integrate TEI into an existing monitoring stack without building custom exporters. The small Docker images and fast boot times are explicitly aimed at serverless deployments. If you scale to zero and cold-start a container per request burst, TEI's lack of a graph compilation step becomes a real advantage. The token-based dynamic batching also helps in serverless settings because you cannot predict request sizes in advance.
Alternatives: vLLM and Sentence-Transformers
The most direct alternative is vLLM, which also serves transformer models with high throughput but is designed primarily for LLM generation, not embeddings. vLLM uses PagedAttention for KV cache management, which is irrelevant for embedding-only workloads. TEI skips that complexity and focuses on encoder models. Another alternative is the sentence-transformers library, which is Python-based and runs on PyTorch. It offers broad model support and easy integration with Hugging Face, but it lacks the dynamic batching and Rust-level optimizations. For a production API, sentence-transformers requires you to build your own batching and serving layer. TEI gives you a ready-made server with gRPC and REST endpoints. The trade-off is clear: sentence-transformers supports almost any model you can load, while TEI supports a curated list as a ready-made server.
Maintenance, Upgrades, and License
TEI is licensed under Apache-2.0, which permits commercial use, modification, and redistribution without copyleft obligations. The repository is active, with releases in 2026 (v1.9.2 in February, v1.9.3 in March, v1.9.4 in September). That cadence means you should plan for regular upgrades to get bug fixes and new model support. Read the release notes before upgrading. The project is written in Rust, which has a steep learning curve if you need to modify the source. But for most users, you interact only through Docker images or a local install. The main maintenance cost is keeping up with model architecture changes: if a new embedding model becomes popular, you have to wait for TEI to add support, which depends on the maintainers. That is a risk if your model choice is not in the supported list.
Editorial conclusion
Adopt TEI if you serve supported embedding models (BERT, Qwen3, GTE, etc.) at scale and need low latency with token-based dynamic batching. Do not adopt it if you require models outside the supported list, need custom pooling beyond the provided options. Before committing, verify that your exact model architecture is supported, check the version-specific release notes for breaking changes, and test the gRPC or REST endpoint against your expected batch size and sequence length. TEI is a focused, high-performance tool, not a general-purpose inference framework.
Frequently asked questions
What does text embeddings inference mean by a text embedding?
TEI is a toolkit for deploying and serving open source text embeddings and sequence classification models, covering FlagEmbedding, Ember, GTE and E5, with supported architectures from Nomic and BERT through MPNet, ModernBERT, Qwen3 and Gemma3.
Does ChatGPT use embeddings, according to text embeddings inference?
TEI's stated scope is open source text embeddings and sequence classification checkpoints, grouped by architecture and by position encoding, with BAAI/bge-base-en-v1.5 named as the model in the benchmark line of the header.
Can an llm serve as an embedding model in text embeddings inference?
The README's example table shows is that generative families do appear as embedding checkpoints: Qwen3-Embedding-8B and Qwen3-Embedding-4B, Alibaba-NLP/gte-Qwen2-7B-instruct, and Salesforce/SFR-Embedding-2_R under the Mistral type.
What does inference mean in text embeddings inference on Hugging Face?
In this repository it means serving an already trained open source model. The feature list names no model graph compilation step, token based dynamic batching, Safetensors and ONNX weight loading, Prometheus metrics and Open Telemetry distributed tracing, with API and gRPC sections reserved in the table of contents.
How does text embeddings inference compare with infinity?
For TEI's side of such a comparison, the project is built from Rust, six Dockerfiles including cuda, cuda-all, rocm, intel and arm64, an ort backend for ONNX weights, a python backend crate, and a proto directory beside a grpc-client crate.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/huggingface-text-embeddings-inference)Star history chart for your README
[](https://hysenlabs.com/projects/huggingface-text-embeddings-inference)Was this useful?