ONNX: the interchange format whose declared job is scoring, not training
Open standard for machine learning interoperability
At a glance
- What is it?
- ONNX defines an open computation graph format for AI models with built-in operators and standard data types, and the package around it makes choices a user inherits, from abi3 wheels that start at Python 3.12 to a reproducibility claim it explicitly refuses to make absolute.
- Who is it for?
- Use ONNX when your problem is getting a trained graph to run outside the framework that produced it, and you are willing to work inside the format's declared scope, which is scoring. Do not reach for it expecting the spec to cover training-time behavior, and do not treat its reproducible build section as a supply chain guarantee, because the project states the opposite.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
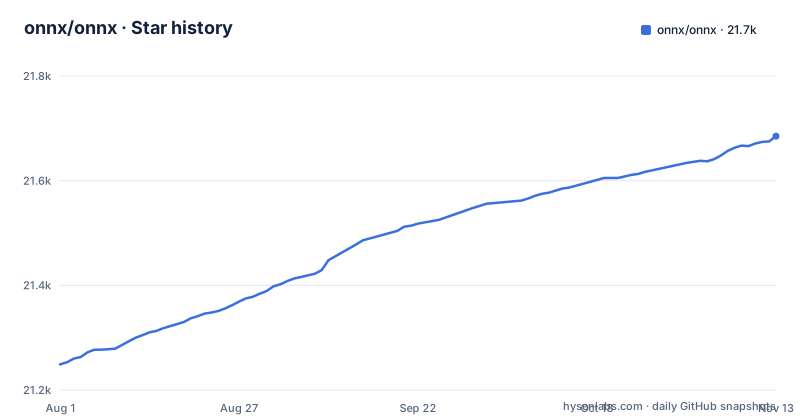
- onnx/onnx21,685 ★ · +436
| Repository | 2026-08-01 | 2026-11-13 |
|---|---|---|
| onnx/onnx | 21.2k | 21.7k |
436 Stars in the last 104 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
abi3 wheels start at cp312 while requires-python still says 3.10
The install line is short:
pip install onnx # or pip install onnx[reference] for optional reference implementation dependenciesUnderneath it sit two version statements that do not agree. The package metadata sets requires-python to >=3.11, and the build configuration sets wheel.py-api to cp312, while the compatibility note says the abi3 wheels let a single binary wheel work across multiple Python versions from 3.12 onwards. abi3 is what makes one wheel cover several interpreters, but only from that cp312 baseline, so the declared floor of 3.11 covers versions the published wheels do not serve. The consequence for a reader is that 3.11 is inside the declared support window but outside the wheel window, which turns a declared-supported install into a source build, and the build path needs CMake and a compiler rather than a wheel.
SOURCE_DATE_EPOCH is an aid to comparison, not a reproducibility promise
The reproducible build section sets SOURCE_DATE_EPOCH to the source commit timestamp in the build and release workflows, and then rules out the conclusion a reader might want. The text states plainly that SOURCE_DATE_EPOCH alone does not guarantee byte-for-byte identical artifacts across different environments. A reproducibility check has to use the same source revision, dependency versions, toolchain, target platform and build configuration before artifacts can be compared, and it says such a comparison complements release provenance attestations rather than replacing them. So the guarantee you get is the ability to diff two artifacts and learn whether they differ, not the guarantee that yours matches someone else's. The practical consequence is that if you are trying to verify a PyPI release against a local build, the timestamp normalisation only helps once you have already matched the revision, the protobuf and numpy floors, and the CMake configuration.
Three console entry points, two of which only check
The package installs three commands. check-model maps to onnx.bin.checker:check_model and check-node maps to onnx.bin.checker:check_node, so both do validation rather than execution: they check a model and they check a node. backend-test-tools maps to onnx.backend.test.cmd_tools:main and exists for backend test work. That split matters for how you read a pipeline failure: a model that fails check-model never reaches a runtime, so the format's own checker is the first gate, and a node-level complaint points at one operator rather than the whole graph. There is no entry point here for converting or running a model; the repository points that work at a separate optimizer repository and at the version converter API, so validation is what this package ships as a command line.
protobuf is pinned exactly at build time and ranged at run time
The build system requires scikit-build-core>=0.11 and protobuf==6.31.1 with no lower bound allowed, while the runtime dependencies list protobuf>=6.31.1, numpy>=1.26 and ml_dtypes>=0.5.4. The same file asks for CMake >=3.26, a Release build type, ONNX_BUILD_PYTHON set to ON and ONNX_INSTALL set to OFF, and it keeps a build directory called .setuptools-cmake-build for historical reasons even though the backend is scikit-build-core. Version is dynamic and read out of the VERSION_NUMBER file through a regex provider, so there is no version string to edit in pyproject.toml. Consequence for a builder: you cannot loosen the build-time protobuf pin without changing runtime expectations, and the wheel explicitly excludes proto3 files, markdown and CMakeLists.txt while the sdist include list is followed by an exclude of everything.
Scoring is the declared scope, so training behavior stays outside the spec
The format description is explicit about where it aims: an open source format for AI models, both deep learning and traditional ML, defining an extensible computation graph model, definitions of built-in operators and standard data types, and currently the capabilities needed for inferencing, in other words scoring. Training is not the stated target, which means a graph whose behavior only exists during training has no guarantee attached to it, and a model that needs an operator nobody has defined needs a spec change rather than a local workaround. The project routes that through a document for adding a new operator and through its Special Interest Groups and Working Groups, so the cost of an unsupported operator is a proposal and a review cycle. For a reader, the practical test is whether the model you hold already runs under an opset that lists every operator it uses, because that list is the boundary of what the format promises.
The operator index is linked twice, and one link is the latest release
Two entries in the learning list both carry the name Operators documentation, which is easy to skim past. One points into the branch at docs/Operators.md, the other points at onnx.ai/onnx/operators/index.html and is labelled latest release. That label is the part that matters: the published index reflects the newest released version, not the current main branch, so a reader checking whether an operator exists can be looking at a spec older than the source they are reading. The same pattern runs through the rest of the spec surface. Versioning principles live in docs/Versioning.md, the intermediate representation in docs/IR.md, shape and type inference in docs/ShapeInference.md, and graph optimization lives in a separate optimizer repository, so the reference material is split across the branch, the website and other repositories rather than in one reference manual.
The community page stops listing meetups at 2023.06.28
Governance is documented rather than assumed. The project describes itself as a community project with an open governance model, points contributors at Special Interest Groups and Working Groups, and says a roadmap process takes place every year with details in ROADMAP.md. Meeting schedules for the Steering Committee, working groups and SIGs live at onnx.ai/calendar. What the page does not reflect is current activity: the archive of community meetups ends at 2023.06.28, while the repository itself was last pushed on 2026-11-02 with releases v1.23.0 on 2026-09-18, v1.23.1 on 2026-09-29 and v1.23.2 on 2026-10-06. So the archive is not a signal you can use to judge the project, and the push date and release tags are. The README invites you to open Issues or use Slack for more real-time discussion.
Editorial conclusion
Use ONNX when your problem is getting a trained graph to run outside the framework that produced it, and you are willing to work inside the format's declared scope, which is scoring. Do not reach for it expecting the spec to cover training-time behavior, and do not treat its reproducible build section as a supply chain guarantee, because the project states the opposite. Before you commit, confirm your Python version clears the 3.12 floor that the published wheels target, pick pip install onnx or pip install onnx[reference] deliberately, since the reference extra pulls in Pillow, and read docs/Versioning.md plus the version converter API so your opset choice is a decision rather than a default.
Frequently asked questions
What is ONNX used for?
ONNX provides an open source format for AI models, both deep learning and traditional ML, together with an extensible computation graph model, definitions of built-in operators and standard data types. The stated purpose is interoperability between frameworks and a shorter path from research to production, with the focus on the capabilities needed for inferencing, that is scoring.
Is ONNX still used?
The repository's last push is 2026-11-02 and recent releases are v1.23.0 on 2026-09-18, v1.23.1 on 2026-09-29 and v1.23.2 on 2026-10-06. The project also says ONNX is widely supported and can be found in many frameworks, tools and hardware, and points to pre-trained ONNX models published on the Hugging Face onnx-community organization.
Is ONNX free to use?
Yes. The repository is under Apache License v2.0, and the released packages are published on PyPI and installed with `pip install onnx`. A separate onnx-weekly package is published on PyPI to enable experimentation and early testing.
why use onnx
The two reasons the project gives are enabling interoperability between different frameworks and streamlining the path from research to production. For testing, the project uses pytest as its test driver, and detailed build options and common errors are documented separately in INSTALL.md.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/onnx-onnx)Star history chart for your README
[](https://hysenlabs.com/projects/onnx-onnx)Was this useful?