simonw/llm: four ways to install one CLI, and a plugin boundary around every model
Access large language models from the command-line
At a glance
- What is it?
- The llm package is a command-line tool and Python library for OpenAI, Claude, Gemini and local models, but most of its surface arrives through plugins, key stores and per-endpoint flags rather than through the package itself. It is at version 0.37 and the last push landed on 2026-10-30.
- Who is it for?
- Adopt llm if you want one prompt syntax across hosted APIs and a local server, and expect to install a plugin before Gemini, Claude or Ollama models work. Keep it in an isolated environment through pipx or uv rather than pip, since its runtime dependencies include pip and setuptools.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
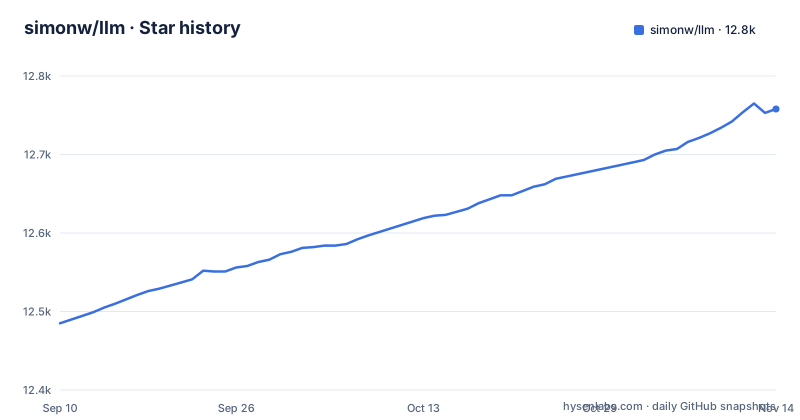
- simonw/llm12,758 ★ · +273
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| simonw/llm | 12.5k | 12.8k |
273 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four installers, four different dependency footprints
The same package is reachable four ways, and the choice changes what lands on your machine.
pip install llmbrew install llmpipx install llmuv tool install llmThe pip route pulls the declared runtime dependencies into whatever environment you are in: click, httpx2, condense-json, openai, click-default-group, sqlite-utils, pydantic, typing-extensions, PyYAML, pluggy, python-ulid, setuptools, pip and puremagic, plus pyreadline3 on Windows. Having pip and setuptools listed as runtime requirements is unusual, and it means a plain pip install pulls those into whatever environment you install into. pipx and uv tool install both give the tool its own environment and expose one binary on your path, which is the cheaper option when the same machine also runs other Python tools.
The Homebrew path is the odd one out: the documentation links a warning note next to the brew install line, which tells you the formula has a caveat worth reading before you use it. The package requires Python 3.11 or newer, and the classifiers list 3.11 through 3.15, so anything older is unsupported. The README also links the Homebrew formula page at formulae.brew.sh/formula/llm.
The endpoint command skips the key store and repeats itself every call
Any server that speaks the OpenAI Chat Completions protocol can be driven without configuring anything, which is how you reach a local model server such as LM Studio:
uvx llm openai endpoint http://localhost:1234/v1 \
  -m google/gemma-4-12b \
  "What is the capital of France?"

uvx llm openai endpoint http://localhost:1234/v1 \
  -m google/gemma-4-12b \
  --chat
`uvx` runs the tool straight from the package index, so this works before anything is installed. `--chat` switches the same endpoint from a one-shot prompt to an interactive session.
What this path does not give you is persistence. The URL, the port and the model name are arguments, not stored settings, so every invocation in these examples repeats them. If the endpoint needs authentication you add `--key your-api-key`, and that puts a secret directly on the command line where shell history and process listings can keep it. The README points to its "Run against an endpoint without configuring it" documentation page for more options.
Claude, Gemini and local models all arrive as separate installs
The package itself talks to OpenAI and to OpenAI-compatible endpoints. Gemini, Anthropic and Ollama models come through plugins (pluggy is a runtime dependency), which is why the quick start for Anthropic begins by installing something:
llm install llm-gemini
llm keys set gemini
# Paste Gemini API key here
llm -m gemini-3.5-flash 'Tell me fun facts about Mountain View'

llm install llm-anthropic
llm keys set anthropic
# Paste Anthropic API key here
llm -m claude-sonnet-5 'Impress me with wild facts about turnips'
Local models go the same way, on top of a separate download step:
# Install the plugin
llm install llm-ollama

# Download and run a prompt against the Orca Mini 7B model
ollama pull llama3.2:latest
llm -m llama3.2:latest 'What is the capital of France?'
The consequence is that a fresh install cannot talk to Claude, Gemini or an Ollama model until the matching plugin is present, and a model name that looks supported may simply be unknown until its plugin exists. Plugin versions are not tied to the llm version: 0.37 is the package, and llm-gemini or llm-ollama can move independently. If a model call breaks after a plugin upgrade, the package release notes are not where the answer is. The plugin pages live under the plugins/installing-plugins.html section of llm.datasette.io, separate from the usage pages.
llm keys set prompts for a secret and says nothing about where it lands
Credentials enter through an interactive prompt rather than a command line argument:
# Paste your OpenAI API key into this
llm keys set openai

# Run a prompt (with the default gpt-6-luna model)
llm "Ten fun names for a pet pelican"

# Extract text from an image
llm "extract text" -a scanned-document.jpg

# Use a system prompt against a file
cat myfile.py | llm -s "Explain this code"
`llm keys set openai`, `llm keys set gemini` and `llm keys set anthropic` are the only credential commands shown, and each one blocks on a paste. The docs cover usage, logging, embeddings, schemas and tools in separate pages, and the README's contents list links a Setup page; check it for where keys are stored before writing automation around them.
Note that the default model is gpt-6-luna and the key command above is the only setup needed for that path, which makes it the simplest provider to start with.
llm chat is a REPL with four escape prefixes and no documented file input
Interactive mode is a line oriented session with a small fixed vocabulary:
llm chat -m gpt-4.1Inside it, `exit` or `quit` leaves, `!multi` opens a multi-line block closed by `!end`, `!edit` opens your default editor so you can revise the prompt before it is sent, and `!fragment <my_fragment> [<another_fragment> ...]` splices stored text into the prompt. Fragments are the mechanism behind long context work, which arrived in release 0.24 together with template plugins, and they are also how you avoid retyping a long instruction block.
The gap is input. One-shot mode documents images with `-a scanned-document.jpg`, files through a pipe as in `cat myfile.py | llm -s "Explain this code"`, and video as a sequence of JPEG frames from release 0.25, but the chat commands shown in the README do not include any of that. Check the interactive chat documentation page before planning a chat-first workflow over files or images.
The README is a build artifact, so hand edits to it are lost
README.md is not authored. It is produced from docs/index.md by a cog block that runs sphinx-build and pipes the markdown back in, and the tooling that does it is pinned in the dev dependency group at sphinx==7.2.6 and sphinx-markdown-builder==0.6.8, with cogapp in the same group. The top level directory confirms the shape of the project: docs/, llm/, tests/, a Justfile, pytest.ini, ruff.toml, mypy.ini, AGENTS.md, .github/ and MANIFEST.in.
Two things follow for anyone who wants to change the documentation. First, edits belong in docs/index.md, and an edit made directly in README.md disappears the next time the generator runs, which is a confusing way to lose work if you did not know the file was generated. Second, the published documentation and the README are the same content at different addresses, llm.datasette.io with an /en/stable/ prefix for each page, so a bug in the doc build shows up twice.
For a reader, the practical check is that documentation URLs ending in en/stable/ describe the stable line, while the changelog lives at a separate changelog.html address. Contributors who want to confirm their change landed should look at the rendered site, not at the file in the repository.
Three releases in three weeks, and dependency floors with no ceilings
The version history is dense at the front. Release 0.35 shipped on 2026-09-07, 0.36 on 2026-09-22 and 0.37 on 2026-11-02, and the version string in pyproject.toml reads 0.37. The last push to the repository was on 2026-10-30. The project is not archived.
What that cadence costs you is dependency drift. The runtime requirements are floors with no upper bounds: openai>3, condense-json>=1.1, click-default-group>=1.2.3, sqlite-utils>=4.0 and pydantic>=2.0.0, with click, httpx2, pluggy, PyYAML and python-ulid listed plain. A future major of openai or click can land inside your environment without the package pinning you out of it, and if llm breaks, the fix is not necessarily a new llm release. The dev group shows the shape of the test surface instead, with pytest-recording and syrupy for recorded fixtures, llm-echo==0.3a3 as the echo server the tests run against, and black and ruff for linting.
Two further cautions. Release 0.32a0 was a major backwards compatible refactor, so alpha versions appear in this project's history and can carry more churn than the version number suggests. And the feature set has moved fast since the first announcement in April 2023: embeddings tools, llm chat and llm-clip in September 2023, multimodal images, audio and video in October 2024, schemas in February 2025, fragments and template plugins in April 2025, terminal tool execution in 0.26, and GPT-5 support in 0.27. Documentation written for an older point release will describe a smaller tool than the one you have.
Editorial conclusion
Adopt llm if you want one prompt syntax across hosted APIs and a local server, and expect to install a plugin before Gemini, Claude or Ollama models work. Keep it in an isolated environment through pipx or uv rather than pip, since its runtime dependencies include pip and setuptools. Before you commit, check which plugin versions your models need, confirm your Python is 3.11 or newer, and decide where API keys will live, and check the setup documentation for where llm keys set stores them.
Frequently asked questions
What are the top 5 LLM models?
The llm project does not rank models or publish a comparison. It exposes them by name: gpt-6-luna is the default after llm keys set openai, and the examples also name gpt-4.1, claude-sonnet-5, gemini-3.5-flash, llama3.2:latest and google/gemma-4-12b served from a local endpoint.
Is there a library for LLMs in Python?
Yes. llm is both a CLI tool and a Python library, requiring Python 3.11 or newer and reaching OpenAI directly plus Anthropic, Gemini, Ollama and other providers through plugins installed with llm install. It is a client, not an inference engine, so remote API calls cost money and local models depend on a server you run yourself.
What is Simon Willison known for?
The package metadata in pyproject.toml lists Simon Willison as the sole author of llm, and the project points readers to his blog for annotated release notes. A May 2023 post on that blog covered llm alongside the ttok and strip-tags command line tools.
What is Simon software?
Around this project, the related tools named in the documentation are llm, ttok and strip-tags from the May 2023 announcement, plus separate plugins such as llm-ollama, llm-gemini and llm-anthropic. Community discussion goes through the Discord linked as datasette.io/discord-llm, and this repository does not enumerate other software.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/simonw-llm)Star history chart for your README
[](https://hysenlabs.com/projects/simonw-llm)Was this useful?