LTX-2: A 22B audio-video DiT with a two-tier pipeline and a 66 GiB download
Official Python inference and LoRA trainer package for the LTX-2 audio–video generative model.
At a glance
- What is it?
- Lightricks' LTX-2 package offers a distilled transformer for fast generation and a DFR path for production quality, but the real cost is in VRAM, disk space, and gated Hugging Face downloads.
- Who is it for?
- Adopt LTX-2 if you need a single model that outputs synchronized audio and video and you can afford a 66 GiB download plus a GPU that handles a 22B transformer, even with fp8 and offloading. Do not adopt it if you need a lightweight model or a simple text-to-video tool without audio, because the gated Hugging Face download and the multi-component download add friction.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
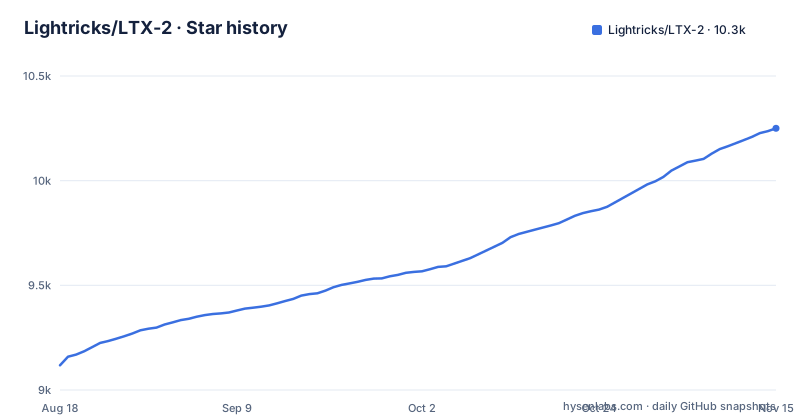
- Lightricks/LTX-210,250 ★ · +1,132
| Repository | 2026-08-18 | 2026-11-15 |
|---|---|---|
| Lightricks/LTX-2 | 9.1k | 10.3k |
1,132 Stars in the last 89 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What LTX-2 actually is
LTX-2 is a Python package from Lightricks that provides inference and LoRA training for a diffusion transformer (DiT) that generates audio and video together. The README calls it "the first DiT-based audio-video foundation model" that includes synchronized audio, video, high fidelity, multiple performance modes, and open access. The package is not a single script; it is a set of pipelines, each targeting a different use case. The two main ones are DistilledPipeline, which is the fast starting point, and DFR (Diffusion Fidelity Rendering), which is the production-quality path. The target user is someone who needs to generate video with matching audio from text or images, and who is willing to manage a large model download and a CUDA-capable GPU. The package is written in Python and uses uv for dependency management, which is a modern choice but assumes familiarity with that tool.
The two-tier pipeline design
The core architectural choice is a split between a distilled transformer and a full dev transformer. The distilled model runs in "far fewer steps" and is what DistilledPipeline, DFRPipeline, ICLoraPipeline, and DubItPipeline expect. The dev transformer is only used by the guided two-stage pipelines: TI2Vid, Keyframe, and A2Vid. This split means you must choose which transformer to download before you run anything. The README warns not to pass the full dev transformer to the DFR pipeline. The DFR path reuses the same distilled transformer but adds a detailing IC-LoRA, which generates extra keyframes and a spatial detailing pass. The result is longer runtime and more VRAM, but the README claims it is production quality. This design gives you a fast mode and a quality mode without needing two separate model families, which is practical but also means the fast mode is a compromise, not a separate lightweight model.
How the data flows through the model
The generation pipeline takes a text prompt, passes it through a Gemma 4 12B text encoder that has been fine-tuned for LTX, and then feeds the resulting embeddings into the transformer. The transformer produces latent representations for both video and audio. Two separate VAEs decode these latents: one for video and one for audio. A spatial upscaler model then increases the resolution. The README lists the exact files needed: a transformer, a text encoder, a video VAE, an audio VAE, and a latent spatial upscaler. The video VAE is a diffusion decoder, called NADiffusionDecoder, which improves quality but takes longer to decode and uses more VRAM. The audio VAE is separate, which is unusual and reflects the model's focus on synchronized audio. The text encoder is not optional; every pipeline requires it, and the README explicitly states that Google's stock Gemma 4 is not a substitute because the encoder version is checked against the checkpoint's training version.
Getting it running: commands and config
The quick start uses uv, not pip. You clone the repo, run `uv sync --extra natten`, and then download models with the Hugging Face CLI. The download command is long because it pulls five separate files into a local directory that mirrors the Hugging Face repository layout. The README warns that this is roughly 66 GiB. After that, you run the distilled pipeline with a command that passes each file path as a flag, for example `--transformer-path`, `--text-encoder-path`, and so on. A notable detail is the `--num-frames 121` flag, which sets the number of frames. For GPU memory constraints, the README suggests `--quantization fp8-cast --offload {cpu, disk}`. The DFR pipeline has its own module, `ltx_pipelines.dfr_pipeline`, and requires an additional LoRA download from a separate repository. The defaults for DFR are 1024x1536 at 24 fps, and UHD 4K is `--width 3840 --height 2176`, not 2160, which is a specific quirk. The README links further documentation for additional flags and pipeline details.
The real cost: disk, VRAM, and the natten backend
The 66 GiB download is just the start. The model is 22B parameters in bf16, which means the transformer alone is around 44 GB in memory. The README suggests fp8 quantization and offloading to CPU or disk for memory constraints, but that will slow generation. The video VAE is a diffusion decoder, which adds decode time and VRAM. The `natten` extra is the fastest backend for the diffusion VAE, but it is Linux and CUDA only. On Windows and macOS, the package automatically falls back to a Triton or eager implementation. That fallback is a practical concession, but it means performance varies wildly by platform. The text encoder is also 12B parameters, so the total memory footprint is substantial. If you are on a laptop or a single consumer GPU, this model is likely out of reach without aggressive offloading, which will make generation painfully slow.
A genuine limitation: gated access and version checks
The README includes a troubleshooting note: if you get a 401/403, you must accept the model terms on Hugging Face and log in with a Read token that has the "read gated repos" scope enabled. This means the model is gated, not fully open. The license field in the repository is NOASSERTION, which means you cannot assume it is open source. The text encoder version check adds another constraint: if you try to use a different Gemma 4 checkpoint, the pipeline will reject it. This is a deliberate lock-in to the LTX-tuned encoder. For a package that claims "open access," the gating and version checks are a real friction point. You cannot just download the weights and run; you must have a Hugging Face account, accept terms, and use the exact files. This is a limitation if you are in an environment where external downloads are restricted or where you need to audit the model weights.
The alternative: a different approach to audio-video generation
The obvious alternative is to use a separate video generation model and a separate audio generation model, then synchronize them in post-production. For example, you could use a text-to-video model like Stable Video Diffusion and a text-to-audio model like AudioLDM, and then align the audio track to the video frames with a tool like FFmpeg. The difference in approach is fundamental: LTX-2 generates audio and video jointly in a single DiT, which means the audio is inherently synchronized to the video content. With separate models, you must handle synchronization yourself, and the audio may not match the visual events. However, separate models are often smaller and easier to run on consumer hardware. The trade-off is quality of synchronization versus resource requirements. If you already have a pipeline for separate generation, LTX-2 is a heavier but more integrated option.
Maintenance and upgrade cost
The repository has active development, with releases v1.4.1 (2026-09-30), v1.4.2 (2026-10-02) and v1.5.0 (2026-10-18), and the last push is the same day as the v1.5.0 release. This suggests a fast-moving project, which means you should expect frequent changes to the CLI flags and pipeline modules. The README references documentation files under `packages/ltx-pipelines/docs/`, which you read in the cloned repository. The package is structured as a monorepo with a `packages/` directory, which is a sign that the code is modular but also that upgrading might require updating multiple packages. The license is NOASSERTION, which is not a standard open source license. That means you cannot assume you have the right to modify and redistribute the code or the model weights. Before adopting this in a commercial product, you should contact Lightricks or check the Hugging Face model card for explicit terms. The version check on the text encoder is also a maintenance burden: if you upgrade the model, you must ensure the encoder matches.
Editorial conclusion
Adopt LTX-2 if you need a single model that outputs synchronized audio and video and you can afford a 66 GiB download plus a GPU that handles a 22B transformer, even with fp8 and offloading. Do not adopt it if you need a lightweight model or a simple text-to-video tool without audio, because the gated Hugging Face download and the multi-component download add friction. Before committing, verify that your GPU has enough VRAM for the distilled pipeline at your target resolution, and check the Hugging Face terms for the LTX-2.5 repository, as the 401/403 note indicates gated access.
Frequently asked questions
Is LTX-2 open source?
The README lists open access among the model's capabilities, and this repository is the official Python inference and LoRA trainer package. The root holds LICENSE, LICENSE-2 and LICENSE-2_x, so check the file that matches your use.
Is LTX-2 free?
Running it locally needs a CUDA GPU and about 66 GiB of disk for the weights, and those weights are gated: accept the model terms on Hugging Face and authenticate with a Read token, enabling the read gated repos scope on a fine-grained token.
how to install ltx 2
Clone the repository, then run `uv sync --extra natten`. The natten extra is the fastest backend for the diffusion video VAE and is Linux plus CUDA only, so it is skipped on Windows and macOS and decoding falls back to Triton or eager there.
how to use ltx 2 locally
Download the LTX-2.5 components with the Hugging Face CLI into a `--local-dir` that mirrors the repository layout, then run `uv run python -m ltx_pipelines.distilled` with the transformer, text encoder, both VAE and spatial upsampler paths. Under GPU memory pressure, add `--quantization fp8-cast --offload {cpu, disk}`.
how to use ltx 2.5
LTX-2.5 is the recommended model and the one the Quick Start uses. Its weights are published as one file per component, so you download only what a pipeline needs: the distilled or dev transformer, the Gemma 4 12B text encoder with projection, a video VAE, an audio VAE, and the upscalers for the resolution and frame rate you intend to run.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/lightricks-ltx-2)Star history chart for your README
[](https://hysenlabs.com/projects/lightricks-ltx-2)Was this useful?