interview-guide: a Chinese-language readme, an empty architecture section, and a compose stack whose defaults are a lesson
An open-source AI interview platform built with Spring Boot 4.1, Java 25, Spring AI 2.0, React, PostgreSQL/pgvector, Redis and RustFS, supporting smart resume analysis, mock interviews, voice interviews and knowledge-base RAG.
At a glance
- What is it?
- This is a self-hosted interview assistance platform in Java and React: it analyses résumés, runs mock interviews by text and voice, parses interview invitations into a calendar, and answers questions against a document knowledge base. The code is promised free and the guided tutorial is sold. The deployment files ship with a database password spelled out, an unauthenticated cache, and an object store whose access key and secret are the same word, and the compose file comments explain each choice as course material.
- Who is it for?
- Read it as a teaching project rather than a product, because that is how its own files present it: the compose comments explain each service as a lesson, and the readme asks contributors to read it first. Three things to settle before running it.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 37 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
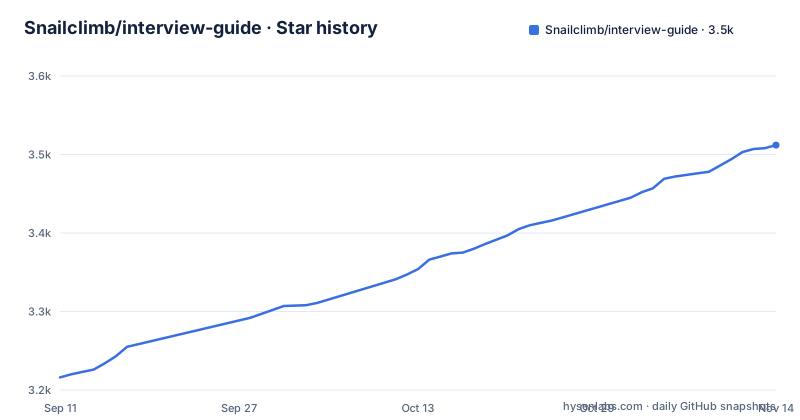
- Snailclimb/interview-guide3,512 ★ · +296
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| Snailclimb/interview-guide | 3.2k | 3.5k |
296 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The architecture section is a heading with nothing under it
The README in this repository is written in Chinese, and one of its sections is empty.
There is a heading for system architecture, and immediately after it comes the heading for the companion tutorial. Nothing sits between them. So the document that introduces the project, lists two tables of pinned dependency versions, and then promises a free and complete open-source implementation, skips the one section a reader would most want, which is what the thing actually looks like.
There is a project structure section further down, and it is a directory tree rather than a diagram. It starts at the backend application directory, into the main Java source root, to the main class and a shared foundation package that contains subpackages for provider integration and structured output, a repeatable rate-limiting annotation, an aspect and a script-based rate limiter, asynchronous producer and consumer templates, configuration, and a unified evaluation engine shared by the text and voice paths. The tree stops partway through that last entry, mid-word.
So the structural information exists twice in the repository, once as an empty heading and once as a partial listing, and neither is complete.
The code is promised free, the guided tutorial is sold
The tutorial section opens with a promise, stated in bold: this project commits to being completely free and open source, and will not make a Pro version or paywall the core functionality.
Two paragraphs later, the same section offers a paid version of that tutorial, with a link, an explicit note that the tutorial is paid content, and a parenthetical explaining that the aim is to cover the time cost.
Both statements can be true at once. The setup the readme asks for is short:
git clone https://github.com/Snailclimb/interview-guide.git
cd interview-guide
followed by copying the sample environment file and filling in one provider key. The code stays free; the guided walkthrough is a separate product covering everything from standing up infrastructure through to the core implementation and how to describe the work in an interview. The author is selling teaching time, not access to features.
It is worth naming anyway, because a reader who arrives at the repository from the project page rather than the readme could see a link to paid material and a paywalled-feature claim before ever finding the pledge not to paywall the code. The pledge is two paragraphs further down than the link.
Every backend version is pinned, and the front end is deliberately behind
The two stack tables are the most precise thing in the readme, and putting them side by side says a lot.
The backend pins thirteen things to exact versions: the application framework, the language at 25 using virtual threads, the AI integration framework, an agent utility library, the relational database with a vector extension at 14 and newer, the cache and its client library, a document parser, a PDF library, an object mapper, an API documentation library, a speech recognition and synthesis SDK, an object storage SDK, and the build tool at 9.6.1.
The front end pins twelve, and they are a different generation: React at 18.3, TypeScript 5.6, the build tool at 5.4, the utility CSS framework at 4.1, the router at 7.11, an animation library, a charting library, an icon library, a calendar component, a virtual list library for the retrieval chat, and the package manager at 10.26.
So the back end is on the newest of everything and the front end is two major versions behind on its framework. That is not sloppiness: the retrieval chat is the part that has to survive long documents, and the virtual list is the reason the front end can.
The compose file is written as course material
The container definitions are the unusual part of this repository, and it is worth reading how they are commented.
Each service has a numbered banner, a purpose section, a tutorial-knowledge-points section, and a health-check section. The database section explains that the vector-enabled image was chosen instead of the standard database image specifically to get vector search, and adds that a vector store is core infrastructure for this kind of application. The cache section explains that a stream implementation is a reasonable substitute for a full message broker with lower operational cost, and the rationale section above the tables says the same thing again about not wanting too many components.
The reason is given twice, consistently, across two of the three questions in that rationale section: the database and vector store in one engine, and a cache rather than a broker, both to keep the number of moving parts small.
The consequence is that the compose file reads as documentation that happens to be executable. Anyone who wants to understand the architecture should read the comments before the code, because the comments carry the argument and the code only carries the wiring.
The shipped defaults are a database password, an open cache, and a symmetric key
Three credentials are visible in the shipped files, and all three are placeholders that work.
The database service creates a superuser named postgres with the password defaulting to the word password, and the sample environment file sets the same value explicitly, with a comment reminding you that this is what the compose file defaults to. The port is published to the host.
The cache service has no password at all. Its health check is a bare ping command with no credentials, and the port is published.
The object store is configured in the development compose file rather than the main one, and its sample credentials are the access key and the secret key set to the same literal string.
None of this is unusual for a development stack that is meant to be started with one command, and the environment file says so at the top. It does mean the stack is not safe to expose as it stands, which is a one-line change per service and an easy thing to miss.
The key that protects stored provider credentials must never change
One value in the sample environment file carries a warning that is easy to skim past, because it is written as a comment above a line that looks like every other placeholder.
The value is the encryption key for provider API keys, and the comment says it is required, that production should replace it with a random long string, and that it must be kept unchanged after deployment.
That last clause is the operationally important one. The settings module writes runtime configuration into a directory in the user's home and encrypts the API keys it stores there, which means this key is not just an input to the application but the only thing standing between an encrypted provider credential and whoever reads that file. Rotating it later does not rotate the credentials; it makes every previously stored one unreadable.
It is also the one configuration item that cannot be fixed after the fact. A leaked database password can be changed; a changed encryption key with existing stored keys cannot be changed back.
The two unticked checklist items are exactly the two admitted voice problems
The voice interview module is the only section of the readme with a known-issues block, and it names four problems: end-to-end latency is high because the audio is relayed through the server, echo leaks in without headphones, the synthesised voice offers a single timbre, and audio breaks up on weak networks.
It also names the plans: exploring WebRTC, client-side voice detection with noise reduction, and end-to-end voice models.
Then the task list at the bottom of the readme has nineteen ticked items and exactly two unticked, and they are the voice module's WebRTC work and the voice module's additional voice options.
So the two lists agree exactly, which is a good sign for a project this size. It also means the voice path is the part still in motion, while everything else on the list, from the unified evaluation engine shared by text and voice to rate limiting, to the knowledge base question bank with its capacity validation, is marked done.
Editorial conclusion
Read it as a teaching project rather than a product, because that is how its own files present it: the compose comments explain each service as a lesson, and the readme asks contributors to read it first. Three things to settle before running it. The database password, the cache and the object store credentials are all defaulted in the shipped files, so change them before anything is reachable. The sample environment file's key for encrypting stored provider credentials ships as a placeholder and must not change after first deployment. And the one feature area with admitted problems is voice: two checklist items remain unticked and they are exactly the two the voice section flags.
Frequently asked questions
what is interview guide
In this repository it is a self-hosted interview assistance platform. It analyses uploaded résumés with a language model, runs mock interviews by text and by voice, parses interview invitations into a calendar, and answers questions against a document knowledge base using vector retrieval. The back end is Java on a Spring framework with PostgreSQL and a vector extension, Redis for caching and asynchronous work, and the front end is React.
how to set up an interview guide
For this platform the setup is a clone, a copy of the sample environment file, one required API key for the text, speech recognition and speech synthesis provider, and a container stack providing the database, the cache and object storage. Without containers you install those three services yourself: PostgreSQL 14 or newer with the vector extension, Redis 6 or newer, and any S3-compatible store.
What does interview guide need to run?
A JDK 25 and Node.js 18 or newer are required, with the package manager and Docker recommended. The running services are PostgreSQL 14 or newer including the vector extension, Redis 6 or newer, and an S3-compatible object store. The repository ships a sample environment file naming the provider credentials the application expects, including one required key for the default model and speech provider.
questionnaire vs interview guide
That is a research methodology distinction and nothing here addresses it. What the platform produces is a structured interview record: per-question evaluations, a total score, strengths and suggested improvements, generated asynchronously by the evaluation engine that the text and voice interview paths share, with the report exportable as a PDF.
interview guide vs schedule
Nothing in the repository draws that distinction. What exists is a scheduling module alongside the interview modules: it parses invitations from three meeting formats using both rules and a language model, extracts the company, role, time and meeting link, and offers day, week and month calendar views with drag adjustment, automatic expiry of past invitations, and configurable reminders.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/snailclimb-interview-guide)Star history chart for your README
[](https://hysenlabs.com/projects/snailclimb-interview-guide)Was this useful?