llm-d: A Kubernetes-Native Inference Stack for Accelerator-Aware LLM Serving
Achieve state of the art inference performance with modern accelerators on Kubernetes
At a glance
- What is it?
- llm-d is a CNCF sandbox project that layers intelligent routing, KV-cache management, and disaggregation on top of model servers like vLLM and SGLang. It targets production Kubernetes deployments where raw model server performance is not enough.
- Who is it for?
- Adopt llm-d if you run production LLM serving on Kubernetes and need prefix-cache-aware routing, tiered KV offloading, or prefill/decode disaggregation across multiple accelerators. It is a poor fit for single-node experiments or teams without Kubernetes operational maturity.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Shell, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
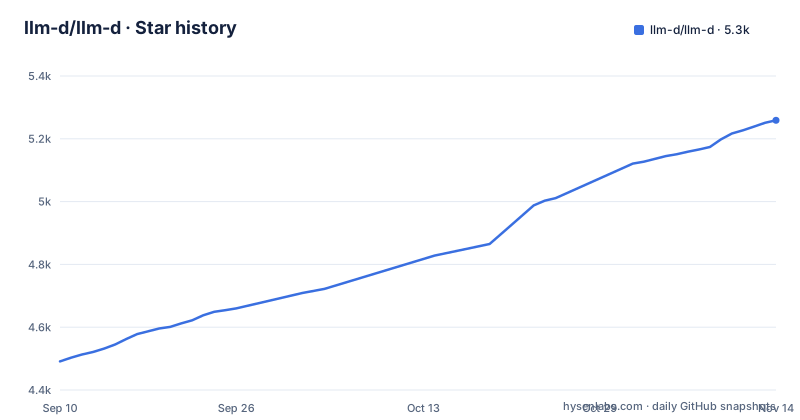
Star history
- llm-d/llm-d5,259 ★ · +768
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| llm-d/llm-d | 4.5k | 5.3k |
768 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What llm-d Actually Does
llm-d is not another model server. It sits above vLLM and SGLang, which handle the low-level execution of transformer layers on accelerators. The project's own description says it provides orchestration and optimizations above those servers. That distinction matters. If you already run vLLM on Kubernetes and hit scaling or latency problems under multi-tenant traffic, llm-d is aimed at you. The target user is a platform team running production inference at scale, not a researcher spinning up a single GPU. The project is a CNCF sandbox, founded by Red Hat, Google Cloud, IBM Research, CoreWeave, and NVIDIA. That backing explains the focus on multi-cloud portability and the emphasis on reproducible benchmark workflows rather than just raw kernel tricks.
Four Themes, One Architecture
The README organizes llm-d into six themes: intelligent routing, advanced KV-cache management, serving large models, agent-aware serving, operational excellence, and batch processing. Intelligent routing is the load balancer layer. It uses prefix-cache awareness to send requests with shared prefixes to the same replica, and it can also balance based on predicted latency. The README describes that predicted latency-based scheduling as experimental. KV-cache management extends the effective working set by offloading cache to CPU or disk, with a global index that tracks cache state across replicas. Serving large models relies on prefill/decode disaggregation and wide expert parallelism, which split the prefill and decode phases onto different hardware. Operational excellence covers priority- and fairness-aware flow control for multi-tenant workloads, zero-downtime operations, SLO-aware autoscaling and end-to-end observability. These themes are not independent. Routing decisions depend on cache state, and disaggregation changes how routing must work.
Getting Started: Helm Charts and Well-Lit Paths
The quickstart guide is the entry point. The README says most users begin with the Optimized Baseline, and the well-lit path guides provide benchmarked recipes and Helm charts. You will need a Kubernetes cluster with accelerator nodes and a model you want to serve. The actual commands are not in the README, but the quickstart link provides them. The documentation stresses that these are benchmarked recipes, not just sample YAML. That is a strong point: you get a known-good starting configuration rather than a blank canvas.
The Performance Claims: Read the Footnotes
The README lists several performance highlights, all sourced from partner blogs or llm-d's own blog. For example, a 3x output throughput gain with prefix-cache-aware routing versus round-robin on Llama 3.1 70B with 4 AMD MI300X. A 40% reduction in TTFT and ITL with predicted-latency scheduling on NVIDIA GPUs. A 13.9x throughput improvement with hierarchical KV offloading at 250 concurrent users on 4 H100s. These are impressive numbers, but they come from controlled tests on specific hardware and model sizes. The 50k tokens/sec claim for wide expert parallelism uses a 16x16 B200 topology, which is far beyond what most teams have. The project does point to Prism, a benchmark platform, for reproducible results. That is a good sign. However, you should not assume those gains transfer to your workload. The README itself says the numbers are validated from production deployments and partner benchmarks, not from an independent body.
Where llm-d Falls Short
The most obvious limitation is complexity. This is not a tool you install and forget. It requires understanding prefix caches, disaggregation, and autoscaling signals. For a single model with low traffic, the overhead of the router and cache manager may exceed the benefit. The README's large-model theme relies on fast accelerator interconnects. If your cluster uses commodity networking, wide expert parallelism will not work well. Another gap: the project depends on vLLM and SGLang, so you inherit their limitations. If your model is not supported by those servers, llm-d cannot help. Finally, the documentation is extensive but spread across the website, and the README is more of a marketing page than a technical reference. You must visit the docs to learn the actual config keys.
Alternatives: Rolling Your Own vs. Managed Services
The most direct alternative is to use vLLM or SGLang directly with Kubernetes and write your own routing and autoscaling. That is what llm-d replaces. The difference is that vLLM gives you a model server with a built-in scheduler, but it does not provide cluster-level prefix-cache awareness across replicas. You would need a separate load balancer that understands KV cache state. llm-d provides that router out of the box. Another alternative is a managed inference platform like those from cloud providers, which abstract away Kubernetes entirely. Those services handle scaling and routing but lock you into one vendor and often do not expose the same level of control over disaggregation. llm-d sits in between: it gives you the control of self-hosting with some of the convenience of a managed service, but you still operate the Kubernetes cluster. The choice depends on whether you have the team to run infrastructure.
Maintenance and License Considerations
llm-d is licensed under Apache-2.0, which permits commercial use, modification, and redistribution without copyleft obligations. That is a permissive license, so you can integrate it into proprietary products. The project is active, with releases v0.9.0 in August 2026, v0.10.0 on 2026-09-29 and v1.0.0 on 2026-10-20. You should budget time to track upstream changes, especially if you customize the Helm charts. Check the FOSSA status link if you need detailed dependency license analysis.
Editorial conclusion
Adopt llm-d if you run production LLM serving on Kubernetes and need prefix-cache-aware routing, tiered KV offloading, or prefill/decode disaggregation across multiple accelerators. It is a poor fit for single-node experiments or teams without Kubernetes operational maturity. Before committing, verify that your model server version (vLLM or SGLang) matches the tested recipes, confirm your accelerator interconnect supports the required communication patterns, and reproduce the cited benchmarks on your own hardware, as the performance claims come from partner blogs, not independent tests.
Frequently asked questions
What is llm-d?
llm-d is a high-performance distributed inference serving stack for production deployments on Kubernetes. Model servers such as vLLM and SGLang run the models, and llm-d supplies the orchestration and optimisations above them: intelligent routing, tiered KV cache management, prefill and decode disaggregation, multi-tenant flow control, SLO-aware autoscaling and batch APIs.
What is the difference between vLLM and llm-d?
The division of labour is explicit: model servers like vLLM and SGLang handle running large language models efficiently on accelerators, while llm-d provides orchestration and optimisations above model servers to serve high-scale real-world traffic. So llm-d is a layer deployed alongside a model server rather than a replacement for one.
Is llm-d open source?
It is an Apache-2.0 licensed repository and a Cloud Native Computing Foundation sandbox project, founded by Red Hat, Google Cloud, IBM Research, CoreWeave and NVIDIA.
What does llm-d provide for a production vLLM stack?
Well-lit path guides with benchmarked recipes and Helm charts, and the README says most users begin with the Optimized Baseline. Alongside that it lists priority- and fairness-aware flow control for multi-tenant quality of service, SLO-aware autoscaling, and OpenAI-compatible Batch APIs for large-scale offline inference.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- LLM-d v1.0.0 is outHacker News · Oct 23, 2026 · 2 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/llm-d-llm-d)Star history chart for your README
[](https://hysenlabs.com/projects/llm-d-llm-d)Was this useful?