AxonHub: A Go-Based AI Gateway That Swaps Providers Without Touching Your SDK
⚡️ Open-source AI Gateway — Use any SDK to call 100+ LLMs. Built-in failover, load balancing, cost control & end-to-end tracing.
At a glance
- What is it?
- AxonHub is an open-source AI gateway that translates OpenAI, Anthropic, and other SDK calls to 100+ LLMs. It targets vendor lock-in but ships as a beta under the Apache-2.0 license with a default branch named unstable.
- Who is it for?
- Adopt AxonHub if you run multiple AI SDKs or model providers and need a single translation layer with failover, load balancing, and cost tracking, and if you can tolerate a beta-stage project. Do not adopt it for production-critical workloads without testing the claimed sub-100ms failover on your own network.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
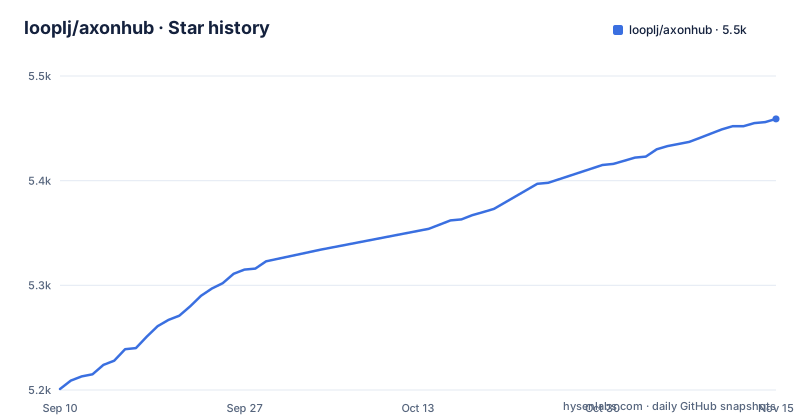
- looplj/axonhub5,459 ★ · +258
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| looplj/axonhub | 5.2k | 5.5k |
258 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What AxonHub Actually Solves
AxonHub addresses a concrete pain: teams that write code against one model provider's SDK and later want to switch to another provider without rewriting that code. The README frames it as eliminating vendor lock-in, letting you move from GPT-4 to Claude or Gemini by changing configuration only. It also targets integration complexity, since you would otherwise maintain separate request formats for each provider. The project positions itself as an AI gateway that sits between your application and the model APIs, converting requests and responses on the fly. The intended users are developers building agents or applications that consume large language models, particularly those who use multiple SDKs like OpenAI, Anthropic, or generic AI SDKs.
How the Gateway Mechanism Works
The core mechanism is protocol translation. AxonHub accepts requests in the format of one SDK, for example the OpenAI SDK, and transparently converts them into the format expected by the target provider, such as Anthropic's Claude. The README claims you can use the OpenAI SDK to call Claude, or the Anthropic SDK to call GPT, with zero code changes. This implies a mapping layer that handles differences in endpoint paths, request schemas, authentication headers, and response structures. The feature table also points to load balancing and failover: AxonHub routes each request to the healthiest channel, and if one provider fails, it automatically switches to another in under 100 milliseconds, according to the README. The gateway also tracks cost per request, breaking down input, output, and cached tokens. It offers request tracing at the thread level, which suggests it instruments each call with a timeline for debugging. This is not a proxy that just forwards traffic; it is a stateful translator that maintains provider health, usage records, and access control.
Getting It Running: Commands and Configuration
It does state that AxonHub is Docker Ready, based on a badge, and the repository is written in Go. The homepage is axonhub.onrender.com, indicating a hosted demo may exist. To run it yourself, the repository ships a Dockerfile and a docker-compose.yml that runs AxonHub with PostgreSQL, and the Makefile has build targets for the Go backend and the frontend. The documentation index referenced in the README, docs/zh/index.md, likely contains setup instructions. The repository also ships config.example.yml, and the compose file says environment variables take priority over the config file. The project has a docs/zh directory with guides on load balancing, tracing, permissions, and cost tracking, which suggests that after installation you would configure channels, which represent different model providers or API endpoints, and set up routing rules. The mention of enterprise-level RBAC implies you can define users, roles, and usage quotas.
The Beta State and the Unstable Branch
AxonHub is not a mature release. The latest version is v1.0.0-beta12, published on 2026-11-02, with beta11 on 2026-10-08 and beta10 on 2026-09-06. The default branch is named unstable, which is an honest signal that the project does not guarantee a stable API or behavior between commits. Regular beta releases, roughly one a month, suggest active development but also indicate that breaking changes are likely. For an engineering team evaluating this gateway, the unstable branch means you should pin a specific release tag rather than track the default branch. The beta designation also implies that features like the sub-100ms failover and the full request tracing may not be battle-tested at scale. The README's claim of supporting 100+ LLMs is broad, and the README's Supported Providers table lists OpenAI, Anthropic, Zhipu, Moonshot, DeepSeek, ByteDance Doubao, Gemini and Jina AI among others, with the compatible APIs for each.
Licensing and Maintenance Cost
The repository is licensed under Apache-2.0, with LICENSE and NOTICE files at the root. Maintenance cost is another factor: the project appears to be actively maintained, with recent pushes and a series of beta releases. However, the default branch being unstable means you should expect to invest time in tracking changes. The documentation is split across multiple languages, with an English README.en-US.md available, but the main README is in Chinese with some English feature descriptions. This bilingual setup may add friction for non-Chinese-speaking teams.
A Real Alternative: LiteLLM or Kong AI Gateway
A direct alternative to AxonHub is LiteLLM, an open-source proxy that also translates between OpenAI, Anthropic, and other providers. LiteLLM is Python-based and has a long track record. The key difference in approach is that LiteLLM focuses on a unified API that mimics the OpenAI format, so you point your existing OpenAI SDK at the proxy and it handles the rest. AxonHub claims to accept any SDK format natively, not just OpenAI, which is a broader promise. Another alternative is Kong's AI Gateway, which is a plugin for the Kong API gateway, offering traffic control, load balancing, and observability as part of an existing API infrastructure. Kong takes a more enterprise-oriented approach, integrating with your existing gateway policies, whereas AxonHub is a standalone service. If you already run Kong, adding its AI plugin may be simpler than deploying a new Go service. The choice depends on whether you want a purpose-built gateway with its own UI and tracing (AxonHub) or a component within a larger API management stack.
What the README Does Not Tell You
Several claims in the README lack supporting detail. The sub-100ms failover is presented as a headline feature, but the feature table gives no benchmark data to back it up. The README says AxonHub provides end-to-end tracing and thread-level observability, and points to docs/zh/guides/tracing.md for the details. Cost tracking is similarly described with a table, but the mechanism for tracking cached tokens is not explained. The project also lists enterprise-level RBAC, but the permission model is not described beyond fine-grained access control and usage quotas. The sponsor section dominates the README, with multiple commercial API resellers promoting their services, which raises questions about the project's neutrality. The README is partly a marketing page for those sponsors. As an evaluator, you should treat the feature list as a roadmap rather than a verified specification, and you must run the project yourself or read the linked docs to confirm each capability.
Editorial conclusion
Adopt AxonHub if you run multiple AI SDKs or model providers and need a single translation layer with failover, load balancing, and cost tracking, and if you can tolerate a beta-stage project. Do not adopt it for production-critical workloads without testing the claimed sub-100ms failover on your own network. Check the unstable default branch and the latest beta release notes before committing. Verify that your specific SDK and provider pair is supported by reading the docs/zh/api-reference and tracing guides, because the README's promise of any SDK to any model is broad and needs concrete confirmation.
Frequently asked questions
What is AxonHub, the AI gateway?
It is a gateway written in Go that translates your request into whatever format the target provider expects, so you can call Claude from an OpenAI SDK or GPT from an Anthropic SDK without changing code. Around that it adds a full request timeline, role based access control with quotas, automatic failover between channels and per request cost tracking.
How do I use AxonHub for the first time?
Start from the compose file at the root: set DB_PASSWORD, AXONHUB_IMAGE and POSTGRES_IMAGE, then bring it up. It publishes ${AXONHUB_BIND_ADDRESS:-127.0.0.1}:${AXONHUB_HOST_PORT:-8090}:8090, so the first run is reachable on port 8090 from the machine only. config.example.yml is the starting point for file based configuration, which the compose file treats as lower priority than environment variables.
Which Go toolchain does AxonHub need?
The module file declares go 1.26.4 for module github.com/looplj/axonhub, and the Dockerfile runs its module download with GOTOOLCHAIN=auto, which lets the toolchain fetch what the module asks for. The build also downloads a second, nested module, so llm/go.mod and llm/go.sum are copied in before the download step.
How does AxonHub build its web interface?
The Dockerfile starts from node:26-alpine, installs [email protected] and enables it, installs with a frozen lockfile and a mounted pnpm store cache, and raises the Node heap with NODE_OPTIONS=--max-old-space-size=4096. The resulting dist directory is copied into internal/server/static/dist so the Go binary serves it, and the Makefile has its own build-frontend target that does the same copy from the host.
Which databases does AxonHub support?
The compose deployment runs Postgres through a service named postgres with AXONHUB_DB_DIALECT set to postgres and a DSN built from DB_PASSWORD, while the Makefile cleanup-db target works on a local SQLite file called axonhub.db. The module dependencies include the Postgres driver pgx/v5 and the MySQL driver, so more than one backend is compiled in even though the shipped compose file wires up Postgres.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/looplj-axonhub)Star history chart for your README
[](https://hysenlabs.com/projects/looplj-axonhub)Was this useful?