maderix/ANE: Training Transformers on Apple's Neural Engine Through Private APIs
Training neural networks on Apple Neural Engine via reverse-engineered private APIs
At a glance
- What is it?
- A research project that reverse-engineers _ANEClient and _ANECompiler to run backpropagation on the Apple Neural Engine. It works, but it is not a framework, and its own author says so.
- Who is it for?
- Adopt maderix/ANE only if you want to study how the ANE is driven outside CoreML, or if you are prepared to fork it and carry the maintenance yourself. It is the wrong tool for anyone who needs a supported training stack, stable APIs, or a promise that the next macOS release will not break the build.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Objective-C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
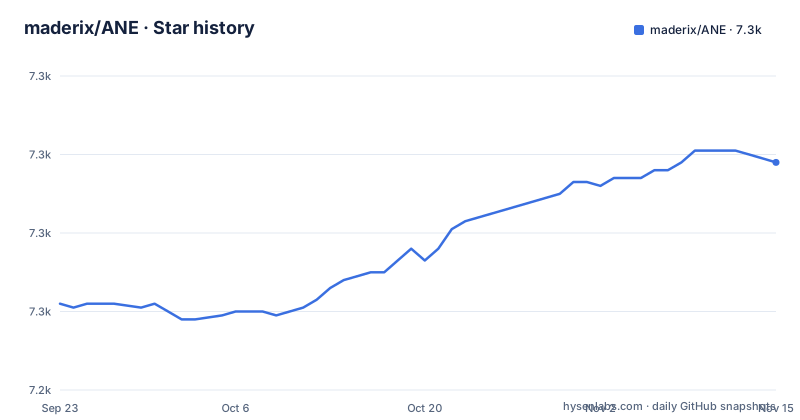
- maderix/ANE7,298 ★ · +36
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| maderix/ANE | 7.3k | 7.3k |
36 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem: Apple exposes the ANE for inference only
The Apple Neural Engine is a 15.8 TFLOPS FP16 accelerator on M4 silicon, according to the README. Apple surfaces it through CoreML, and CoreML is an inference path. There is no supported way to run a backward pass on it. So the hardware sits there, fast and idle, while training happens on the GPU or the CPU.
maderix/ANE exists to show that the barrier is software, not silicon. The README states the goal directly: to demonstrate that training on the Apple Neural Engine, and potentially other NPUs, is possible. The author calls it a weekend research hack that grew beyond expectations.
The audience is narrow and worth naming. This is for engineers who want to understand how the ANE is actually driven at the API level, who are comfortable reading Objective-C and MIL, and who treat the repository as a reference rather than a dependency. It is not for teams that need a training loop they can ship.
How the ANE training pipeline is put together
The project bypasses CoreML entirely. It reverse-engineers the `_ANEClient` and `_ANECompiler` private APIs plus the MIL (Model Intermediate Language) format, then compiles custom compute graphs and dispatches them to ANE hardware.
The dynamic pipeline packs weights into spatial dimensions so that changing weights does not trigger a recompile. For MHA models such as Stories110M, that means six kernels per layer: `sdpaFwd` for the QKV projection, scaled dot-product attention and output projection; `ffnFused` for the SwiGLU FFN; `ffnBwdW2t` and `ffnBwdW13t` for the FFN backward pass, split for memory reasons; and `sdpaBwd1` and `sdpaBwd2` for SDPA backward. GQA models such as Qwen3-0.6B add `woFwd`, `qBwd` and `kvBwd` for grouped-query attention where Q_DIM differs from DIM, bringing the count to ten kernels per layer.
The split between ANE and CPU is the part that decides whether this is useful to you. Forward and backward dx passes run on the ANE. The dW gradients run on the CPU through Accelerate cblas. RMSNorm forward and backward, residual connections with DeepNet alpha scaling, loss computation, gradient accumulation and the Adam optimizer also live on the CPU. The README is explicit that many element-wise operations still fall back to CPU.
Several optimizations are documented. A channel-first CPU layout matches the ANE IOSurface `[1,C,1,S]` format and removes transpose overhead. vDSP vectorized RMSNorm is reported as 10x faster than the naive version, 6.7ms down to 0.7ms. The dW gradient sgemms overlap with ANE evaluations on a serial dispatch queue via GCD, and the cblas wait is deferred into the next step's forward pass. RMSNorm is folded into forward kernels as MIL ops, and the output projection backward is merged into the SDPA backward kernel. Forward taps expose Q, K, V, attention scores and hidden states through concat outputs so the CPU does not recompute them. An `exec()` restart works around a limit of roughly 119 ANE compiles per process. There is also a GPU to ANE zero-copy pipeline over shared IOSurface, described as GPU prefill feeding ANE decode.
The README reports 91 ms per step for Stories110M at 109M parameters and 412 ms per step for Qwen3-0.6B at 596M parameters, both on the dynamic no-recompile pipeline. Those are the author's numbers on the author's hardware, not an independent measurement.
Installing maderix/ANE and running a first benchmark
The repository root holds a set of standalone Objective-C source files, each one a self-contained experiment. The top-level entries include `api_exploration.m`, `inmem_basic.m`, `inmem_bench.m`, `inmem_peak.m`, `ane_int8_bench.m`, `sram_bench.m` and `sram_probe.m`, alongside `benchmarks/`, `bridge/`, `training/` and `assets/` directories.
The file names tell you what each one does. `inmem_basic.m` is described as an in-memory MIL compilation proof-of-concept, so it is the smallest thing to look at first. `inmem_bench.m` measures ANE dispatch latency. `inmem_peak.m` measures peak TFLOPS with a 2048x2048 matmul. `ane_int8_bench.m` compares INT8 W8A8 against FP16 throughput.
For the training side, the relevant code lives under `training/`. The README says the pipeline supports Adam, gradient accumulation and checkpoint/resume via `exec()` restart.
Where maderix/ANE falls short
The author is unusually direct about the limits, and they are severe enough to change the adoption decision.
Utilization is low. The README states training works but runs at roughly 5 to 9 percent of peak, with significant engineering challenges remaining. That number should anchor every performance expectation. The 91 ms and 412 ms per-step figures are real, but they are achieved at a small fraction of what the silicon can do.
Many element-wise operations still fall back to CPU. The dW gradients are entirely on CPU via cblas, as are RMSNorm, residuals, loss and the optimizer. So the ANE is doing the forward pass and the dx backward pass while the rest of the training loop runs on general-purpose cores. That split limits how much you gain as models grow.
The project does not replace GPU training for anything beyond small research models today. That is the README's own sentence. If you are training something larger, this is not the path.
Maintenance is the other constraint. The README states the author does not intend to grow this into a large community project, that feature requests will likely go unaddressed, and that PRs will be merged at a relatively slow pace. The last push was on 2026-03-10. The repository has no published GitHub releases. Anyone adopting it should plan to fork.
Finally, the API surface is private. `_ANEClient` and `_ANECompiler` are not public interfaces, which means an OS update can change or remove them without notice.
How this differs from MLX and CoreML
The README names its own non-alternatives: it is not a replacement for CoreML, MLX or llama.cpp. The distinction is worth spelling out because the projects are often confused.
CoreML is Apple's supported path to the ANE, and it is inference only. You get a documented API, model conversion tooling and OS-level stability. You do not get a backward pass. maderix/ANE trades all of that stability for the ability to run training kernels on the same hardware.
MLX is Apple's array framework for Apple Silicon, and it targets the GPU and CPU with a unified memory model. It is a general-purpose training and inference stack with a public API. maderix/ANE is not a framework at all: it is a set of MIL kernels and dispatch code aimed at one accelerator, with the surrounding training loop partly on CPU.
llama.cpp is an inference engine for language models, optimized for quantized inference across many backends. It does not train. The overlap with maderix/ANE is the INT8 W8A8 work, where the README reports 1.88x throughput over FP16 on a 128x conv 512ch 64x64 configuration and 1.85x on a 64x conv configuration. That quantization uses MIL `quantize`/`dequantize` ops for activations and `constexpr_affine_dequantize` for weights, with int8 stored and fp16 at compile time. It is a benchmark result about ANE throughput, not a drop-in inference runtime.
So the real choice is not between competing trainers. It is between a supported inference stack that cannot train on the ANE, and a research codebase that can, at low utilization and with no support contract.
Licence and the cost of keeping it running
The repository is MIT licensed. That is the most permissive outcome for anyone who wants to fork, modify and redistribute, and the README leans into it deliberately, inviting readers to take the code and build something better. It also notes that if the community decides to maintain a single source of truth repository in the future, the author supports that.
MIT does not carry a warranty, and this project needs one more than most. It links against private Apple APIs, so the practical maintenance cost is not the MIT terms, it is the reverse-engineering surface. Every OS update is a chance that `_ANEClient` or `_ANECompiler` changes shape, that MIL op semantics shift, or that the roughly 119-compile-per-process limit moves. None of that is covered by the licence.
The upgrade cost for a fork is therefore open-ended: you own the private API layer. If that is acceptable, MIT gives you everything you need to proceed. If it is not, no licence term will help. This is a description of the licence and the technical surface, not legal advice.
Editorial conclusion
Adopt maderix/ANE only if you want to study how the ANE is driven outside CoreML, or if you are prepared to fork it and carry the maintenance yourself. It is the wrong tool for anyone who needs a supported training stack, stable APIs, or a promise that the next macOS release will not break the build. Before investing time, read the three Substack articles linked from the README, confirm your machine is Apple Silicon with an ANE, and check whether the training/ directory covers the model shape you care about. The repository's own scope statement is the clearest signal: this is a proof of concept, not a maintained framework.
Frequently asked questions
What does maderix/ANE actually do?
It trains transformer models on the Apple Neural Engine using reverse-engineered `_ANEClient` and `_ANECompiler` private APIs and the MIL format, rather than CoreML. The README describes it as a proof of concept for ANE training and a set of benchmarks documenting ANE performance characteristics.
Is maderix/ANE a production framework?
No. The README states plainly that this is a research project, not a production framework, and that it is not a replacement for CoreML, MLX or llama.cpp. It also says feature requests will likely go unaddressed and PRs will be merged at a relatively slow pace.
How fast is training on the Apple Neural Engine with maderix/ANE?
The README reports 91 ms per step for Stories110M at 109M parameters and 412 ms per step for Qwen3-0.6B at 596M parameters on the dynamic no-recompile pipeline. It also states utilization is low, around 5 to 9 percent of peak, and that many element-wise operations still fall back to CPU.
Does maderix/ANE replace GPU training?
The README says it does not replace GPU training for anything beyond small research models today. Forward and backward dx passes run on the ANE, but dW gradients, RMSNorm, residuals, loss and the Adam optimizer run on the CPU.
What licence is maderix/ANE under and can I fork it?
It is MIT licensed, and the README explicitly invites readers to take the code, modify it and build something better. The author also says he would support a community-maintained single source of truth repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/maderix-ane)Star history chart for your README
[](https://hysenlabs.com/projects/maderix-ane)Was this useful?