PageIndex swaps the vector store for a document tree and an LLM that reads it
PageIndex: Document Index for Vectorless, Reasoning-based RAG. Inspired by AlphaGo, we propose **PageIndex**, a **vectorless**, **reasoning-based RAG** system that builds a **hierarchical tree index** from long documents, and uses LLMs to **reason** *over that index* for **agentic, context-aware retrieval**.
At a glance
- What is it?
- VectifyAI/PageIndex is an MIT-licensed Python SDK that builds a hierarchical tree index from long documents and lets a chat model reason its way to the right section. It removes embeddings and chunking, but moves retrieval cost and quality onto the LLM you choose, and its dependency pins need care.
- Who is it for?
- PageIndex fits teams answering questions over long professional documents such as 10-K filings, contracts or manuals, where tracing an answer to a section matters more than per-query cost. It fits poorly where every query must be cheap and instant, because each answer runs a chat model over the tree, or where the Python environment cannot accept its tight litellm and PDF library pins.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
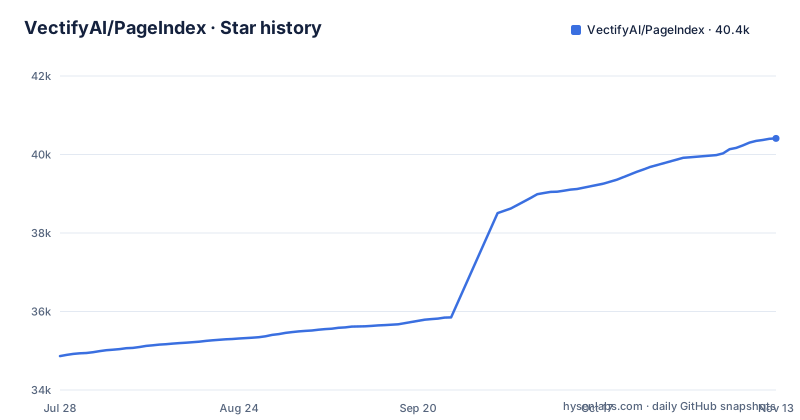
- VectifyAI/PageIndex40,409 ★ · +5,545
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| VectifyAI/PageIndex | 34.9k | 40.4k |
5,545 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A tree index replaces embeddings and chunking
PageIndex starts from the claim that similarity is not relevance. Vector RAG embeds the query and returns text that looks similar, which on professional documents can miss a passage that is relevant but phrased differently, or return one that is similar but beside the point. PageIndex removes the vector database and the chunking step entirely and works in two stages: first it generates a tree-structure index for each document, then an LLM searches that tree by reasoning, much as an analyst opens a long report to the right chapter.
The project frames the difference in four rows. Vector RAG uses a vector index, retrieves by semantic similarity, produces results that are hard to trace, and sees only the query embedding. PageIndex uses a tree index, retrieves by LLM reasoning over the tree, returns results traceable to explicit references, and can take the full context into account, including conversation history and domain knowledge. The intended targets are financial reports, legal documents, regulatory filings, technical manuals, medical literature and academic textbooks.
Two model slots with very different jobs
The SDK installs from PyPI:
pip install -U pageindexA client takes two models, one for building the index and one for searching it:
import os
from pageindex import PageIndexClient

os.environ["OPENAI_API_KEY"] = "your-openai-key"

client = PageIndexClient(
    index="gpt-6-luna",                 # model to build the tree index
    chat="gpt-6-sol",                   # model to search the tree
)
doc_id = client.submit_document("report.pdf")["doc_id"]

answer = client.chat("What was the 2023 operating margin?", doc_id=doc_id)
print(answer)
The split matters for budgeting. The tree structure itself comes from the document layout without an LLM; the `index=` model only summarizes and refines it, so a basic model is enough there. The `chat=` model does the actual retrieval by walking the tree, and the guidance is to use the best model you can afford. The chat model is the slot where cutting cost trades directly against retrieval quality.
Every question is an LLM reasoning run, not a lookup
Because retrieval is reasoning over the tree, each question spends chat-model tokens. There is no precomputed similarity score to fall back on, so query cost grows with the number of questions and the price of the chat model, not just with corpus size.
The project's PageIndex Financial QA Benchmark measures this trade directly. It compares 34 configurations of 19 LLMs answering 100 questions over 40 Form 10-K filings from 8 companies, with PageIndex doing the retrieval, and reports cost per 100-question run, excluding one-time indexing. That design is useful: it shows accuracy and price side by side for different chat models rather than a single headline number. It is also a vendor benchmark on one document type. If your corpus is not financial filings, run your own question set before assuming the same accuracy and cost curve holds.
For teams where per-query latency is the constraint, VectifyAI also offers a hosted Page Search API that finds the answering pages in about a second; the 97% token cost reduction it advertises applies to that service, not to the open-source SDK.
Indexing is cheap and done once per document
Building a tree locally costs about $0.001 per page with `gpt-5.6-luna` as the index model, so a 1,000-page textbook comes to a little over a dollar and a few minutes, paid once and reused for every later question. In the same local setup, benchmark documents from 9 to 1,098 pages finished indexing in roughly 13 seconds to 4.5 minutes. PageIndex is designed not to depend heavily on the index model, and the project reports that a basic model did not hurt quality in its experiments.
The default indexing method in local mode is PageIndex Flash, a fast tree generator for text-based PDFs. The qualifier matters: Flash is built around PDFs that carry a text layer, so a corpus of scanned images is outside what that default is designed for, and you should check the docs at docs.pageindex.ai for how such files are handled before committing a scanned archive to it.
Local mode and the hosted products are separate things
The SDK runs in two modes from one client. In local mode it indexes, retrieves and chats on your machine with your own LLM API key, as in the `OPENAI_API_KEY` example above. In cloud mode the same client talks to PageIndex Cloud at developer.pageindex.ai instead of running on your machine.
Several things that appear alongside the repository are hosted products rather than parts of the MIT package: the Page Search API at search.pageindex.ai, the PageIndex App at app.pageindex.ai, described as a document analysis agent for long professional documents, and PageIndex Cloud itself. PageIndex File System, a file-level tree indexing layer for reasoning over an entire corpus instead of one document, is presented through the blog. Anyone comparing pricing should separate the open-source SDK, where you pay only your LLM provider, from these services.
PageIndex tools can be dropped into the OpenAI Agents SDK, the Claude Agent SDK or other agent frameworks, with integration notes at docs.pageindex.ai/sdk/agents.
Claude models through a Claude Code subscription
There is a second way to supply models that avoids an API key. With a Claude subscription, PageIndex can call Claude models through Claude Code, with usage covered by the plan. It needs an extra:
pip install -U "pageindex[claude]"Model names then take a `claude-code/` prefix, for example `index="claude-code/haiku"` and `chat="claude-code/opus"`, which matches the split above: a smaller model to refine the index and a stronger one to search it. A worked example lives in `cookbook/pageindex-claude-subscription.py`.
The consequence is that indexing and question answering count against your Claude plan rather than an API bill, so the plan's usage limits become the ceiling on how much you can index and ask.
Tight dependency pins can clash with your environment
The package supports Python 3.10 and later, with classifiers for 3.10 through 3.13, and several of its dependency bounds are narrow for stated reasons. `litellm` is capped at `>=1.105.1,<1.106`: from 1.106 a call with tools imports LiteLLM's proxy MCP handler, which needs `mcp>=2.2`, and the cap is meant to lift at the first clean 1.107 release because 1.107.0 was malware. `openai-agents` must be at least 0.20.0, since older releases broke resending streamed chat messages. `mcp` is held at `>=1.19.0,<3` and `openai` at `>=2.45.0`.
`requirements.txt` goes further and pins exact versions: `PyPDF2==3.0.1`, `pypdfium2==5.13.0` and `sortedcontainers==2.4.0`. Installing from that file into an environment shared with another LLM framework can force a litellm downgrade or a PDF library conflict. A dedicated virtual environment avoids the fight; mixing it into an existing agent stack means resolving those pins first.
Alpha status and version numbers that do not line up
PageIndex is MIT licensed and moving fast: v0.4.7 was tagged on 2026-10-24, v0.5.0 on 2026-10-29 and v0.5.1 on 2026-11-03, and the last push to the repository was on 2026-11-02. The package still declares `Development Status :: 3 - Alpha`.
The version strings disagree. GitHub release tags have reached v0.5.1, while `pyproject.toml` on the default branch names the package version `0.2.10`. When you report a bug or pin a dependency, record the version pip actually installed rather than the release tag you read about. Given the alpha label and weekly releases, pin an exact version in production and read the release notes before upgrading.
Editorial conclusion
PageIndex fits teams answering questions over long professional documents such as 10-K filings, contracts or manuals, where tracing an answer to a section matters more than per-query cost. It fits poorly where every query must be cheap and instant, because each answer runs a chat model over the tree, or where the Python environment cannot accept its tight litellm and PDF library pins. Before adopting it, run your own questions with the chat model you can afford and check which package version pip resolves.
Frequently asked questions
What are the key differences between PageIndex and a vector database?
A vector database retrieves by semantic similarity between embeddings. PageIndex builds a hierarchical tree index of each document and has an LLM reason over that tree, with no vector database and no chunking, so results trace back to explicit sections.
How does PageIndex work in RAG?
PageIndex works in two steps: it generates a tree-structure index for each document, then a chat model agentically searches that tree to find the relevant sections for the question.
How do you use PageIndex locally?
Install it with pip install -U pageindex, set your own LLM API key such as OPENAI_API_KEY, and create a PageIndexClient with an index model and a chat model. Local mode indexes, retrieves and chats on your machine, using PageIndex Flash by default for text-based PDFs.
Is PageIndex open source?
Yes. The PageIndex Python SDK in VectifyAI/PageIndex is released under the MIT license. PageIndex Cloud, the Page Search API and the PageIndex App are separate hosted services.
Is PageIndex free?
The SDK is free under MIT, but local mode calls your own LLM provider, so you pay for those tokens. Local indexing runs about $0.001 per page with gpt-5.6-luna, and each question costs chat-model tokens.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- Show HN: Vectorless, Reasoning-Based RAGHacker News · Oct 1, 2026 · 8 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vectifyai-pageindex)Star history chart for your README
[](https://hysenlabs.com/projects/vectifyai-pageindex)Was this useful?