mimalloc: Microsoft's free-list-sharded allocator and how to drop it into an existing binary
mimalloc is a compact general purpose allocator with excellent performance.
At a glance
- What is it?
- mimalloc is a general purpose allocator that can replace malloc without recompiling your program on ELF systems, and v3 is the version Microsoft recommends. Here is how the free list sharding works, how to install it, and where it is the wrong choice.
- Who is it for?
- Adopt mimalloc if you run a long-lived service or a runtime system on Linux, macOS, Windows, WASM or a BSD, and you want an allocator you can read end to end: about 12k LOC, MIT licensed, with v3.6.1 as the recommended tag. Do not adopt it if you need an allocator whose behaviour you can reason about without reading C source.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
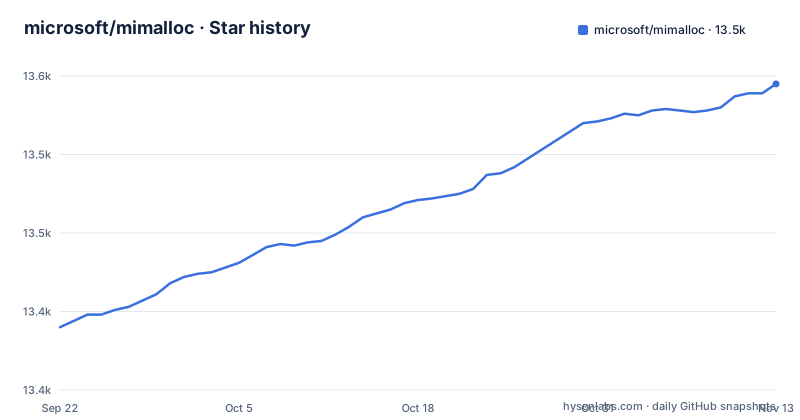
Star history
- microsoft/mimalloc13,545 ★ · +155
| Repository | 2026-09-22 | 2026-11-13 |
|---|---|---|
| microsoft/mimalloc | 13.4k | 13.5k |
155 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem mimalloc targets: allocator contention and fragmentation in long-running services
General purpose allocators are shared state. Every thread that calls malloc and free touches structures that other threads also touch, and the cost of that coordination shows up as worst-case latency rather than average throughput. mimalloc was initially developed by Daan Leijen for the runtime systems of the Koka and Lean languages, which is a telling origin: language runtimes allocate and free constantly, from many threads, and cannot tolerate a stop-the-world pause inside the allocator.
The README frames the goal as bounded behaviour. It claims no blowup, bounded worst-case allocation times up to OS primitives, roughly 0.2% metadata overhead, and no internal points of contention beyond atomic operations. Those are design constraints, not benchmark results, and they explain most of the structural choices below. The audience is therefore narrower than "everyone who allocates memory": it is people writing or embedding runtimes, distributed services that run on thousands of machines, and anyone who has profiled an allocation stall and found the allocator at the bottom of the stack.
Free list sharding and multi-sharding: the mechanism behind mimalloc's low contention
Instead of one free list per size class, mimalloc keeps many smaller lists, one per mimalloc page. A page holds blocks of a single size class and is usually 64KiB on a 64-bit system. Sharding this way reduces fragmentation and improves locality: objects allocated close in time tend to land close in memory.
The larger idea is multi-sharding. Each page carries more than one free list, and specifically one list is reserved for thread-local frees while another serves concurrent frees. Freeing a block from a different thread than the one that allocated it becomes a single compare-and-swap, with no elaborate coordination between threads. Because thousands of separate free lists exist, contention spreads across the heap rather than concentrating on one location. The README compares this to randomized algorithms such as skip lists, where a random oracle removes the need for a more complex algorithm.
Two consequences follow. First, a page can become empty more easily, which is why eager page purging matters: when a page empties, mimalloc marks the memory as unused to the OS, either resetting or decommitting it, which reduces real memory pressure in long-running programs. Second, the allocator needs a way to walk its own heap, and v3 improves heap-walking efficiency, which the README calls out as useful for the CPython garbage collector. v3 also simplifies the lock-free design of earlier versions and improves memory sharing between threads; on certain large workloads the README states it may use much less memory. That is a claim from the project, not something verified here.
Installing mimalloc and using LD_PRELOAD on a real binary
The repository is a CMake project: CMakeLists.txt sits at the top level alongside cmake/ and src/, and the README points to the documentation site for the full API. The exact configure and build invocation depends on your platform and on the options you pass to CMake. What the README does give is the payoff once the shared library exists: on dynamically linked ELF-based systems such as Linux and the BSDs, you can use it as a drop-in replacement for malloc with no code changes.
LD_PRELOAD=/usr/lib/libmimalloc.so myprogramThat single line is the whole integration for a dynamically linked binary. The path is the one the README uses as its example; your build will place libmimalloc.so wherever your install prefix says.
The README also states that mimalloc includes a way to dynamically override the default allocator on Windows, and describes this as having excellent support for dynamic overriding generally. For a first real use, LD_PRELOAD against a service you already run is the cheapest test: it requires no source changes, and reverting means removing the environment variable. That reversibility is a property of the preload approach, not of an in-process API swap.
mimalloc v3 versus v2 and v1: which tag to pin
Three versions are maintained, and they are mostly equal except for how OS memory is handled. New development happens mostly on v3, while v1 and v2 receive security and bug fixes. The README's own recommendation is v3.6.1, released 2026-10-30. v2.5.2 and v1.15.2, both dated 2026-09-12, are labelled stable legacy and legacy respectively.
The version split is not cosmetic. v2 uses thread-local segments to reduce fragmentation; v3 simplifies the lock-free design and improves sharing of memory between threads. v3 adds true first-class heaps that can allocate from any thread, whereas the older model gave you heaps that were efficient but not truly first-class in that sense. v3 also has more efficient heap-walking, which the README ties to the CPython GC.
There is a practical wrinkle worth stating plainly. The README says to send pull requests against v1 if possible, and otherwise against dev3. That is an unusual instruction for a project whose recommended release is v3, and it suggests the v1 line still carries a maintenance burden the project wants help with. If you are choosing a version today, the README's own guidance points at v3.6.1; the v1 request is about where to send patches, not about where to start.
Secure mode, the 10% penalty, and when mimalloc is the wrong tool
mimalloc can be built in a secure mode that adds guard pages, randomized allocation, encrypted free lists and similar measures to defend against heap vulnerabilities. The README states the performance penalty is usually around 10% on average over the project's own benchmarks. That is a project figure, and it is an average: a workload that leans on the specific operations secure mode hardens will feel more than 10%.
The bigger limitation is documentation depth. The README is a design document, not an operations manual. The v3.6.1 notes mention a `-DMI_SECURE=MINIMAL` option for secure mode with minimal (~1%) performance impact, which puts guard pages around all mimalloc meta-data but does not encode free lists.
Two other cases argue against mimalloc. If your program is statically linked, the LD_PRELOAD trick does not apply, and you are back to linking the library and rebuilding. And if your problem is not allocator contention at all (say you are chasing a leak in application code), swapping allocators changes the symptom without addressing the cause, and you will have added a variable to an already confusing investigation. The README's performance claims are the project's own benchmarks against jemalloc, tcmalloc, Hoard and others; treat them as a reason to measure on your workload, not as a result that transfers.
mimalloc versus jemalloc and tcmalloc: different answers to the same question
The most common comparison is mimalloc against jemalloc. Both are general purpose allocators aimed at reducing fragmentation and contention, but they get there differently. jemalloc is the long-standing choice in this space and is widely deployed; its size classes, arenas and extent management are a different architecture from mimalloc's per-page free lists. mimalloc's distinguishing bet is multi-sharding: rather than coordinating threads through shared arena structures, it gives each page separate lists for thread-local and concurrent frees so a cross-thread free is one compare-and-swap. The README's framing is that this distributes contention the way randomization does in a skip list.
tcmalloc, the other frequent comparison, comes from the same broad lineage of thread-caching allocators, and the README lists it among the allocators mimalloc outperforms in the project's benchmarks. The honest difference to evaluate is not which wins a benchmark suite but which one's failure modes you can live with. mimalloc's selling point for a runtime author is the combination of a small codebase (about 12k LOC, which the README calls suitable for integrating and adapting into other projects) and explicit hooks: a monotonic heartbeat and deferred freeing for bounded worst-case times with reference counting.
If you are choosing between them, the deciding question is whether you intend to embed and modify the allocator. If yes, mimalloc's size and hooks are the argument. If you just want a drop-in for an existing service and will never read the source, the three are close enough that your own benchmark decides.
Licence, upgrade cost, and what the release cadence implies
mimalloc is MIT licensed, and the LICENSE file sits at the top level of the repository. MIT is permissive: it permits use, modification and redistribution with the licence and copyright notice retained. Static linking is allowed under MIT, which matters here because LD_PRELOAD only covers dynamically linked binaries and the static case is exactly where you link the library into your own build. This is a general description of the licence text, not legal advice; your counsel should confirm obligations for your distribution model.
The maintenance picture is current. The last push to the repository was on 2026-11-02, and the repository is not archived. Releases are frequent: v3.5.3 on 2026-09-17, v3.6.0 on 2026-10-23 and v3.6.1 on 2026-10-30. The v3.6.1 notes list many small fixes for CPython integration, Emscripten fixes, improved fork support and the new `-DMI_SECURE=MINIMAL` option. v3.6.0 added initial profiling hooks and a default profiler, always-on detailed statistics per size-bin, and initial Rust bindings.
That cadence is the upgrade cost. Tracking releases means re-testing an allocator swap on every minor bump, and because the library is loaded into your process, a regression surfaces as a crash or a latency spike rather than a clean error. The profiling hooks arrived in v3.6.0 and are described as initial.
Editorial conclusion
Adopt mimalloc if you run a long-lived service or a runtime system on Linux, macOS, Windows, WASM or a BSD, and you want an allocator you can read end to end: about 12k LOC, MIT licensed, with v3.6.1 as the recommended tag. Do not adopt it if you need an allocator whose behaviour you can reason about without reading C source. Before committing, verify the two things the README leaves open: whether your platform needs the dynamic override built explicitly, and whether secure mode's roughly 10% average penalty over the project's own benchmarks fits your latency budget.
Frequently asked questions
What does mimalloc mean?
The README says mimalloc is pronounced "me-malloc".
What is mimalloc?
It is a compact general purpose allocator with a drop-in replacement for malloc, initially developed by Daan Leijen for the runtime systems of the Koka and Lean languages. The README describes it as about 12k LOC with simple and consistent data structures.
How do I install mimalloc?
The repository is built with CMake, with CMakeLists.txt at the top level. The README points to the documentation site for the API and shows the LD_PRELOAD usage once libmimalloc.so exists.
How do I use mimalloc in an existing program?
On dynamically linked ELF-based systems such as Linux and the BSDs, the README gives LD_PRELOAD=/usr/lib/libmimalloc.so myprogram as a drop-in replacement with no code changes. Windows also has a documented way to dynamically override the default allocator.
Which is better, mimalloc or jemalloc?
The README claims mimalloc outperforms jemalloc and other leading allocators in the project's own benchmarks, and often uses less memory. The structural difference is mimalloc's free list multi-sharding, where cross-thread frees are a single compare-and-swap rather than coordinated through shared arena structures.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/microsoft-mimalloc)Star history chart for your README
[](https://hysenlabs.com/projects/microsoft-mimalloc)Was this useful?