Milvus 3.0: A Vector Database That Separates Compute from Storage for Scale
Milvus is a cloud-native vector database in Go and C++ for scalable ANN search over billions of vectors, with CPU/GPU acceleration and real-time streaming updates.
At a glance
- What is it?
- Milvus is a cloud-native vector database built in Go and C++ for billion-scale ANN search. This review covers its architecture, index support, deployment modes, and the trade-offs you face when choosing it.
- Who is it for?
- Adopt Milvus if you need a horizontally scalable vector database with real-time streaming updates and a mature ecosystem around Kubernetes. Avoid it if your workload is a small prototype where Milvus Lite or a simpler tool suffices.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
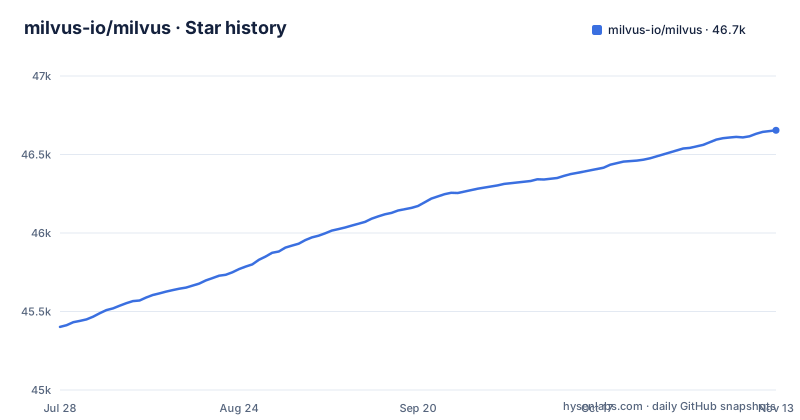
- milvus-io/milvus46,654 ★ · +1,252
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| milvus-io/milvus | 45.4k | 46.7k |
1,252 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem Milvus Solves
Milvus addresses a specific pain point: storing and searching vector embeddings at a scale that a single machine cannot handle. Applications that generate embeddings from text, images, or multi-modal data need a database that can ingest billions of vectors, keep them fresh with streaming updates, and answer thousands of queries per second. Milvus is built for that scale, not for toy demos. It is aimed at teams running production AI workloads who need more than an in-memory index. The README positions it as a high-performance vector database with a fully-distributed, K8s-native architecture. That positioning is the core of its identity. If you are evaluating it, you are likely dealing with a workload that has outgrown a simple library like FAISS or a single-node store.
Architecture: Compute and Storage Separation
The key architectural decision in Milvus is the separation of compute and storage. The README states that the distributed architecture separates compute and storage, allowing independent scaling of query nodes and data nodes. Query nodes handle read-heavy workloads, while data nodes handle write-heavy workloads. This is a stateless microservices design on Kubernetes, which enables quick recovery from failures. The system also supports replicas, which load data segments on multiple query nodes to improve fault tolerance and throughput. This separation is not just a scalability feature; it changes how you plan capacity. You can add query nodes without touching storage, and vice versa. The trade-off is operational complexity. Running a distributed system with multiple node types and coordinators is more involved than running a single database process. The README mentions coordinator HA, which implies that coordinators are a separate component that can fail and recover, adding another layer to manage.
Getting Started: From Lite to Distributed
Milvus offers multiple deployment paths, which is a strength. For a quick start, you can install the Python SDK with `pip install -U pymilvus`. Even lighter, you can install `pymilvus[milvus-lite]` and create a local vector database by instantiating a client with a local file name: `client = MilvusClient("milvus_demo.db")`. That gives you a single-file database for development. For production, you connect to a deployed Milvus server by specifying a URI and token: `client = MilvusClient(uri="<endpoint>", token="<credentials>")`. The README also references a standalone Docker installation, which sits between Lite and the full distributed mode. The API surface is consistent across these modes, so code written against Lite can be pointed at a server later. That is a practical migration path, but be aware that the deployment mode changes performance characteristics. Lite is not a substitute for the distributed version under load.
Index Types and Hardware Acceleration
Milvus supports a range of index types: HNSW, IVF, FLAT (brute-force), SCANN, and DiskANN, along with quantization-based variations like IVFPQ and mmap support. This breadth lets you match the index to your data size and latency requirements. FLAT is exact but slow at scale; HNSW is a common approximate choice; DiskANN is for data that does not fit in memory. The README also mentions GPU indexing, specifically NVIDIA's CAGRA from the RAPIDS cuVS library. That is a notable feature for workloads that can afford GPU resources. The README names CAGRA as the GPU index; check the index documentation for which other indexes support GPU acceleration and the expected speedup. For an engineer, the choice of index is not a minor detail; it affects recall, latency, and memory footprint. Milvus gives you options, but you must understand the trade-offs yourself.
Multi-tenancy and Storage Tiers
Milvus supports multi-tenancy through isolation at the database, collection, partition, or partition key level. The README claims this allows a single cluster to handle from hundreds to millions of tenants. That range is wide, and the actual limit depends on how you configure isolation. The README also mentions hot/cold storage: frequently accessed data can live in memory or on SSDs, while colder data sits on cheaper storage. This is a cost optimization, but it adds a tiering decision. Check the documentation for how tiering is configured before relying on the cost savings.
Licensing and Governance
Milvus is distributed under the Apache 2.0 license, which is permissive for commercial use. The project is under the LF AI & Data Foundation, with Zilliz as the major contributor. That governance structure matters if you are concerned about long-term stewardship. The license allows you to modify and redistribute the code, but you should read the license text for specific obligations. The README also points to Zilliz Cloud as a managed service, which is a separate offering. That means there is a commercial path if you want to avoid self-hosting. The open-source project and the managed service are distinct. If you are evaluating Milvus for a company, the Apache license is a low-risk choice, but the governance under a foundation does not guarantee that Zilliz will not shift focus. The release history shows active maintenance, with v3.0.5 released on 2026-10-30 and v2.6.26 on 2026-10-26, indicating a dual-track release cycle.
Limitations and When It Is the Wrong Tool
Milvus is not the right tool for every vector search problem. If your dataset fits in memory on a single machine and you do not need real-time updates, a simpler in-process library like FAISS or a single-node database like SQLite with a vector extension may be enough. Milvus Lite exists for quickstarts, but it is not intended for production scale. The distributed mode is K8s-native and built from microservices, which is a significant operational burden. Check the coordinator HA documentation the README links to, and test with your own data, since the README gives no exact performance numbers for your workload. You cannot assume that Milvus will handle your workload without testing. The system also supports metadata filtering and range search, but those features can impact performance if not used carefully. If you do not need horizontal scaling or streaming ingestion, Milvus is overkill.
Alternatives and the Difference in Approach
Alternatives include other vector databases; the repository does not compare Milvus with any of them. What the README does emphasise is the compute-storage separation, which gives finer-grained scaling but adds complexity, and GPU indexing with CAGRA. The choice depends on whether you value scalability over simplicity.
Editorial conclusion
Adopt Milvus if you need a horizontally scalable vector database with real-time streaming updates and a mature ecosystem around Kubernetes. Avoid it if your workload is a small prototype where Milvus Lite or a simpler tool suffices. Before committing, verify your exact index type, GPU support, and multi-tenancy isolation level against the current documentation, and confirm that your deployment environment can handle the operational overhead of the distributed mode.
Frequently asked questions
What is Milvus used for?
It is a vector database for approximate nearest neighbour search over learned representations of unstructured data such as text, images and multi-modal information, stored alongside scalar fields such as integers, strings and JSON. Searches can be combined with metadata filtering or run as hybrid search.
Is Milvus free to use?
The open-source project is distributed under the Apache 2.0 licence and is under the LF AI and Data Foundation, with Zilliz as its major contributor. Zilliz Cloud is a separate commercial offering with Serverless, Dedicated and BYOC options.
How do I install Milvus Lite?
Install the client with pip install -U pymilvus, then install pymilvus[milvus-lite] for the embedded version. You create a local database by instantiating the client with a file name, for example client = MilvusClient("milvus_demo.db").
How do I install Milvus?
The project supports Standalone mode for a single machine deployment, and the README links a standalone Docker install guide. The repository's root docker-compose.yml defines a builder (dev-container) service that depends on etcd, minio, pulsar and Azurite; it is a build environment, not the install guide the README links.
How do I connect to a deployed Milvus server with pymilvus?
Instantiate MilvusClient with a uri pointing at the endpoint of your self-hosted Milvus server or Zilliz Cloud, and a token holding your username and password or your Zilliz Cloud API key. The client class is the same one used for the local Milvus Lite file.
Which vector index types does Milvus support?
The major index types are HNSW, IVF, FLAT for brute-force search, SCANN and DiskANN, with quantization-based variations such as IVFPQ and mmap. Milvus also supports GPU indexing, including NVIDIA's CAGRA, and optimises search for metadata filtering and range search.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/milvus-io-milvus)Star history chart for your README
[](https://hysenlabs.com/projects/milvus-io-milvus)Was this useful?