YTsaurus's readme has no install command, four CMake files, and two of its three engines named after other projects
YTsaurus is a scalable and fault-tolerant open-source big data platform.
At a glance
- What is it?
- A big data platform whose Getting Started section is two links, whose build needs CMake, Gradle and Conan at once, whose scale numbers are bare ceilings, and whose Go SDK is still on a 0.0.x version line.
- Who is it for?
- The architecture described here is coherent and the reliability claims are the right shape for the problem, but this page is an index rather than a document, and the gaps line up exactly where you would want detail. Two of the three branded engines wrap a third-party project, so the operational burden of ClickHouse and Spark is part of what you adopt.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
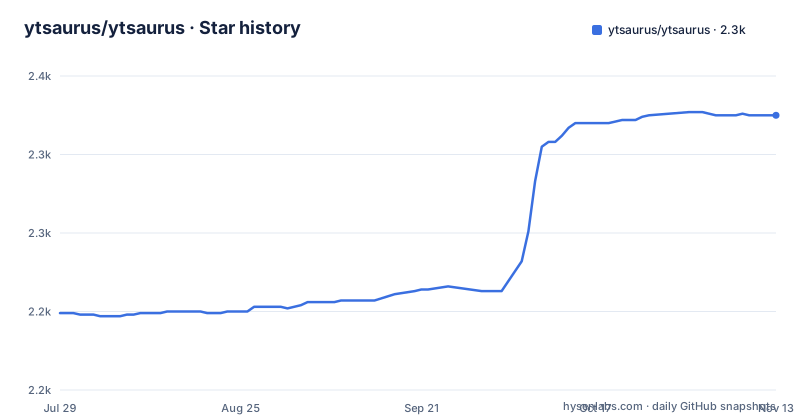
- ytsaurus/ytsaurus2,325 ★ · +126
| Repository | 2026-07-29 | 2026-11-13 |
|---|---|---|
| ytsaurus/ytsaurus | 2.2k | 2.3k |
126 Stars in the last 107 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Getting Started section is two links and no command
There is no installation command anywhere on this page.
The getting started section offers two options and both are links out: a page describing how to try a cluster on Kubernetes, and an online demo. Building from source is a link to a build document in the repository. Everything else on the page describes what the platform is and what it claims to do.
There is also no configuration section, no environment variable, no port, no credential, no default and no example of any kind. For a platform whose own selling point is a multi-tenant cluster with isolation between users, the operational entry points are somewhere else.
Count the places a reader has to go to get an answer. The project website, the documentation section of that website, the source build document, the contributor's guide, a style guide that lives inside the source tree, a long-form blog post, a video, and a chat channel. That is eight entry points, and none of them is on this page.
This is normal for a platform of this size, and it is also why the readme's own content is short enough to read in full. The judgement to make is whether the platform's documentation is as substantial as its feature list claims, and that cannot be answered from here.
Four CMake files and three build systems
The build layout is unusual enough to be worth describing before anything else.
There are five CMake files at the root of the repository. One is the default; the other four are named for a platform and an architecture pair: Linux on x86-64, Linux on aarch64, macOS on x86-64, and macOS on arm64. So the choice of build file is made by editing which file you point your build at, rather than by passing a toolchain file to one entry point.
On top of that there are two more build systems in the same tree. A Gradle wrapper with Kotlin build scripts and a Windows batch file covers the JVM side, and a Conan recipe file covers the C++ dependencies. There is also a toolchain definition for Clang and a vendored directory.
That means a source build coordinates three dependency resolvers: CMake for targets, Conan for C++ libraries, and Gradle for JVM modules, in a repository where the JVM side has a Windows wrapper and the CMake side has no Windows variant listed. For anyone building on Windows, the visible evidence says the JVM half is supported and the native half is not.
Three internal monorepo artefacts also sit at the root: a marker file for a build system the project grew up inside, plus two metadata files for an internal dependency-mapping tool. They are harmless and they are the kind of thing that never gets removed because removing it would break somebody's script.
Two of the three branded engines are named after other projects
The platform is described as four subsystems, and then three of its headline features are frameworks, two of which wrap someone else's engine.
The first is YTsaurus Flow, described as a native framework for real-time stream processing, with stateful computations for recommendation systems, complex pipeline topologies with automatic partitioning and balancing, and exactly-once processing by default. Only this one is called native.
The second is the SQL engine, which the page credits to ClickHouse by name. The claims are that it brings a well-known SQL dialect, fast analytic queries, and integration with business-intelligence tools over JDBC and ODBC. Those are good reasons to embed that particular engine, and they are also the operational reality: the SQL layer is that engine, with its own configuration, its own upgrade path and its own failure modes.
The third is SPYT, powered by Spark, offering a set of tools for writing ETL processes, the ability to launch and support several small Spark clusters at once, and what the page calls easy migration for ready-made solutions. Again the engine is named, and again it is not part of this codebase.
So of the three computation paths, one is first-party and two are integrations. That is a reasonable design, and it is the single most important thing to know before estimating what running this means.
The advantages are capacity ceilings with nothing behind them
The list of advantages is four headings with bullets under them, and the bullets are numbers without workloads.
The scalability section claims up to a million CPU cores and thousands of GPUs, exabytes of data across hard drives, solid-state drives, non-volatile memory and RAM, tens of thousands of nodes, and automated scaling of servers up and down. None of those comes with a configuration: no node shape, no replication factor, no object size distribution, no query shape.
That is not dishonest. Capacity ceilings are exactly what a platform's own documentation should state, and a figure with no workload behind it is a ceiling rather than a benchmark. It does mean a reader cannot turn any of them into a sizing decision, and that the difference between a ceiling and a demonstrated result is the entire question when you are choosing between platforms.
The same applies to the multitenant claim. Supporting large numbers of users is stated as something that eliminates multiple installations and streamlines hardware usage, which is a claim about operational cost, not about density.
The reliability section is different in kind and stronger for it: no single point of failure, automated replication between servers, and updates with no loss of computing progress. Those are architectural statements about design, and a design claim can be checked by reading the code, which is more useful than an unsourced number.
The Go client is on a zero version and the release lines do not relate
The three most recent releases are three different components on three different version schemes, and the tag names encode the component.
The Python client is at 0.13.55, tagged with a path that names the language and the component. The Go client is at 0.0.35, tagged with its own path. The Flow framework is at 0.3.0, tagged with its own name. None of them shares a numbering scheme with the others, and none of them appears to be the platform itself.
The Go client is the one to look at closely. A version of 0.0.x under semantic versioning means no part of its interface is promised to be stable, and the patch number is in the thirties, which is a long way from a first release. Anyone planning to write a service against the Go client is making a bet on an interface that has already changed shape many times.
The Python client at 0.13.x is in a different position: past the initial churn, but still short of a 1.0 that would promise a stable surface.
The cadence, though, is the reassuring part. The Python client and Flow both shipped within a day of each other at the start of October, and the Go client about a week earlier, so the components are moving independently and often rather than in lockstep. That is the right shape for a platform with this many pieces, and it is why reading a single version number tells you nothing about the whole.
Isolation is claimed three times and explained zero times
Read the two sections that touch security and count what is actually said.
The multitenant section says the platform supports large numbers of users, which eliminates multiple installations and streamlines hardware usage. The rich functionality section lists secure isolation for compute resources and storage among the platform's features. The first paragraph of the readme describes the platform as fault-tolerant.
Three adjacent claims, and not one sentence anywhere on the page about how isolation works. There is no statement about whether a user can see another's files, whether compute jobs are confined to the account that submitted them, whether the SQL layer enforces per-user permissions on tables, or whether the key-value store namespaces are a security boundary or a convenience.
The same is true of the storage side. Exabytes across four media and tens of thousands of nodes describe the shape of the data, not its protection. The repository has a certificates directory and a security file, which tells you both are taken seriously somewhere, but the readme is where someone evaluating multi-tenancy would look first.
This is the one gap I would not paper over in a review. A platform whose main economic argument is running many tenants on shared hardware has to make its isolation story legible, and this page does not.
The query language and its function library are directories in the tree
The SQL engine is described as a subsystem with a dialect, and the repository layout shows what that means concretely.
There is a directory named for the query language and a separate directory that appears to be its function library, alongside the core source directory, a command-line wrapper and its configuration file at the root, a connectors directory, a contributed-code directory, a developer tools directory, and a build directory.
So the language is not an implementation detail of the engine. It is a first-class part of the repository, with what looks like a user-extensible library beside it. For a platform that offers a SQL engine borrowed from another project, having the dialect and its function set in-tree is the part that makes it yours.
The command-line wrapper and its configuration at the repository root are the other clue to how this is meant to be operated. A multi-component distributed system with a config file checked in at the root is a system where the cluster is described somewhere, and that somewhere is not this readme.
The contributor's guide points at a style guide stored inside the source tree, which is the older convention and a deliberate one for a C++ project of this size: the rules for writing code live next to the code rather than on a website.
Editorial conclusion
The architecture described here is coherent and the reliability claims are the right shape for the problem, but this page is an index rather than a document, and the gaps line up exactly where you would want detail. Two of the three branded engines wrap a third-party project, so the operational burden of ClickHouse and Spark is part of what you adopt. Multi-tenant isolation is claimed without a mechanism, and the Go client is pre-1.0. Read the docs site before the readme, and size it against the capacity claims as ceilings rather than as results.
Frequently asked questions
What is YTsaurus?
A distributed storage and processing platform for big data, released under Apache-2.0 and written mainly in C++. It includes a MapReduce module, a distributed file system, a NoSQL key-value store, a SQL query engine and a job scheduler, plus three named computation frameworks.
How do I try YTsaurus?
The readme links two options and shows no commands: a page describing how to try a cluster on Kubernetes, and an online demo. Building from source goes through a build document in the repository. There is no installation command or configuration on the readme page itself.
Which computation engines does YTsaurus include?
Three named frameworks: YTsaurus Flow, described as native, for real-time stream processing with exactly-once by default; a SQL engine powered by ClickHouse, offering a familiar dialect, fast analytic queries and JDBC and ODBC access for BI tools; and SPYT, powered by Apache Spark, for ETL processes across multiple small clusters.
What versions are the YTsaurus clients at?
The recent releases show the Python client at 0.13.55, the Go client at 0.0.35 and the Flow framework at 0.3.0, each tagged with a path or name identifying the component. The Go client being on a zero version line means it offers no stability promise for its interface.
Does YTsaurus isolate tenants from each other?
The readme claims secure isolation for compute resources and storage among its features, in a section about supporting large numbers of users. It does not describe the mechanism anywhere on the page, so what protects one account's data and jobs from another has to be read in the documentation rather than here.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ytsaurus-ytsaurus)Star history chart for your README
[](https://hysenlabs.com/projects/ytsaurus-ytsaurus)Was this useful?