Prebuilt Flash Attention Wheels: A Distribution Layer for a Painful Build
Project brief: Provide with pre-build flash-attention 2 and 3 package wheels on Linux and Windows using GitHub Actions.
At a glance
- What is it?
- This repository publishes prebuilt flash-attention 2 and 3 wheels for Linux and Windows, covering CUDA and PyTorch combinations that upstream does not ship. The build pipeline is the real product, and it comes with infrastructure costs.
- Who is it for?
- Adopt this repository if you use flash-attention on Linux x86_64, Linux ARM64, or Windows and want to skip a multi-hour compile for CUDA and PyTorch versions that upstream does not publish. Skip it if you need a formally maintained package with guaranteed long-term support, or if your environment sits outside the documented version matrix.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
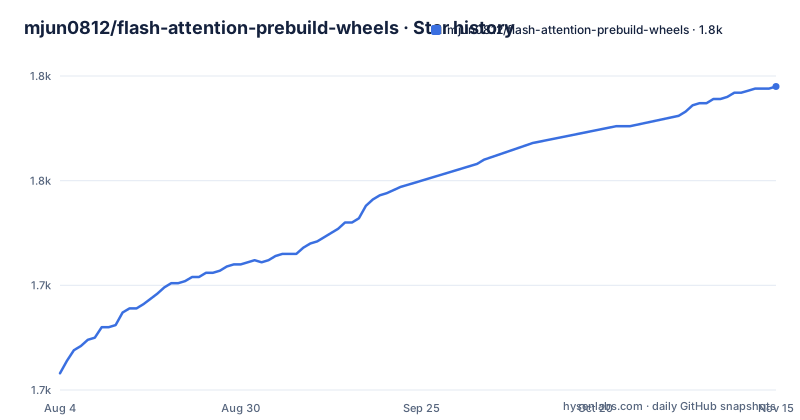
Star history
- mjun0812/flash-attention-prebuild-wheels1,795 ★ · +137
| Repository | 2026-08-04 | 2026-11-15 |
|---|---|---|
| mjun0812/flash-attention-prebuild-wheels | 1.7k | 1.8k |
137 Stars in the last 103 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Build Bottleneck It Removes
Compiling flash-attention from source is slow and resource-hungry. The README states this plainly: building takes a very long time and is resource-intensive. That cost repeats for every combination of CUDA and PyTorch you need, and upstream does not distribute wheels for all of them. This repository fills that gap by publishing prebuilt wheels for flash-attention 2 and, since v0.8.0, flash-attention 3. The intended user is an engineer who needs a specific flash_attn version paired with a specific CUDA and PyTorch release, and who does not want to spend hours waiting for a local compile. It also covers Windows, which is a less common target for this library. The repository is not a fork of flash-attention itself; it is a distribution layer that builds and hosts the artifacts.
What the Wheel Naming Convention Tells You
Each wheel file encodes its full dependency matrix in the filename. The pattern is flash_attn-[version]+cu[CUDA]torch[PyTorch]-cp[Python]-cp[Python]-linux_x86_64.whl. The README gives the concrete example flash_attn-2.6.3+cu124torch2.5-cp312-cp312-linux_x86_64.whl, which maps to Python 3.11, CUDA 12.4, PyTorch 2.5, and flash_attn 2.6.3. Since v0.5.0, the local version label also appears in pip list output, so an installed package shows as flash_attn==2.8.3+cu130torch2.9 instead of a bare version. That label makes it possible to distinguish builds that differ only in their CUDA or PyTorch backend. The naming convention is strict, and you must match every component exactly. A mismatch between the wheel's torch version and your installed torch will likely cause import errors at runtime, though the README does not describe what those errors look like.
Installation: Direct, Local, or via the Search Page
The README documents three installation paths. The first is a direct pip install from a release URL, for example pip install https://github.com/mjun0812/flash-attention-prebuild-wheels/releases/download/v0.0.0/flash_attn-2.6.3+cu124torch2.5-cp312-cp312-linux_x86_64.whl. The second is to download the wheel with wget and install it locally. The third is to browse a search page at mjunya.com/flash-attention-prebuild-wheels, the packages documentation, or the GitHub releases page to find the exact wheel you need. The README does not mention using pip's index or any package manager integration; you must know the exact version string in advance. That is a manual process, but it is also predictable. There is no dependency resolution beyond what pip does with the wheel itself, so you are responsible for installing the matching torch and CUDA runtime.
Coverage: 854 Wheels and What 100% Means
The README includes a coverage table generated from the build matrix. As of the latest release, it lists 521 Linux x86_64 wheels, 174 Linux ARM64 wheels, and 159 Windows wheels, for a total of 854, with 0 missing in each category. The table claims 100% coverage, but that percentage is relative to the matrix the repository defines, not every possible flash-attention version. The matrix is a curated set of combinations the maintainer chose to build. The README does not specify how the matrix is generated or how often it is updated. The coverage table is a useful at-a-glance check, but you still need to confirm your exact combination exists in the release assets. The ARM64 coverage is notably smaller than x86_64, which suggests the maintainer prioritizes the most common platform.
Flash Attention 3 and Platform Constraints
Since v0.8.0, the repository also builds flash_attn_3 wheels. The README notes that Flash Attention 3 requires Hopper (SM90) or newer GPUs and CUDA 12.3 or later. That is a hard hardware requirement, not just a software version. If you are on an Ampere or older GPU, you cannot use those wheels at all. The Linux wheels built since v0.7.0 use the manylinux2_28 platform tag, which the README states is compatible with old glibc versions (<=2.17). That matters for older Linux distributions. The Windows wheels are built on windows-2022, and the README does not state a minimum Windows version, so you should assume a recent Windows 10 or 11. These constraints mean the repository is not a universal drop-in; it is tied to specific platform and hardware generations.
Build Infrastructure: Self-Hosted Runners and AWS CodeBuild
The repository does not rely solely on GitHub-hosted runners. The README explicitly mentions a self-hosted runner and AWS CodeBuild for building wheels. The build environment table lists GitHub-hosted ubuntu-22.04 for Linux x86_64 and ARM64, windows-2022 for Windows, plus self-hosted Linux and Windows runners, and AWS CodeBuild for Windows. The maintainer asks for sponsorship to keep this infrastructure running. That is a practical concern: the wheels exist because someone pays for compute time. The README also credits a sponsor for providing computing resources. This means the availability of future wheels depends on continued funding and volunteer effort. If the infrastructure goes away, the release pipeline stops, and the existing wheels remain but no new versions appear.
Self-Build Option: Fork and Trigger a Workflow
If the exact wheel you need is missing, the README describes a self-build path. You can fork the repository, optionally set up a self-hosted runner, edit create_matrix.py to set the desired versions, and then push a tag like v*.*.* to trigger the build workflow. The README warns that some version combinations may not build successfully, particularly on GitHub-hosted runners due to job time limits. For those cases, a self-hosted runner is required. That is a real limitation: you cannot assume every combination will compile even with this pipeline. The self-build process is not zero-configuration; you need to understand the matrix script and have access to a runner that can finish the job. This option is most useful for an organization that already runs its own CI and wants to produce a custom wheel without maintaining a full build system from scratch.
Maintenance, Licensing, and What to Verify
The repository is BSD-3-Clause licensed, which is permissive, but it only covers the build scripts and metadata, not the flash-attention code itself. The upstream flash-attention project has its own license, and you should check that separately if you redistribute the wheels. The release history shows a steady cadence: v0.9.52 in July 2026, v0.9.49 in mid-July, and v0.9.48 in early July. That suggests active maintenance, but it is a single-person effort, as the acknowledgments list individual sponsors. The README does not document an upgrade path or migration notes between wheel versions. Before adopting it, verify that your target wheel exists in the release assets, that the local version label matches your torch build, and that the platform tag (manylinux2_28) is compatible with your glibc. The coverage table is a good starting point, but it is not a guarantee for every conceivable environment.
Editorial conclusion
Adopt this repository if you use flash-attention on Linux x86_64, Linux ARM64, or Windows and want to skip a multi-hour compile for CUDA and PyTorch versions that upstream does not publish. Skip it if you need a formally maintained package with guaranteed long-term support, or if your environment sits outside the documented version matrix. Before relying on it, verify that your exact Python, CUDA, PyTorch, and flash_attn versions appear in the release assets or the packages page, and confirm the wheel's local version label matches your torch build. The repository is a one-person distribution effort, so check the last release date and the coverage table before depending on it in production.
Frequently asked questions
How do I check which flash-attention build is installed?
Since v0.5.0 the wheel's local version label carries the CUDA and PyTorch versions, so pip list shows something like flash_attn==2.8.3+cu130torch2.9 rather than a bare 2.8.3. Before v0.5.0 two builds of the same release were indistinguishable in that output.
Which platforms does flash-attention-prebuild-wheels cover?
The coverage table reports 590 wheels for Linux x86_64, 207 for Linux ARM64, 189 for Windows, all at 100.0% with nothing missing, and 15 for Linux x86_64 with ROCm at 60.0% with 10 combinations missing. The totals are 1,001 existing against 10 missing.
How do I install a wheel from flash-attention-prebuild-wheels?
Pick the four variables, Python, CUDA, PyTorch and flash_attn version, find the matching filename in the packages document or the releases list, then install from the URL or download the file and pip install it. The two examples printed in the readme use a placeholder release tag of v0.0.0, which predates the local version label scheme, so they are illustrations rather than commands to run.
Why do the ROCm wheels carry a git hash in the version?
Because RDNA support is not in a Flash Attention 2 release tag yet, so those builds come from an upstream commit. The wheel version is a release plus a short commit hash, which means pip cannot resolve it by version alone and it has to be installed from a file or a constructed URL.
What are the requirements for the flash_attn_3 wheels?
Flash Attention 3 wheels have been available since v0.8.0 and require Hopper, meaning SM90, or newer GPUs and CUDA 12.3 or later. They are published as flash_attn_3, which is a different distribution name from flash_attn.
Can I build a flash-attention wheel that is not in the index?
Yes, by forking the repository, optionally setting up a self-hosted runner, editing create_matrix.py with the versions you want, and pushing a v*.*.* tag to trigger the workflow. GitHub-hosted runners are said to be unable to build some combinations because of job time limits, which is what the self-hosted runner is for.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mjun0812-flash-attention-prebuild-wheels)Star history chart for your README
[](https://hysenlabs.com/projects/mjun0812-flash-attention-prebuild-wheels)Was this useful?