NeMo RL: NVIDIA's Post-Training Toolkit for GRPO and Beyond, with a Narrow Hardware Lane
Project brief: Scalable toolkit for efficient model reinforcement. [04/06/2026] New Model Support Added support for Qwen3.5 dense and MoE models (LLM and VLM) for GRPO training.
At a glance
- What is it?
- NeMo RL is a Python library for large-scale reinforcement learning on LLMs and VLMs, supporting GRPO, DAPO, and other algorithms. It targets serious multi-GPU clusters, not single-GPU experimentation.
- Who is it for?
- Adopt NeMo RL if you already run NVIDIA GPUs at scale, need GRPO or DAPO for dense or MoE LLMs, and can commit to its Docker container and config-driven workflow. Skip it if you want a lightweight library for a single GPU or a quick hackathon prototype.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
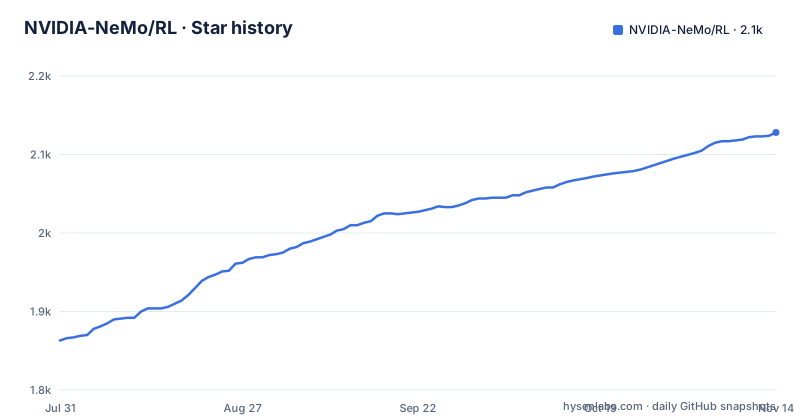
- NVIDIA-NeMo/RL2,128 ★ · +265
| Repository | 2026-07-31 | 2026-11-14 |
|---|---|---|
| NVIDIA-NeMo/RL | 1.9k | 2.1k |
265 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What NeMo RL Actually Does
The library is written in Python and licensed under Apache-2.0. The repository is active, with a v0.7.0 release in July 2026. The documentation lives at docs.nvidia.com, which suggests a formal support structure. The README emphasizes reproducibility through YAML config files, and it links to guides for reproducing specific models like Nemotron-3-Super. That is the core promise: you can take a recipe, run it on your cluster, and get a model that matches a published result. That is a strong claim, and the project backs it with detailed guides, but the guides are not in the README itself. You have to follow the links to see the actual commands.
The Architecture: Backends, Parallelism, and Rollouts
The data flow is visible in the recipe names and the news items. For GRPO, you sample a group of responses for each prompt, compute rewards, and update the policy to increase the likelihood of high-reward responses. The library adds variants like DAPO, which modifies GRPO with clip-higher and dynamic sampling to stabilize training. The README also mentions chunked cross entropy loss and Yarn long-context training, which are implementation details for handling long sequences and large vocabularies. The architecture is clearly modular, with separate components for the policy, the rollout backend, and the reward computation. But the README does not give a full diagram. You have to infer the flow from the config files and the algorithm names.
Getting It Running: Containers and Config Files
The library supports LoRA for SFT, GRPO, and DPO on both backends. That means you can fine-tune adapters instead of full weights, which reduces memory and storage. The README lists specific LoRA recipes, such as grpo-nanov3-30BA3B-2n8g-fsdp2-lora.yaml. So the workflow is not just full fine-tuning. You can start with LoRA to validate a task, then scale to full fine-tuning if needed. The config files are the entry point, and they are dense with parallelism settings. If you are not familiar with Megatron's parallelism options, the learning curve is steep.
Model Support and the Speed of Day-0 Releases
The flip side is that model support is not universal. The README does not claim to support every model on Hugging Face. If your model is not in the list, you may need to write custom code or wait for a release. The Day-0 support for Minimax-M3 is on a separate branch, not the main branch, so you have to switch branches to use it. That is a sign that the main branch is stable but not always the newest. The library is evolving fast, which is good for features but bad for stability. The README itself shows a branch for MuseGlimmer RL support, which is not yet merged into main.
A Real Limitation: The Hardware and Complexity Barrier
Another limitation is the reliance on the NGC container. The README does not offer a source install or a conda environment. If you are behind a firewall or cannot pull from NGC, you are stuck. The container is also tied to NVIDIA's software stack, which may conflict with your existing environment. The README does not discuss debugging or error handling. You are expected to know what you are doing. For a team that wants to experiment with RL post-training, this is a heavy lift. A simpler tool like TRL from Hugging Face might be easier for a first experiment, but it will not scale to the same degree.
Alternatives: TRL and veRL, and the Difference in Approach
Another alternative is to use the underlying Megatron Core directly, without the RL layer. That gives you full control but requires you to implement the RL algorithm yourself. NeMo RL saves you that effort, but it also imposes its own abstractions. The trade-off is between convenience and flexibility. NeMo RL is a high-level library, but it is high-level in the sense of managing parallelism, not in the sense of hiding complexity. You still need to know what GRPO is and how to design a reward function.
Maintenance and Upgrade Cost, and Licence Notes
The upgrade cost is not just about code. The library is closely tied to NVIDIA's hardware and software stack. If you switch to a different GPU vendor, the library may not run. That is a lock-in risk. The README does not discuss portability. For a team that values vendor neutrality, that is a concern. The Apache-2.0 license does not prevent you from modifying the code, but you would have to replace the underlying backends to run on non-NVIDIA hardware, which is a major effort.
Editorial conclusion
Adopt NeMo RL if you already run NVIDIA GPUs at scale, need GRPO or DAPO for dense or MoE LLMs, and can commit to its Docker container and config-driven workflow. Skip it if you want a lightweight library for a single GPU or a quick hackathon prototype. Before adopting, verify that your exact model is in the supported list (Qwen3.5, GLM-4.7-Flash, Nemotron family, etc.), confirm your cluster matches the recipe's parallelism settings (e.g., ep16tp2cp2), and test the container on one node first, since the README offers no CPU-only or minimal-GPU path.
Frequently asked questions
What is NVIDIA-NeMo/RL used for?
It is a post-training library for models, described as ranging from one GPU to thousands and from tiny models to those above a hundred billion parameters. It supports supervised fine-tuning, direct preference optimisation, reward modelling, grouped relative policy optimisation, policy optimisation variants, vision-language training, distillation, and low-rank adaptation, with recipes published per model.
Which Python versions does nemo-rl support?
Python 3.13.14 and above but below 3.14. That is a patch-level lower bound inside a single minor series with the next minor version excluded, so the constraint is narrower than most packages in the ecosystem.
Why does nemo-rl declare a torch range instead of a pin?
Because the backend extras were built against different framework versions, one group at 2.13.0 and another at 2.11.0, and each resolves in its own conflict fork, so the base requirement has to admit both. The comment in the dependency list says the ceiling exists to stop the environment drifting on a relock.
Are nemo-rl Docker images published?
Yes. Both 64-bit and ARM64 Linux containers are published on the NVIDIA container registry, tagged to match the release, with the first official container appearing at version 0.4.0. The library is also installed from the package index as `nemo-rl`.
Does nemo-rl support low-rank adaptation?
Across six combinations. Supervised fine-tuning, grouped relative policy optimisation, and direct preference optimisation are each supported on two backends, with a pull request reference and recipe files for three model and parallel-layout configurations.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvidia-nemo-rl)Star history chart for your README
[](https://hysenlabs.com/projects/nvidia-nemo-rl)Was this useful?