Fast-dLLM ships four sub-projects, and the structure diagram documents two of them
Official implementation of "Fast-dLLM: Training-free Acceleration of Diffusion LLM by Enabling KV Cache and Parallel Decoding"
At a glance
- What is it?
- Four acceleration techniques for diffusion language, vision and action models sharing one repository, four papers and one conference heading, distributed as code directories plus three model weights on a Hugging Face account. No releases, no test suite, and the only open roadmap item is support for one serving engine.
- Who is it for?
- Pick the one project that matches your problem and ignore the rest, because that is how the repository is organised even though the front page presents all four as one family. If you already run Dream or LLaDA and want speed without retraining, the training-free path is the interesting one, and its evaluation command turns the cache on explicitly, which is the entire contribution in a single flag.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 168 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
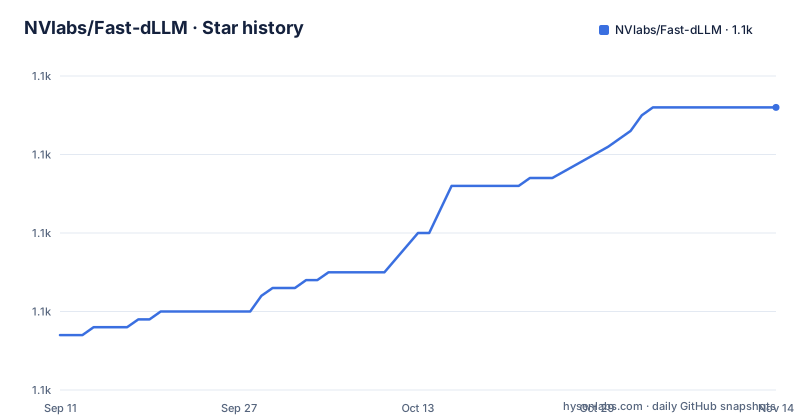
Star history
- NVlabs/Fast-dLLM1,116 ★ · +29
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| NVlabs/Fast-dLLM | 1.1k | 1.1k |
29 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four sub-projects, four papers, and no releases at all
The page opens with a table that compares four things rather than describing one project. Version 1 is a training-free accelerator with a key-value cache and parallel decoding over the Dream and LLaDA backbones. Version 2 is block diffusion with fine-tuning on Qwen2.5 plus hierarchical caching. Fast-dVLM converts an autoregressive vision-language model to block diffusion with block-size annealing. Fast-dDrive adds section-aware block diffusion with scaffold speculative decoding for driving. Each points at its own arXiv entry, and the identifiers run from a 2025 paper through to a 2026 one. The repository has no GitHub releases, so there is no artifact to pin: the unit of distribution is a directory plus, for three of the four, a model on a Hugging Face account named Efficient-Large-Model, which is not the project organisation. The last push is dated 2026-05-30.
One conference heading sits above a table where only two papers have a venue
The page carries an ICLR 2026 heading directly under the badges, above the comparison table. The news list states that versions 1 and 2 were accepted by that conference, dated 2026-01-26. The two later sub-projects, the vision-language and the driving one, are announced as released with web pages, models and papers, and neither announcement mentions acceptance anywhere. So a reader arriving from a link sees a single conference badge and may reasonably assume it applies to everything in the table, when the visible text only supports it for the two oldest entries. Nothing is misstated, but the layout does the implying. The remaining news items are dated: an online demo in August 2025, a parallel-decoding strategy and a benchmark script added in July 2025, a paper update in early July, and a third-party integration in late June.
Version 1 is the only sub-project with no released model
In the model row of the table, the first column holds a dash while the other three hold links. That tracks the approach column: version 1 needs no training and therefore ships no weights, and it is also the only entry that supports two backbones. Its evaluation command makes the contribution visible in a single argument. The cache is switched on explicitly in the model arguments, alongside a diffusion step count, a token limit, and a parallel-decoding algorithm set to a confidence threshold with the threshold set to nine tenths, which is what decides how many positions are decoded at once:
cd v1
pip install -r requirements.txt

# LLaDA interactive chat
python llada/chat.py --gen_length 128 --steps 128 --block_size 32

# Dream evaluation
accelerate launch dream/eval.py --model dream \
    --model_args pretrained=Dream-org/Dream-v0-Base-7B,max_new_tokens=256,diffusion_steps=8,add_bos_token=true,alg=confidence_threshold,threshold=0.9,use_cache=true \
    --tasks gsm8k --num_fewshot 5 --batch_size 1
A block size of 32 and 128 steps in the chat script are the other two knobs that set the speed and quality trade.
The structure diagram covers two directories and stops mid-word
The project structure block is a plain text tree, and it is the weakest part of the page. It describes version 1 with its two backbone subdirectories, its own requirements file and its own readme, then version 2 with a training framework directory, fine-tuning scripts, DeepSpeed configs, a generation module, evaluation entry points, an app and a chatbot, a requirements file and a readme. The last line of the tree is a readme entry that stops after four letters, with no extension and no closing. More significantly, the three other sub-projects, the vision-language directory, the driving directory and the vendored third-party tree, appear nowhere in it, even though all three are linked in the comparison table and two of them have their own quick start further down the same page. The structure documentation covers half the repository.
Training depends on a vendored fork of the framework, with the path injected for you
Fine-tuning the vision-language model is described as using DeepSpeed together with a fork of a training framework held under the third-party directory, and the note in parentheses says the launcher sets the Python path for you. You are also told to run the fine-tuning script from the repository root. That is three instructions that all point at the same fact: the framework is vendored, not depended on. You cannot upgrade it by changing a version, and you cannot run the launcher from inside the sub-project directory. The four sub-projects also disagree about how to install themselves. Version 2 installs the directory in editable mode, while the other three install a requirements file, and the vision-language path additionally needs a dataset fetched by its own shell script before training.
Three decoding paths, and the paper's setting is only the middle one
The driving sub-project exposes three decoding strategies through a single mode argument, which is also settable as an environment variable. The names are the section-aware diffusion path, the scaffold speculative path marked as the paper's canonical setting, and an inference-scaling path built on multi-trajectory rollouts. Two of the three named options are therefore alternatives to the one the paper reports numbers for, and nothing in the quick start tells you which to use unless you read the surrounding prose. Its evaluation entry point takes its inputs as environment variables rather than flags: a model path, the path to a Waymo validation annotation file, and an image root, which is the pattern you would expect for a multi-GPU run and is easy to miss.
Every headline number in the repository, and where it came from
There are four measurable claims and they are all in the news list rather than in a results section. The driving model reports over 200 tokens per second on a single H100, up to twelve times an autoregressive baseline running with a named serving engine, and state of the art error metrics on a Waymo end-to-end benchmark. The vision-language model reports up to a 6.18 times speedup while matching quality across eleven benchmarks. The third-party integration reports inference latency falling from sixty seconds to six. None of them is accompanied by a benchmark configuration beyond a task name, a hardware model, a baseline library and a dataset. The only number that comes with a reproducible command is the third, since the integration points at a specific file in someone else's repository. The online demo sits on another laboratory's domain rather than the project site.
Editorial conclusion
Pick the one project that matches your problem and ignore the rest, because that is how the repository is organised even though the front page presents all four as one family. If you already run Dream or LLaDA and want speed without retraining, the training-free path is the interesting one, and its evaluation command turns the cache on explicitly, which is the entire contribution in a single flag. If you want a model, the other three ship weights. Before you commit, know what you are taking. There are no versioned releases, so a directory is the only unit you can pin, apart from the weights on a third-party model account. The training path depends on a vendored fork of a framework rather than a versioned dependency. And the structure diagram in the readme covers half the repository and ends mid-word, so plan to read each sub-project's own document.
Frequently asked questions
What does Fast-dLLM accelerate?
Diffusion-based large language models, vision-language models, and vision-language-action models. The repository holds four sub-projects covering training-free inference acceleration, block diffusion, direct conversion of a vision-language model, and a driving model.
What is the difference between Fast-dLLM v1 and v2?
Version 1 is training-free inference acceleration using a KV cache and parallel decoding, works with the Dream and LLaDA backbones, and ships no model. Version 2 is block diffusion with fine-tuning on Qwen2.5 and hierarchical caching, and it has a released 7B model.
Which Fast-dLLM models are released?
Three: a 7B block-diffusion language model, a 3B block-diffusion vision-language model, and the driving model. All three are hosted under the Efficient-Large-Model account rather than the project organisation.
How do I install and run Fast-dLLM v2?
Change into the v2 directory, install it in editable mode, then run the app script for a web demo or the evaluation shell script for evaluation. The other three sub-projects install from a requirements file instead.
Does Fast-dLLM support vLLM yet?
Not yet. It is the single open item in the project list, marked as in progress, alongside four completed items covering the inference and evaluation code and the training code for all four sub-projects.
What is scaffold speculative decoding in Fast-dDrive?
One of three decoding paths exposed through a mode flag: section-aware diffusion, scaffold speculative decoding as the paper's canonical setting, and inference scaling using multi-trajectory rollouts.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-fast-dllm)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-fast-dllm)Was this useful?