physical_ai_av: a devkit for a licence-gated driving dataset
Devkit and documentation for the NVIDIA Physical AI Autonomous Vehicles Dataset
At a glance
- What is it?
- physical_ai_av is NVIDIA's Python developer kit for the Physical AI Autonomous Vehicles Dataset, distributed as a pip package with a wiki and notebooks, where access depends on accepting a dataset licence agreement and authenticating against Hugging Face rather than on any credential bundled with the code.
- Who is it for?
- physical_ai_av suits an autonomous-vehicle researcher who has already decided to work with NVIDIA's multi-sensor collection and wants a supported package rather than raw file handling, since the devkit bundles the decoding and columnar dependencies that multi-sensor data implies.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 22 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
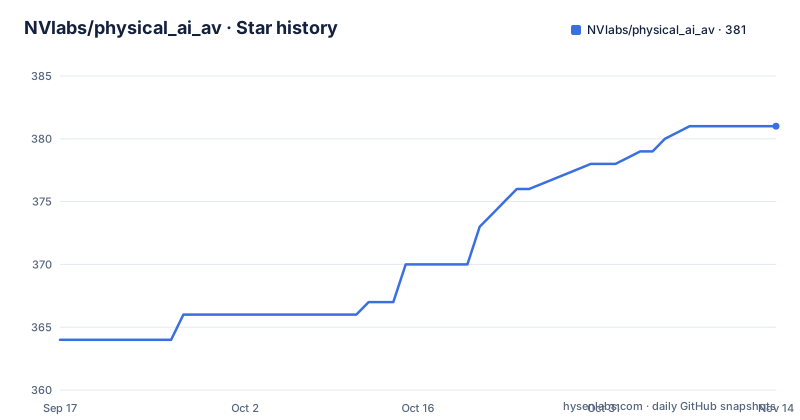
- NVlabs/physical_ai_av381 ★ · +17
| Repository | 2026-09-17 | 2026-11-14 |
|---|---|---|
| NVlabs/physical_ai_av | 364 | 381 |
17 Stars in the last 58 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The data sits behind a licence click, not a credential
The distinction worth internalising is that this package is openly installable while the data it exists to read is not freely downloadable. Installing the kit is a single command:
pip install physical_ai_avGetting at the underlying dataset requires three separate steps on the Hugging Face side. You need an account. You need to log in and agree to the NVIDIA Autonomous Vehicle Dataset License Agreement, which appears at the top of the dataset card rather than being buried in a terms page. And you need to create a user access token and pick an authentication method. That ordering is deliberate and it tells you something about the dataset's status: it is gated, and the gate is a licence acceptance tied to an identity, not an API key you generate and move on from. For a driving dataset containing multi-sensor recordings, that is the expected posture. The practical consequence is that the devkit cannot be evaluated end to end without a decision about licence terms, so treat the agreement as the first task rather than something to click past when a download fails.
Three support routes, and only one of them is public
The support section is unusually explicit about routing, and the split matters if you are about to file something. Usage questions and general discussion about the dataset and the devkit belong on the Alpamayo developer forum, not in the issue tracker, which keeps usage questions from burying actual defects. Bugs, documentation problems, and feature requests go to GitHub issues using one of three provided templates, so the reporter picks the right one and the triage metadata travels with the report. There is a detail there that most projects would leave manual: the relevant NVIDIA responder is assigned automatically through an assignees field on the template, so you are not choosing a maintainer and the routing is not at the mercy of whoever reads the queue first. Security vulnerabilities are the third route and the strictest one, going to NVIDIA's vulnerability disclosure program rather than the public tracker, with an explicit instruction not to file security issues publicly. Three channels, three audiences, and one of them is off the repository entirely.
The dependency list describes the data shape
There are seven runtime dependencies and they describe what the dataset actually contains. A video decoding library at a fairly recent version floor is there because multi-sensor driving data is video at its core, and decoding it in pure Python is not practical. A columnar data library appears alongside numpy and pandas, which is the signature of tabular sensor channels, annotations, and calibration tables stored for fast column access rather than loaded whole. scipy is present for the numeric work that follows, and a progress bar library for the long download and iteration phases that any multi-terabyte dataset will produce. The Hugging Face hub client is the access layer, which is consistent with the authentication requirements described earlier. Read together, the list says the dataset mixes video streams with structured sensor and annotation tables, and the devkit's job is to make both addressable rather than to do anything exotic on top of them.
Demo and dev dependencies are opt-outable groups
Beyond the runtime set, the project file separates optional work into named groups, and the distinction is a good one. The demo group carries the entire visualisation and notebook stack: a kernel, interactive widgets for scrubbing through data, a plotting library, a media player library for displaying video inline, and a headless build of the computer vision library. None of that is needed to call the devkit, and all of it is heavy, so keeping it out of the base install is the difference between a package you can depend on and one you tolerate. The dev group is smaller and more conventional, holding the test runner and the pre-commit tooling. The tool configuration then sets the default groups to all, which is convenient for contributors working inside the repository and exactly the behaviour to override if you are consuming the package from elsewhere. Being explicit about this split is also a reasonable signal about how the project expects the notebooks to be used: as the primary way to explore the dataset, not as an optional extra on top of it.
It builds with uv and lints at a hundred columns
The packaging tells you the toolchain. The build backend is a dedicated uv build backend, versioned with both a floor and a ceiling, which is a stricter constraint than most packages apply to their own build requirements and reflects the project's reliance on that ecosystem. A lock file is committed, and a Python version file pins the interpreter the project itself develops against, while the project metadata declares support for Python 3.11 and newer. Linting is handled by ruff configured to a hundred-column line length, and pre-commit hooks are wired through a configuration file at the repository root, so formatting and checks run before a commit lands rather than in continuous integration after the fact. A tests directory sits alongside the source, which for a package this size suggests the test suite is small and focused. None of this is exotic, and that is the point: for a kit whose users are researchers who will spend their time on data rather than on environment setup, a predictable modern toolchain removes a whole category of friction.
The documentation lives outside the repository
The repository itself is small and its contents reflect that. There is a source directory, a tests directory, a notebooks directory, the package configuration, a security policy, and the readme. Everything substantial is hosted elsewhere: the long-form documentation is a wiki, and the interactive notebooks are the intended way to learn the data. At version 0.2.2, this is a young package with an API that could still move, which is a reasonable reason to pin your dependency if you build something on top of it. The notebooks directory in the repository is worth checking before assuming the wiki is the only entry point, since exploratory examples sometimes live alongside the formal documentation. The overall shape to hold in mind is that you are installing a thin, well-packaged client for a large hosted dataset, and the effort is split accordingly: tooling that is small and conventional, data that is large and gated, and documentation that lives on the wiki and in notebooks rather than in the package.
Editorial conclusion
physical_ai_av suits an autonomous-vehicle researcher who has already decided to work with NVIDIA's multi-sensor collection and wants a supported package rather than raw file handling, since the devkit bundles the decoding and columnar dependencies that multi-sensor data implies. It is a poor fit for someone evaluating datasets casually, because the licence agreement and access token are a gate in front of the data rather than an afterthought, and the package itself is thin by design. Before starting, read the dataset card's licence terms to confirm the data scope suits your work, and install the demo dependency group only if you intend to run the notebooks, since the visualisation stack is what dominates the install.
Frequently asked questions
What is physical_ai_av?
A Python developer kit and documentation for working with the NVIDIA Physical AI Autonomous Vehicles Dataset. It ships as an installable package alongside a wiki and interactive notebooks.
What do I need before I can download the dataset?
A Hugging Face account, a login where you agree to the NVIDIA Autonomous Vehicle Dataset License Agreement shown at the top of the dataset card, and a user access token with a chosen authentication method.
What does the physical_ai_av devkit depend on?
Python 3.11 or newer, plus a video decoding library, the Hugging Face hub client, a columnar data library, and numpy, pandas, scipy, and tqdm. Notebook and plotting tools sit in a separate optional dependency group.
Where should I report a bug or a security issue?
Bugs, documentation issues, and feature requests go into GitHub issues using the matching template, with a responder assigned automatically. Security vulnerabilities go to NVIDIA's Vulnerability Disclosure Program and should not be filed publicly.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-physical-ai-av)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-physical-ai-av)Was this useful?